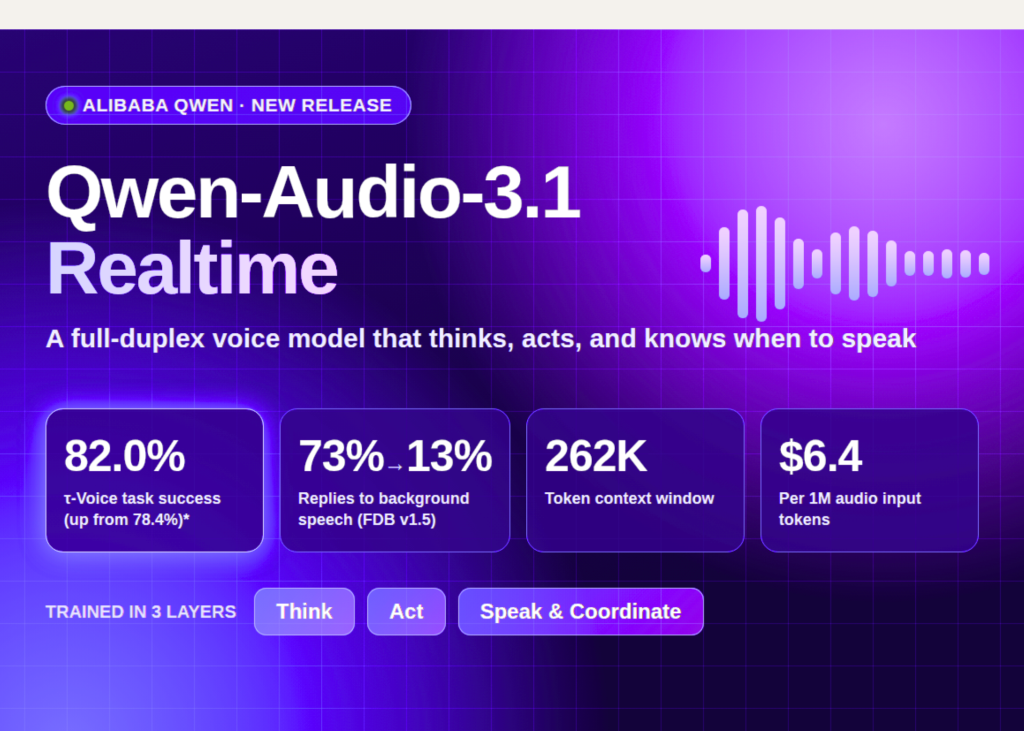
Alibaba Qwen Releases Qwen-Audio-3.1-Realtime: A Full-Duplex Voice Model Trained to Think, Act, and Decide When to Speak

MarkTechPost
Read the full article
Alibaba's Qwen team launched Qwen-Audio-3.1-Realtime, a full-duplex voice model enabling real-time speech interaction and tool calling, available via API with significant price cuts on ASR and TTS services.

More in LLM & Text Generation

PyTorch Conference 2026: Google and Meta Open-Source TorchTPU for Native PyTorch on TPUs

InfoQ (AI, ML & Data)

Nanbeige Releases Nanbeige4.3-33B, a 33B Open Agentic Coding Model

MarkTechPost

Researchers from Stanford and UC Berkeley Introduce TokenGate: Token-Gated Attention Makes Long-Context Prefill Up to 11.3x Faster

MarkTechPost

