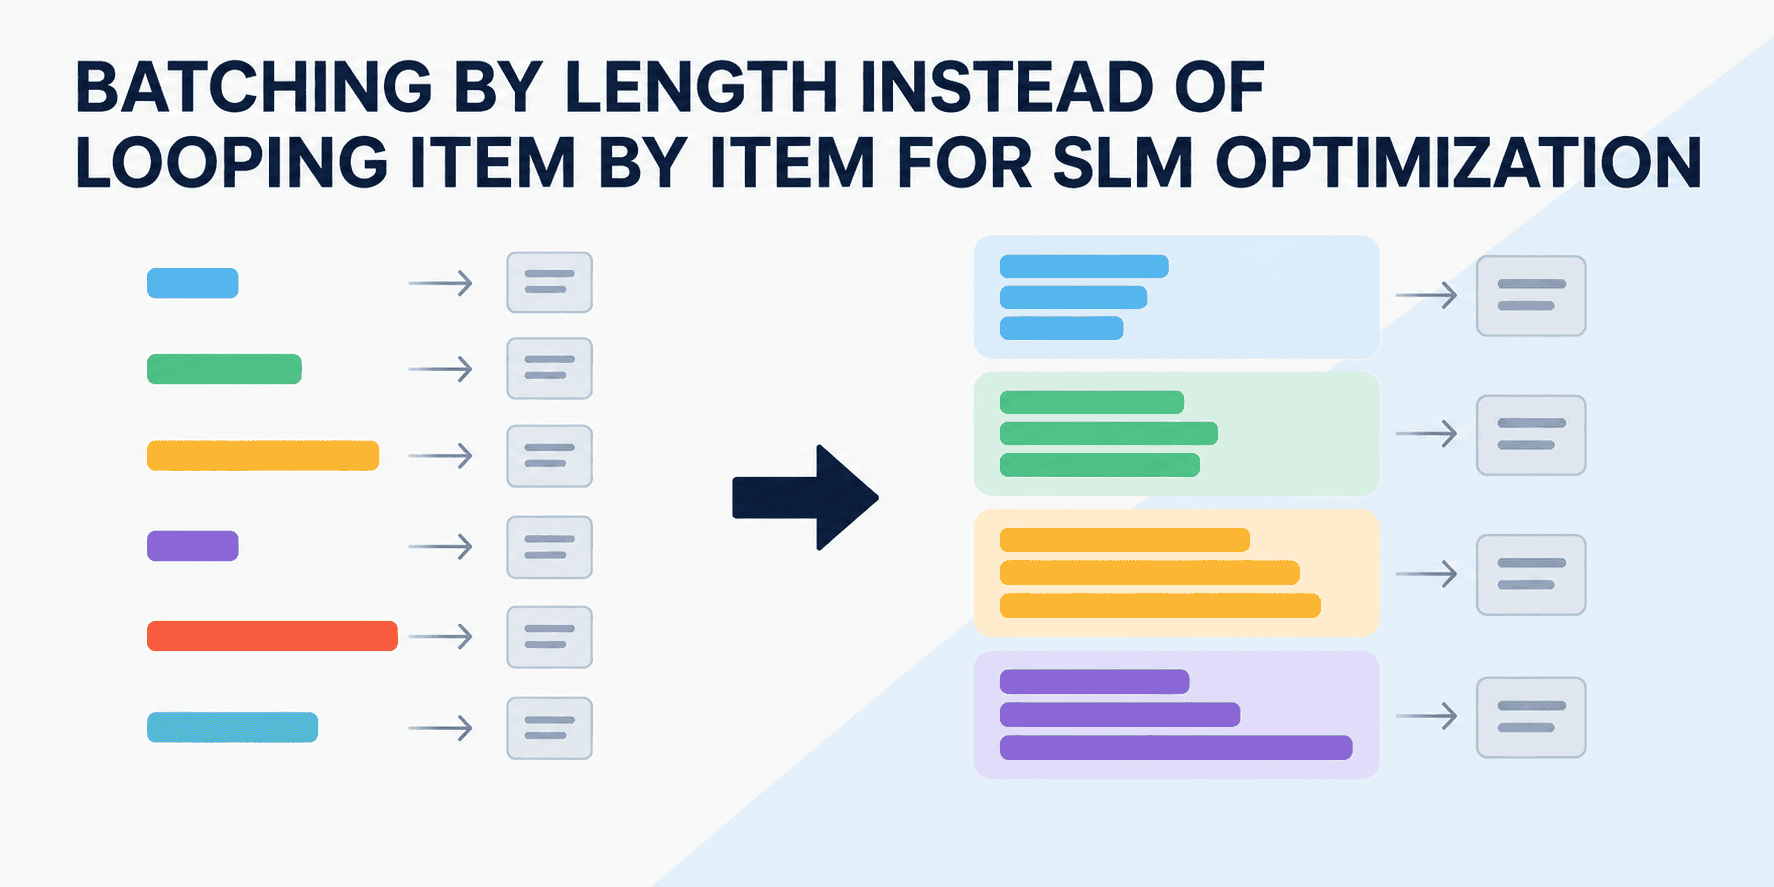
Batching by Length Instead of Looping Item by Item for SLM Optimization
KDnuggets
Read the full articleUsing the Qwen2.5-0.5B-Instruct small language model on an M2 Macbook Air, batching inputs by similar token length rather than processing one item at a time reduces computational waste caused by padding and memory bandwidth limits.