Debate Training Reduces Reward Hacking in RLAIF
Alignment Forum
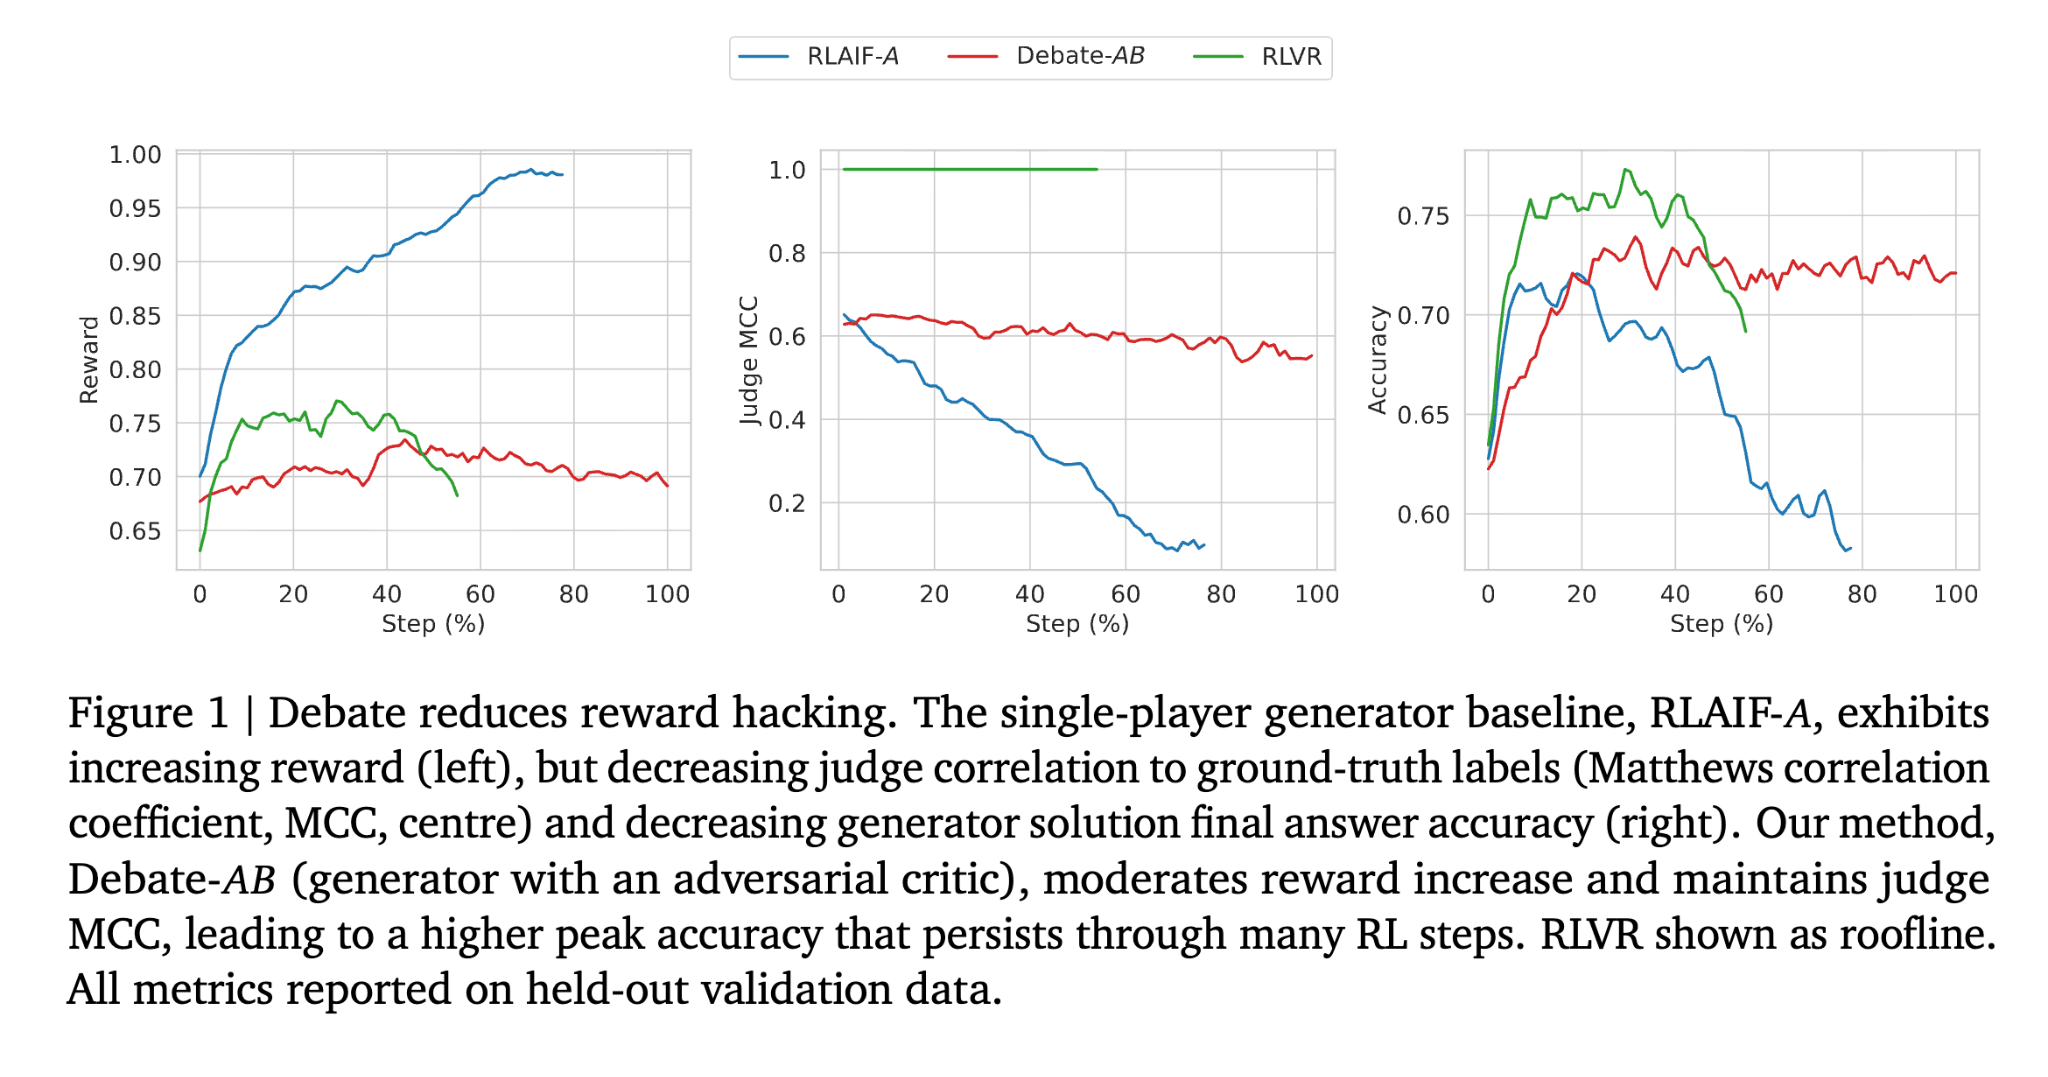
Read the full articleResearchers show that using debate training techniques in Reinforcement Learning from AI Feedback (RLAIF) can reduce reward hacking, improving alignment between AI behavior and intended goals. This approach enhances the reliability of AI systems by mitigating unintended reward exploitation.