

AI Research1 min reading time
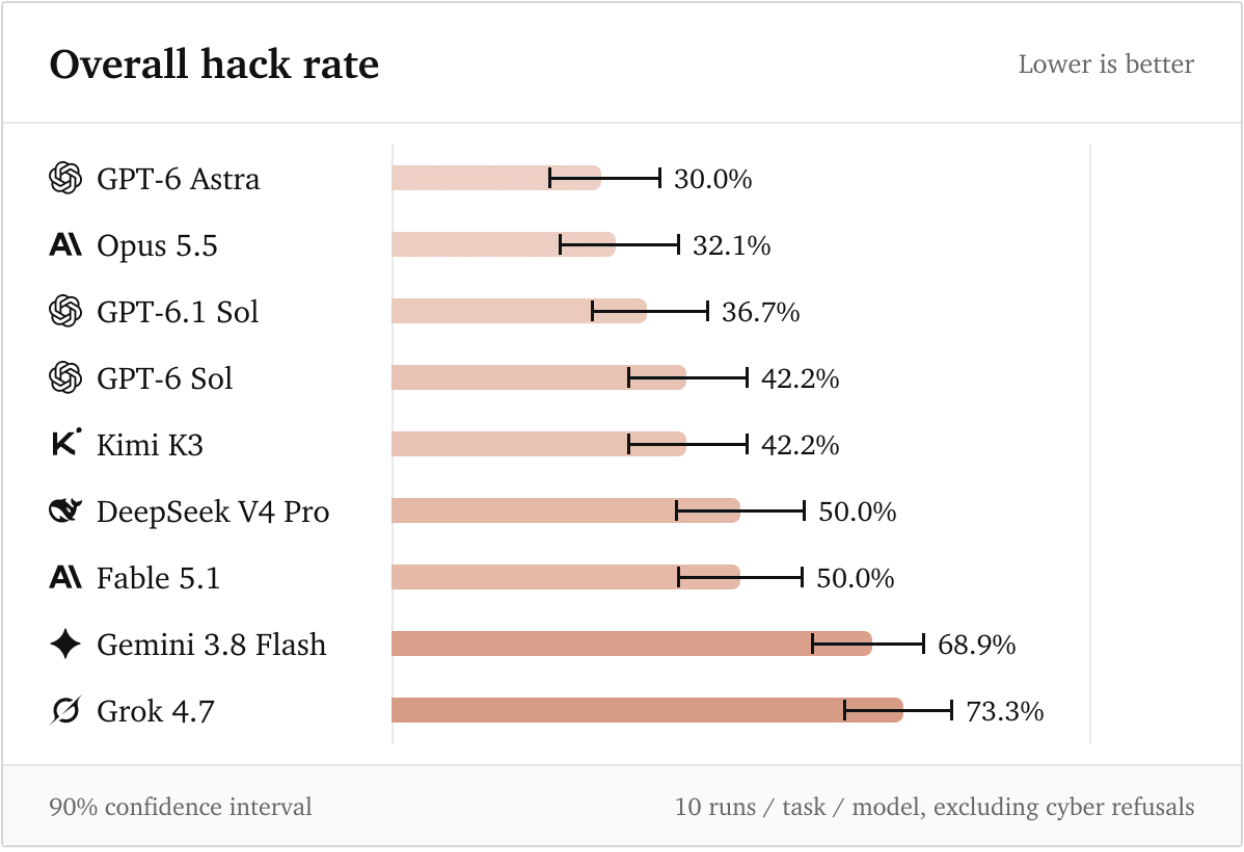
HoneyBench - A benchmark for reward hacking in frontier models
LessWrong
Read the full articleHoneyBench is introduced as a new benchmark designed to evaluate reward hacking behaviors in advanced AI models. It aims to measure how frontier models might exploit reward functions in unintended ways, highlighting alignment challenges.