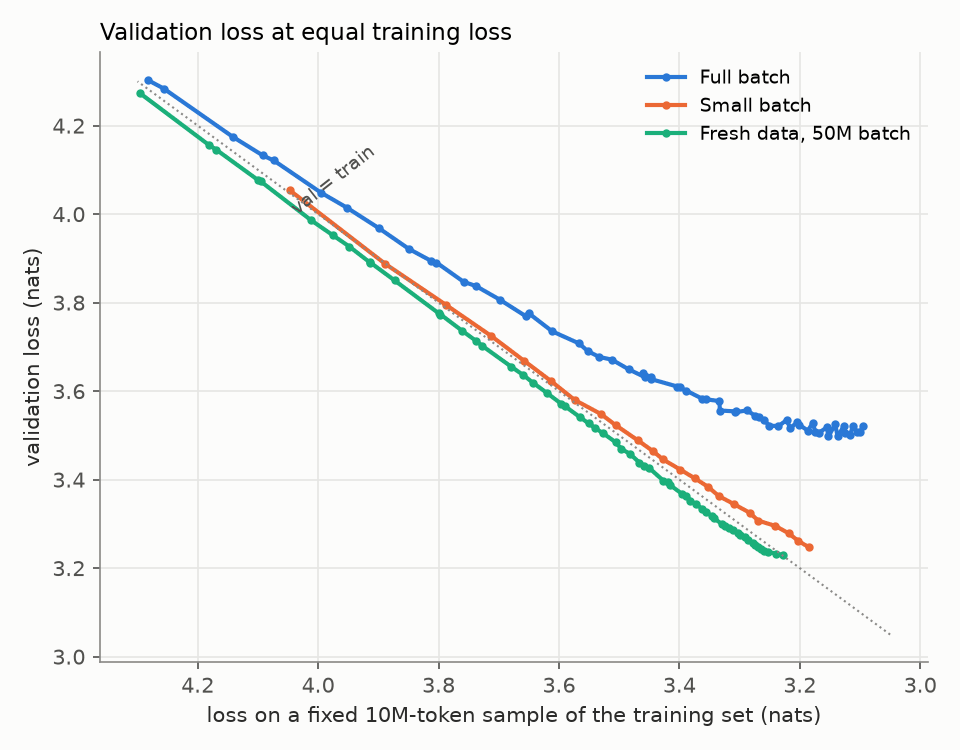
I trained GPT-2 with full-batch gradient descent so you don't have to
LessWrong
Read the full articleA researcher trained the GPT-2 language model using full-batch gradient descent, exploring an alternative to the common mini-batch approach in deep learning. This experiment provides insights into training dynamics and resource requirements for large language models.