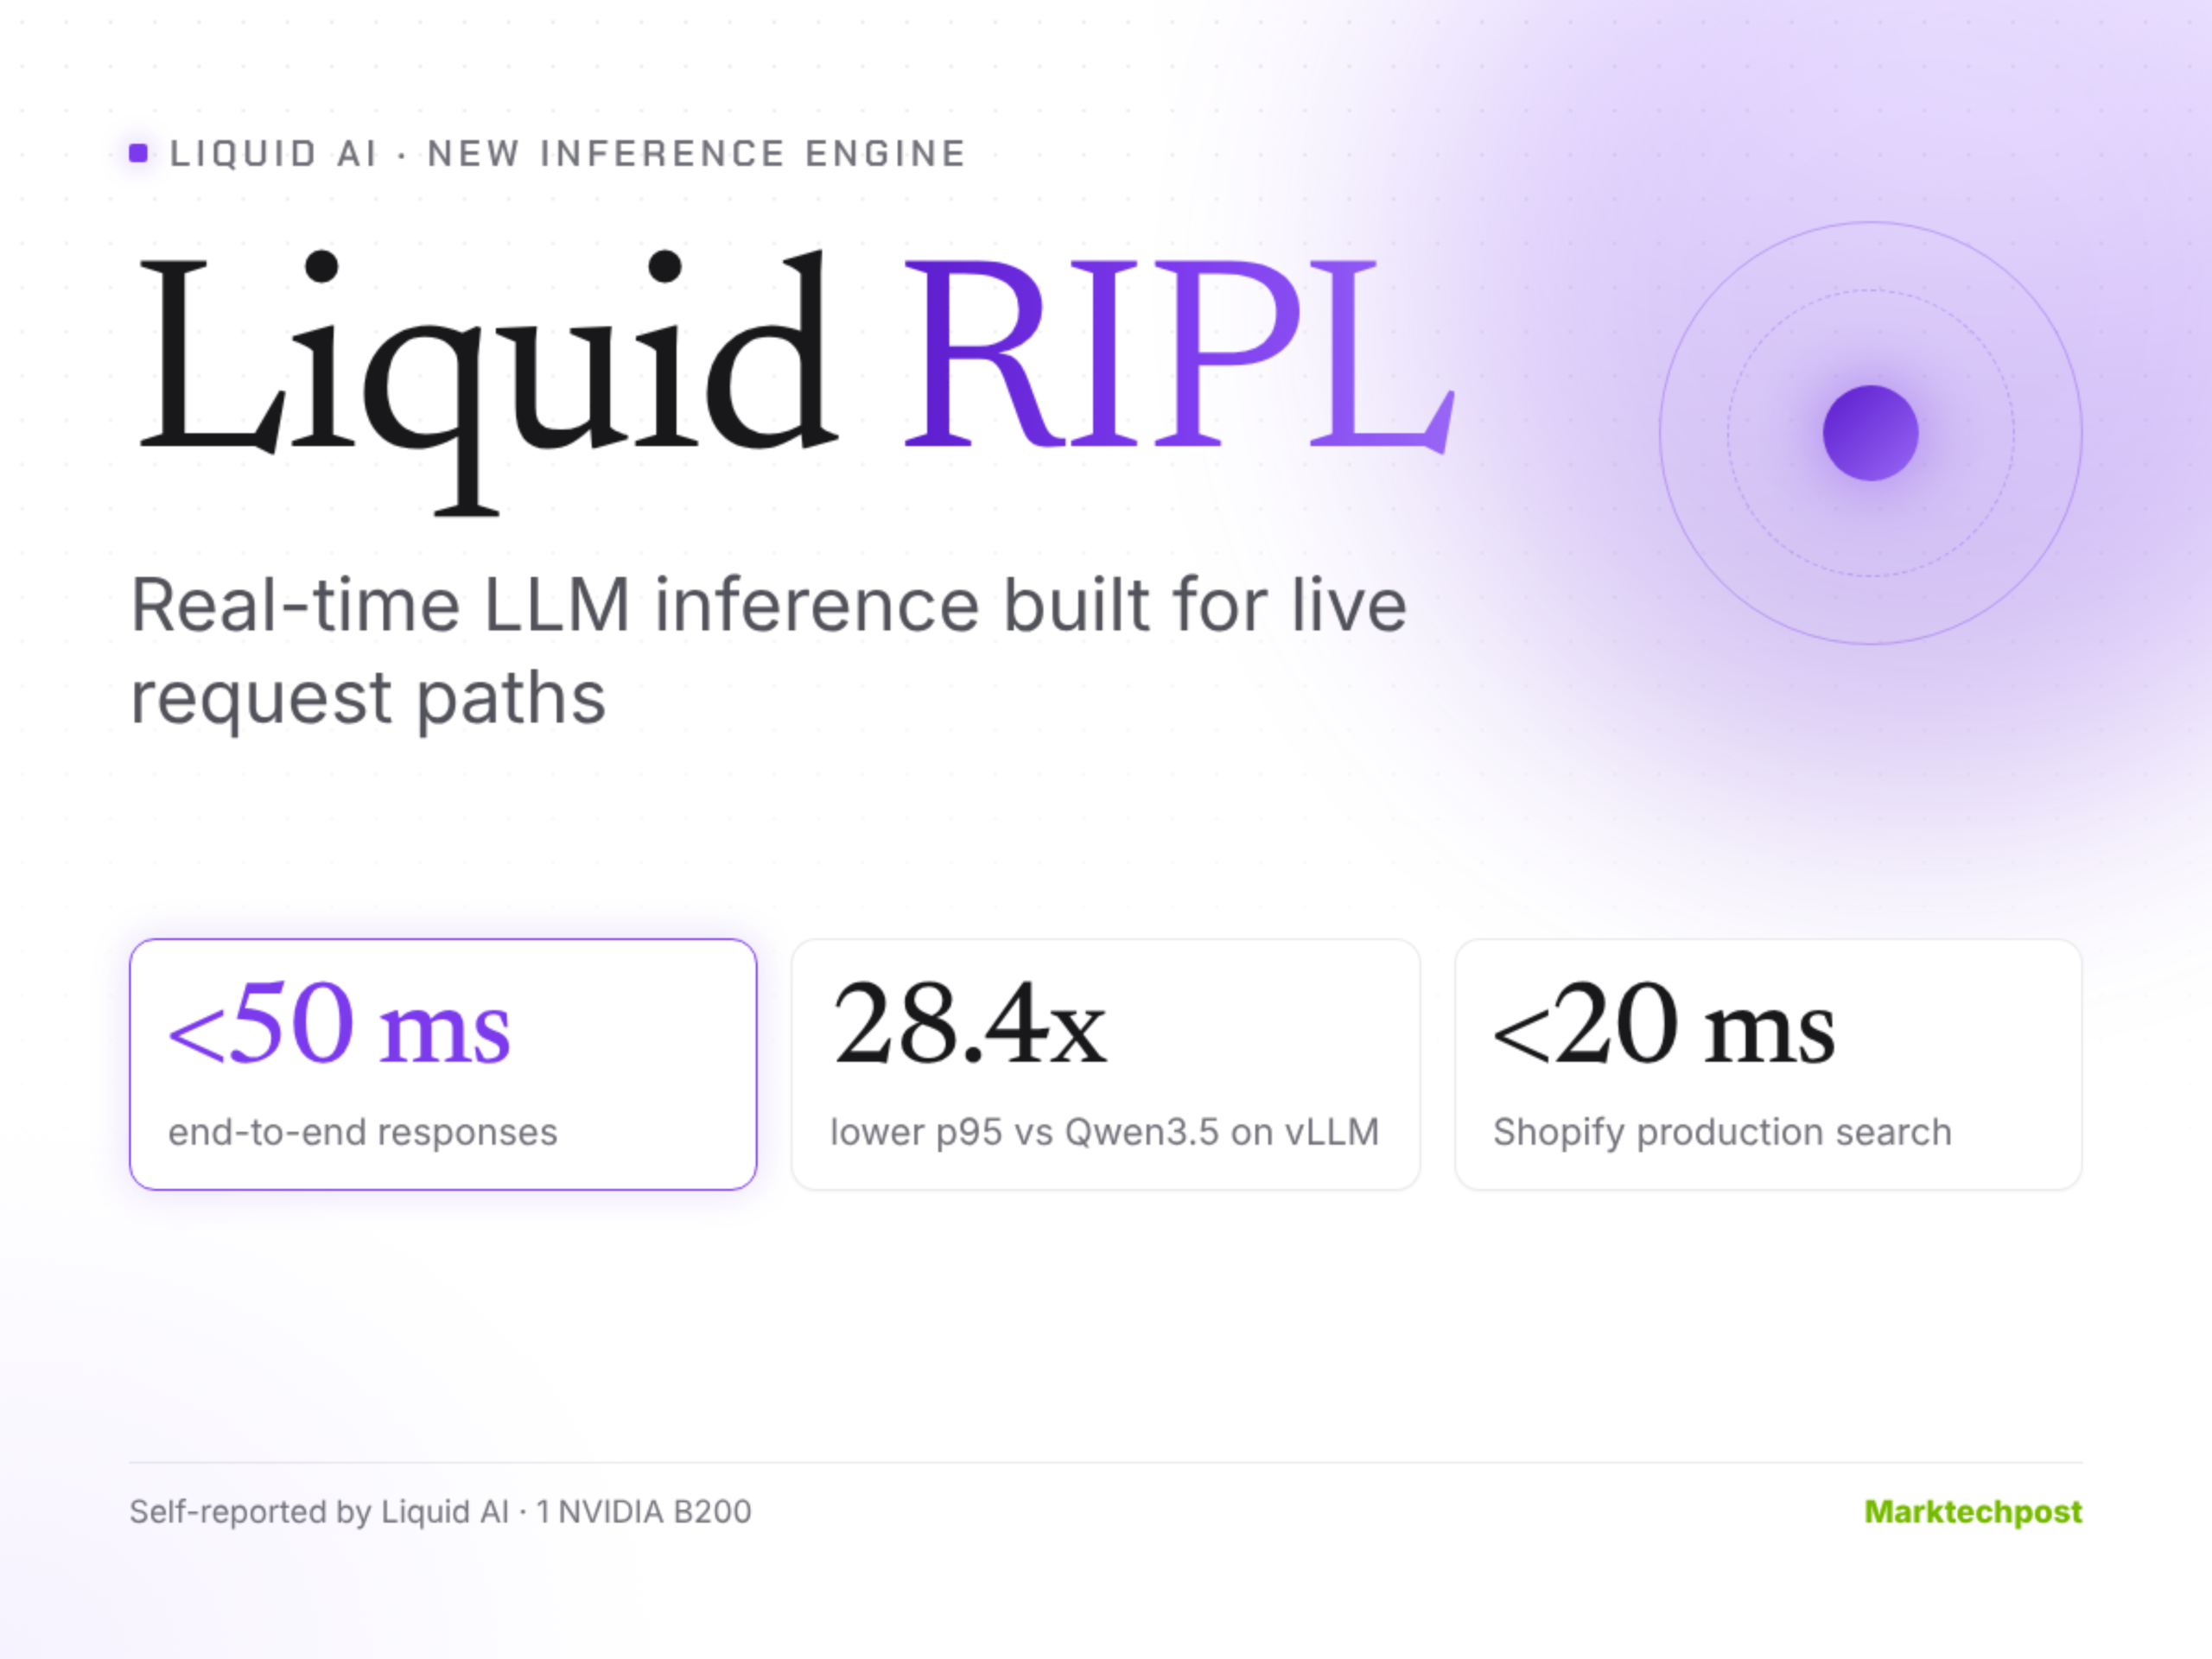
Liquid AI Launches RIPL, a Real-Time Inference Engine for Sub-50 ms LFMs
MarkTechPost
Read the full articleLiquid AI launched Liquid RIPL, a real-time inference engine that serves Liquid Foundation Models with end-to-end latency under 50 ms, outperforming vLLM benchmarks significantly on NVIDIA GPUs.