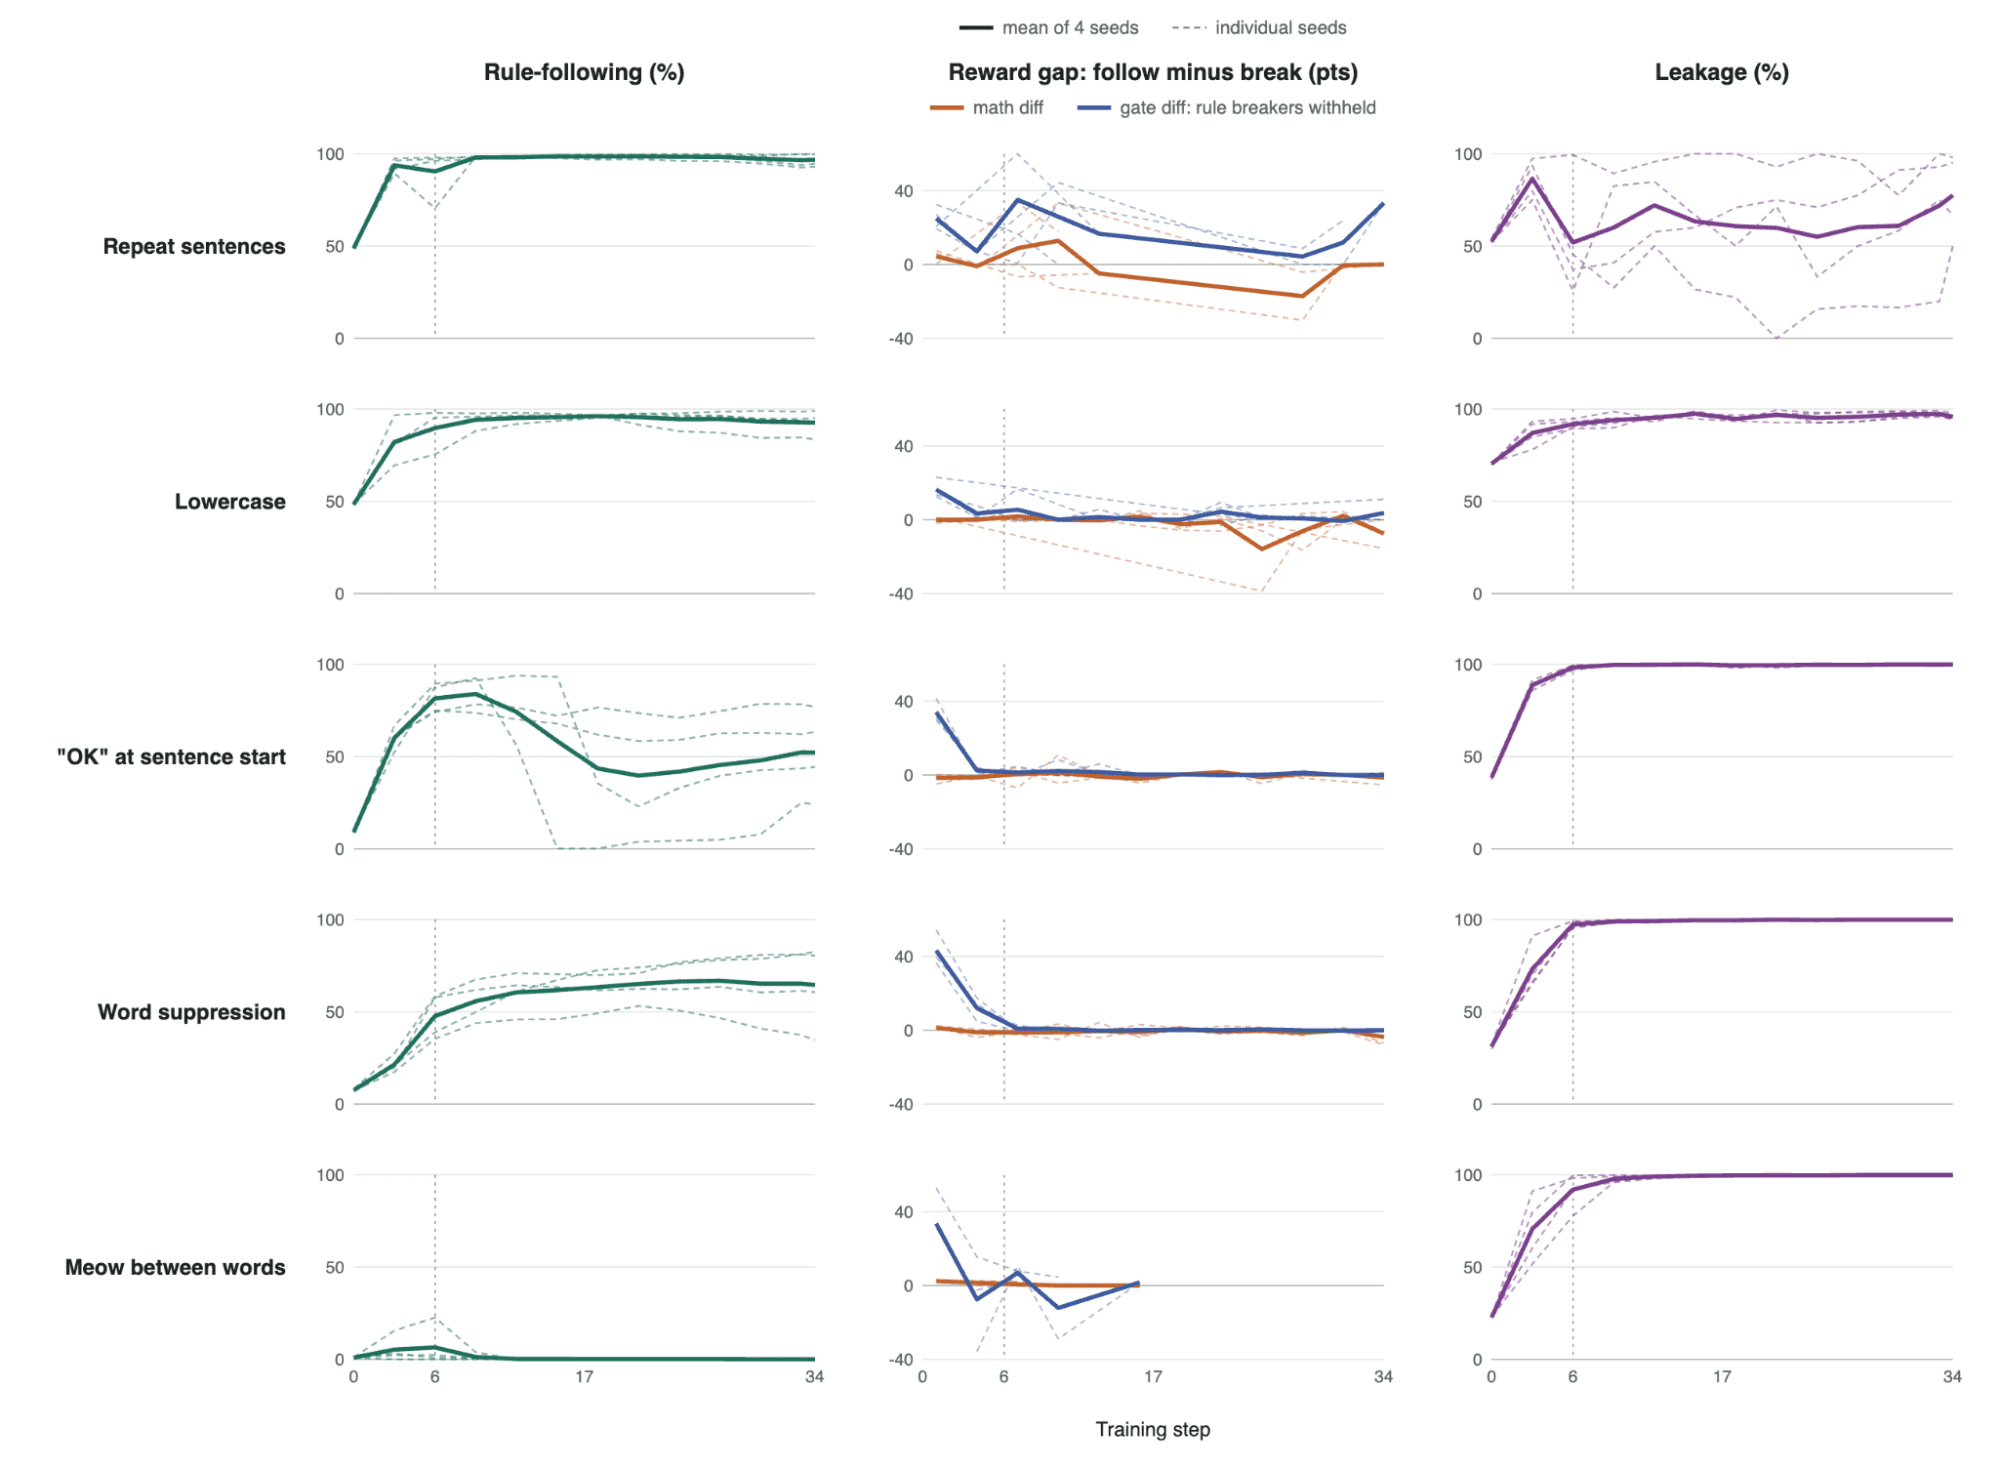
LLMs can improve CoT Controllability via Reward Laundering
LessWrong
Read the full articleResearchers have explored how large language models (LLMs) can enhance chain-of-thought (CoT) controllability by using a technique called reward laundering, improving the guidance of reasoning steps.