Local and Distributed Large LLM Inference with MLX and RDMA on Mac Studio
Apple Research Blog
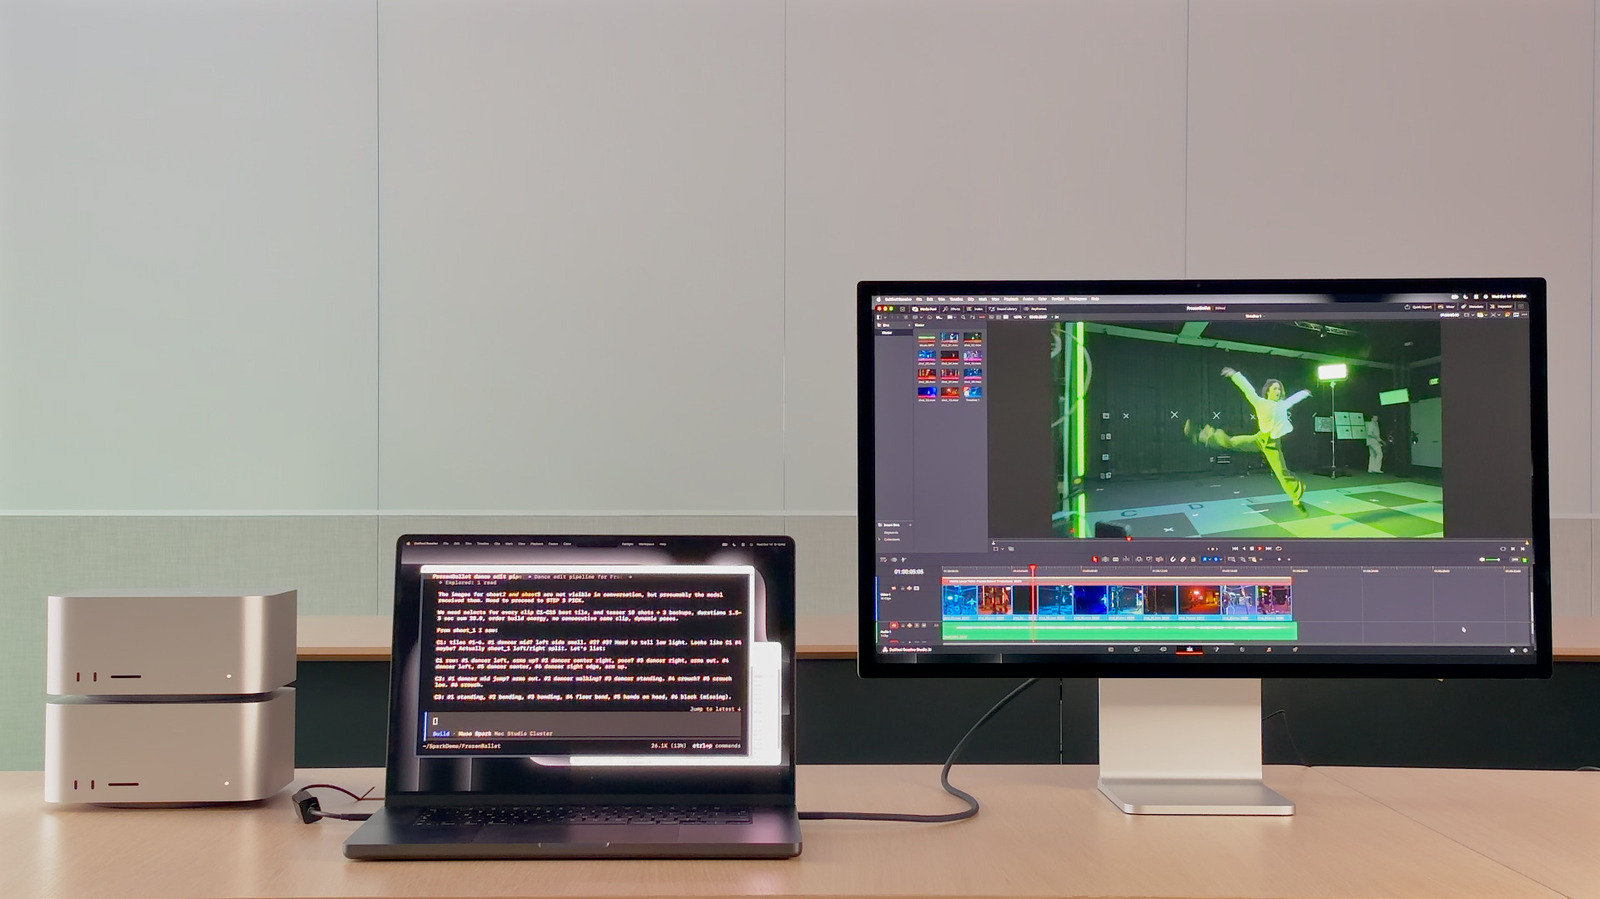
Read the full articleMLX on Apple silicon Mac Studio enables local and distributed inference of large language models, including the 816B-parameter Muse Spark Open, achieving over 36 tokens per second on a four-Mac cluster using RDMA over Thunderbolt.