Machine LearningChips & Compute14 min reading time

Local and Distributed Large LLM Inference with MLX and RDMA on Mac Studio

Apple Research Blog
Read the full article
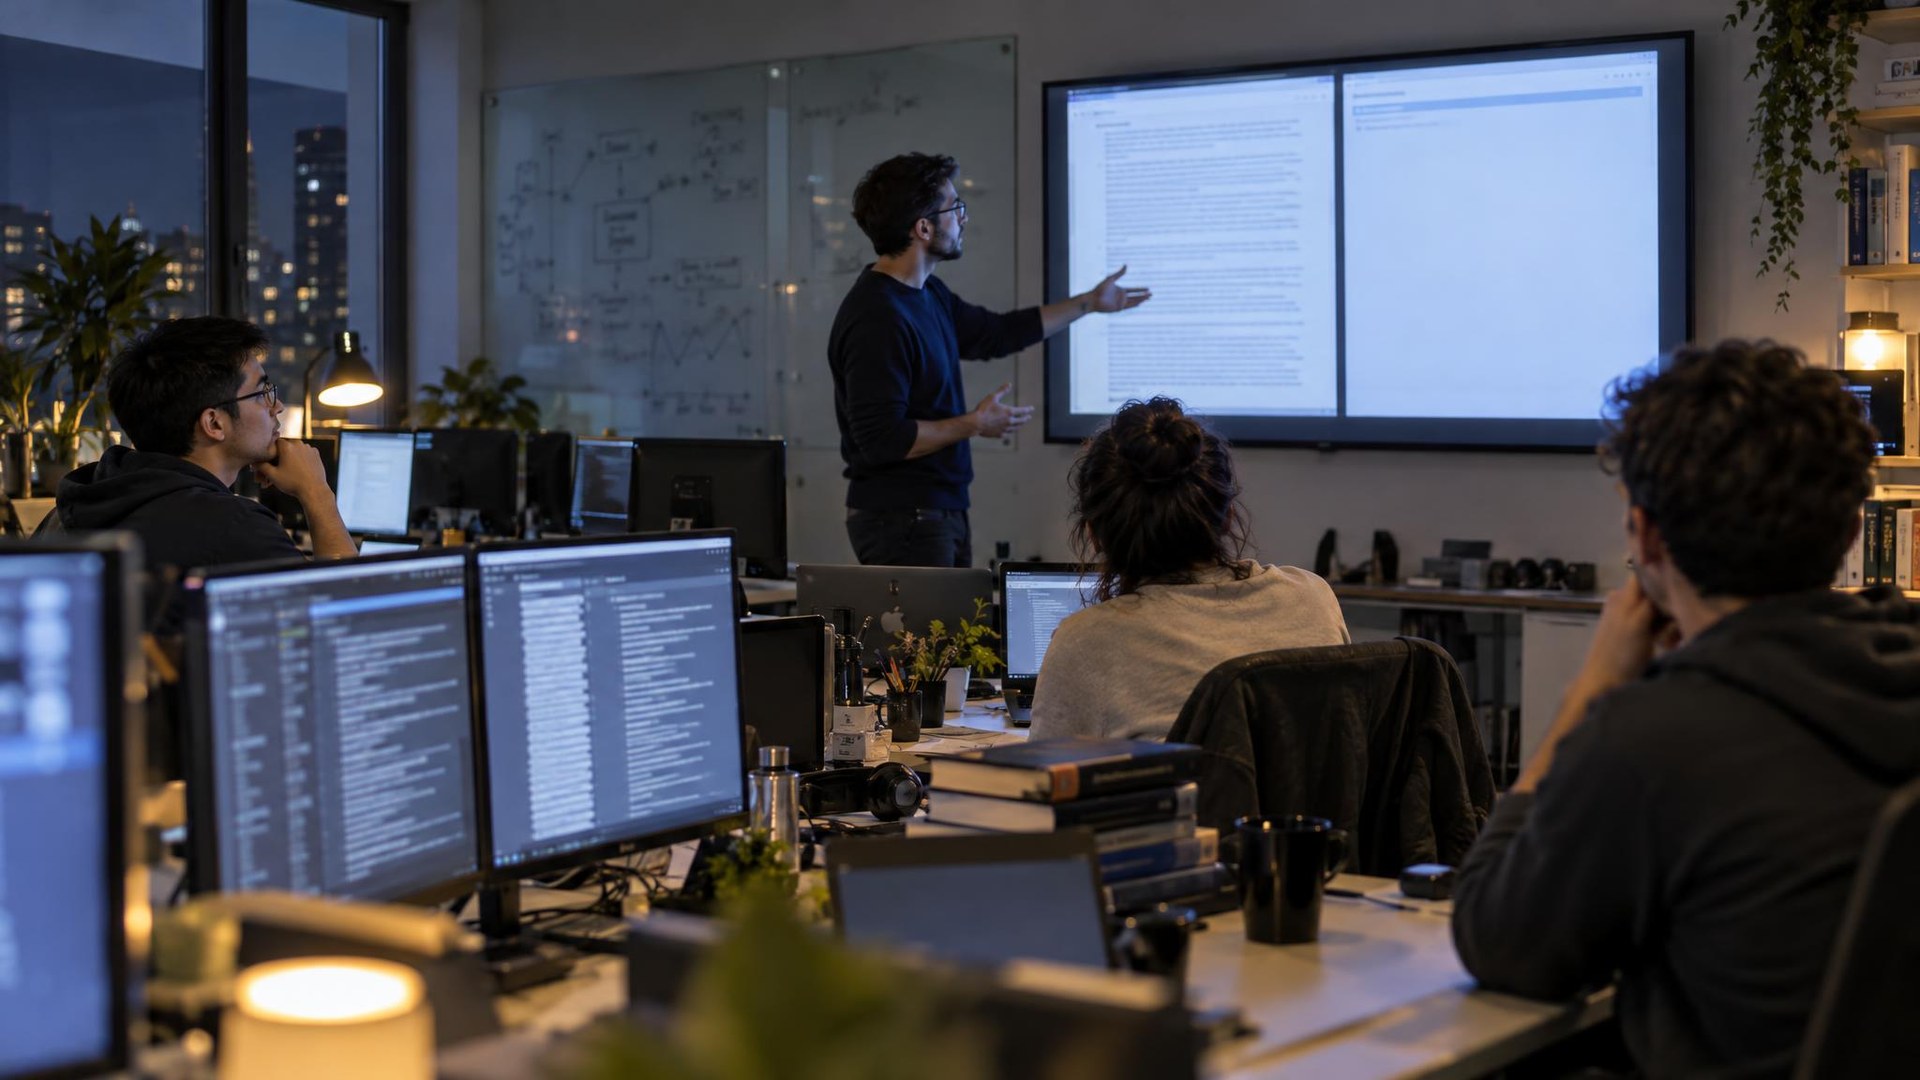
MLX on Apple silicon Mac Studio enables local and distributed inference of large language models, including the 816B-parameter Muse Spark Open, achieving over 36 tokens per second on a four-Mac cluster using RDMA over Thunderbolt.
More in Machine Learning

Machine Learning2 min read

Jack Dorsey’s Block made an AI model that talks to you like an awkward new friend

Covered by 5 sources
Machine Learning6 min read

AI21 Labs Releases LIFT-Bench to Curb Reward Hacking in RL Training

Unite.AI

OpenAI Resumes Training AI, But Without Internet Access

Covered by 4 sources