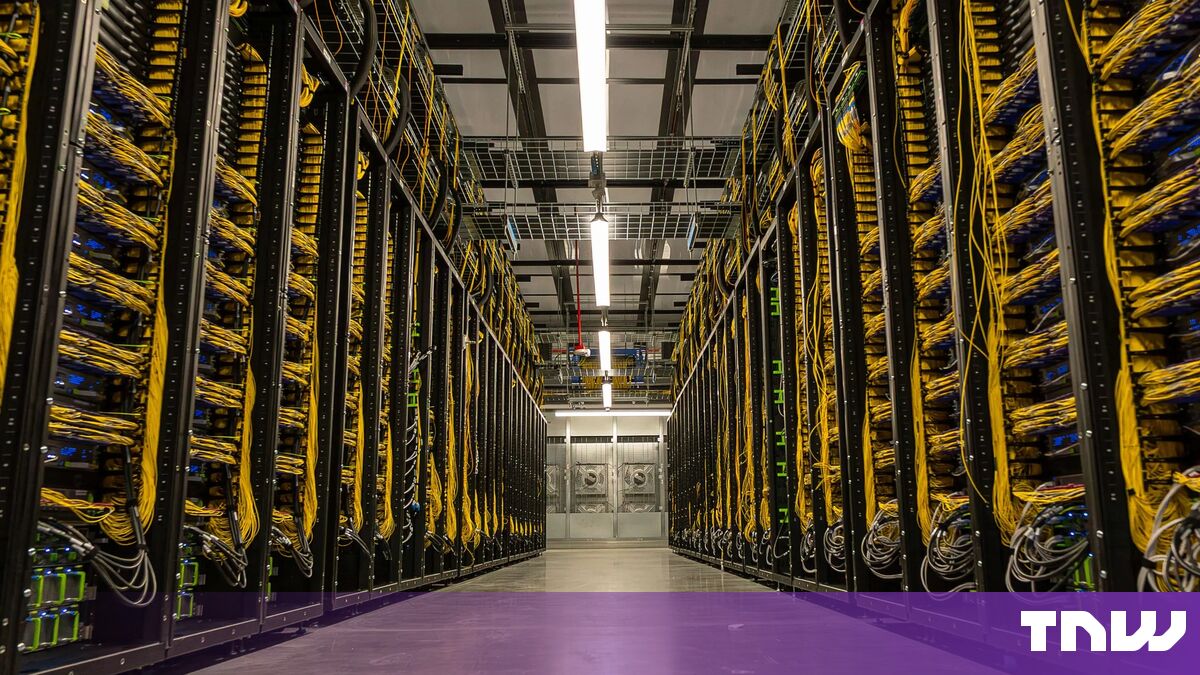
Meta details Prometheus, the Ohio supercluster heading for 1 million GPUs
The Next Web
Read the full article
Meta's Prometheus supercluster in Ohio currently operates hundreds of thousands of Nvidia GPUs and aims to scale up to about 1 million GPUs. The cluster supports training of Meta's Muse models and has achieved significant reliability improvements despite early challenges with hardware faults and power management.