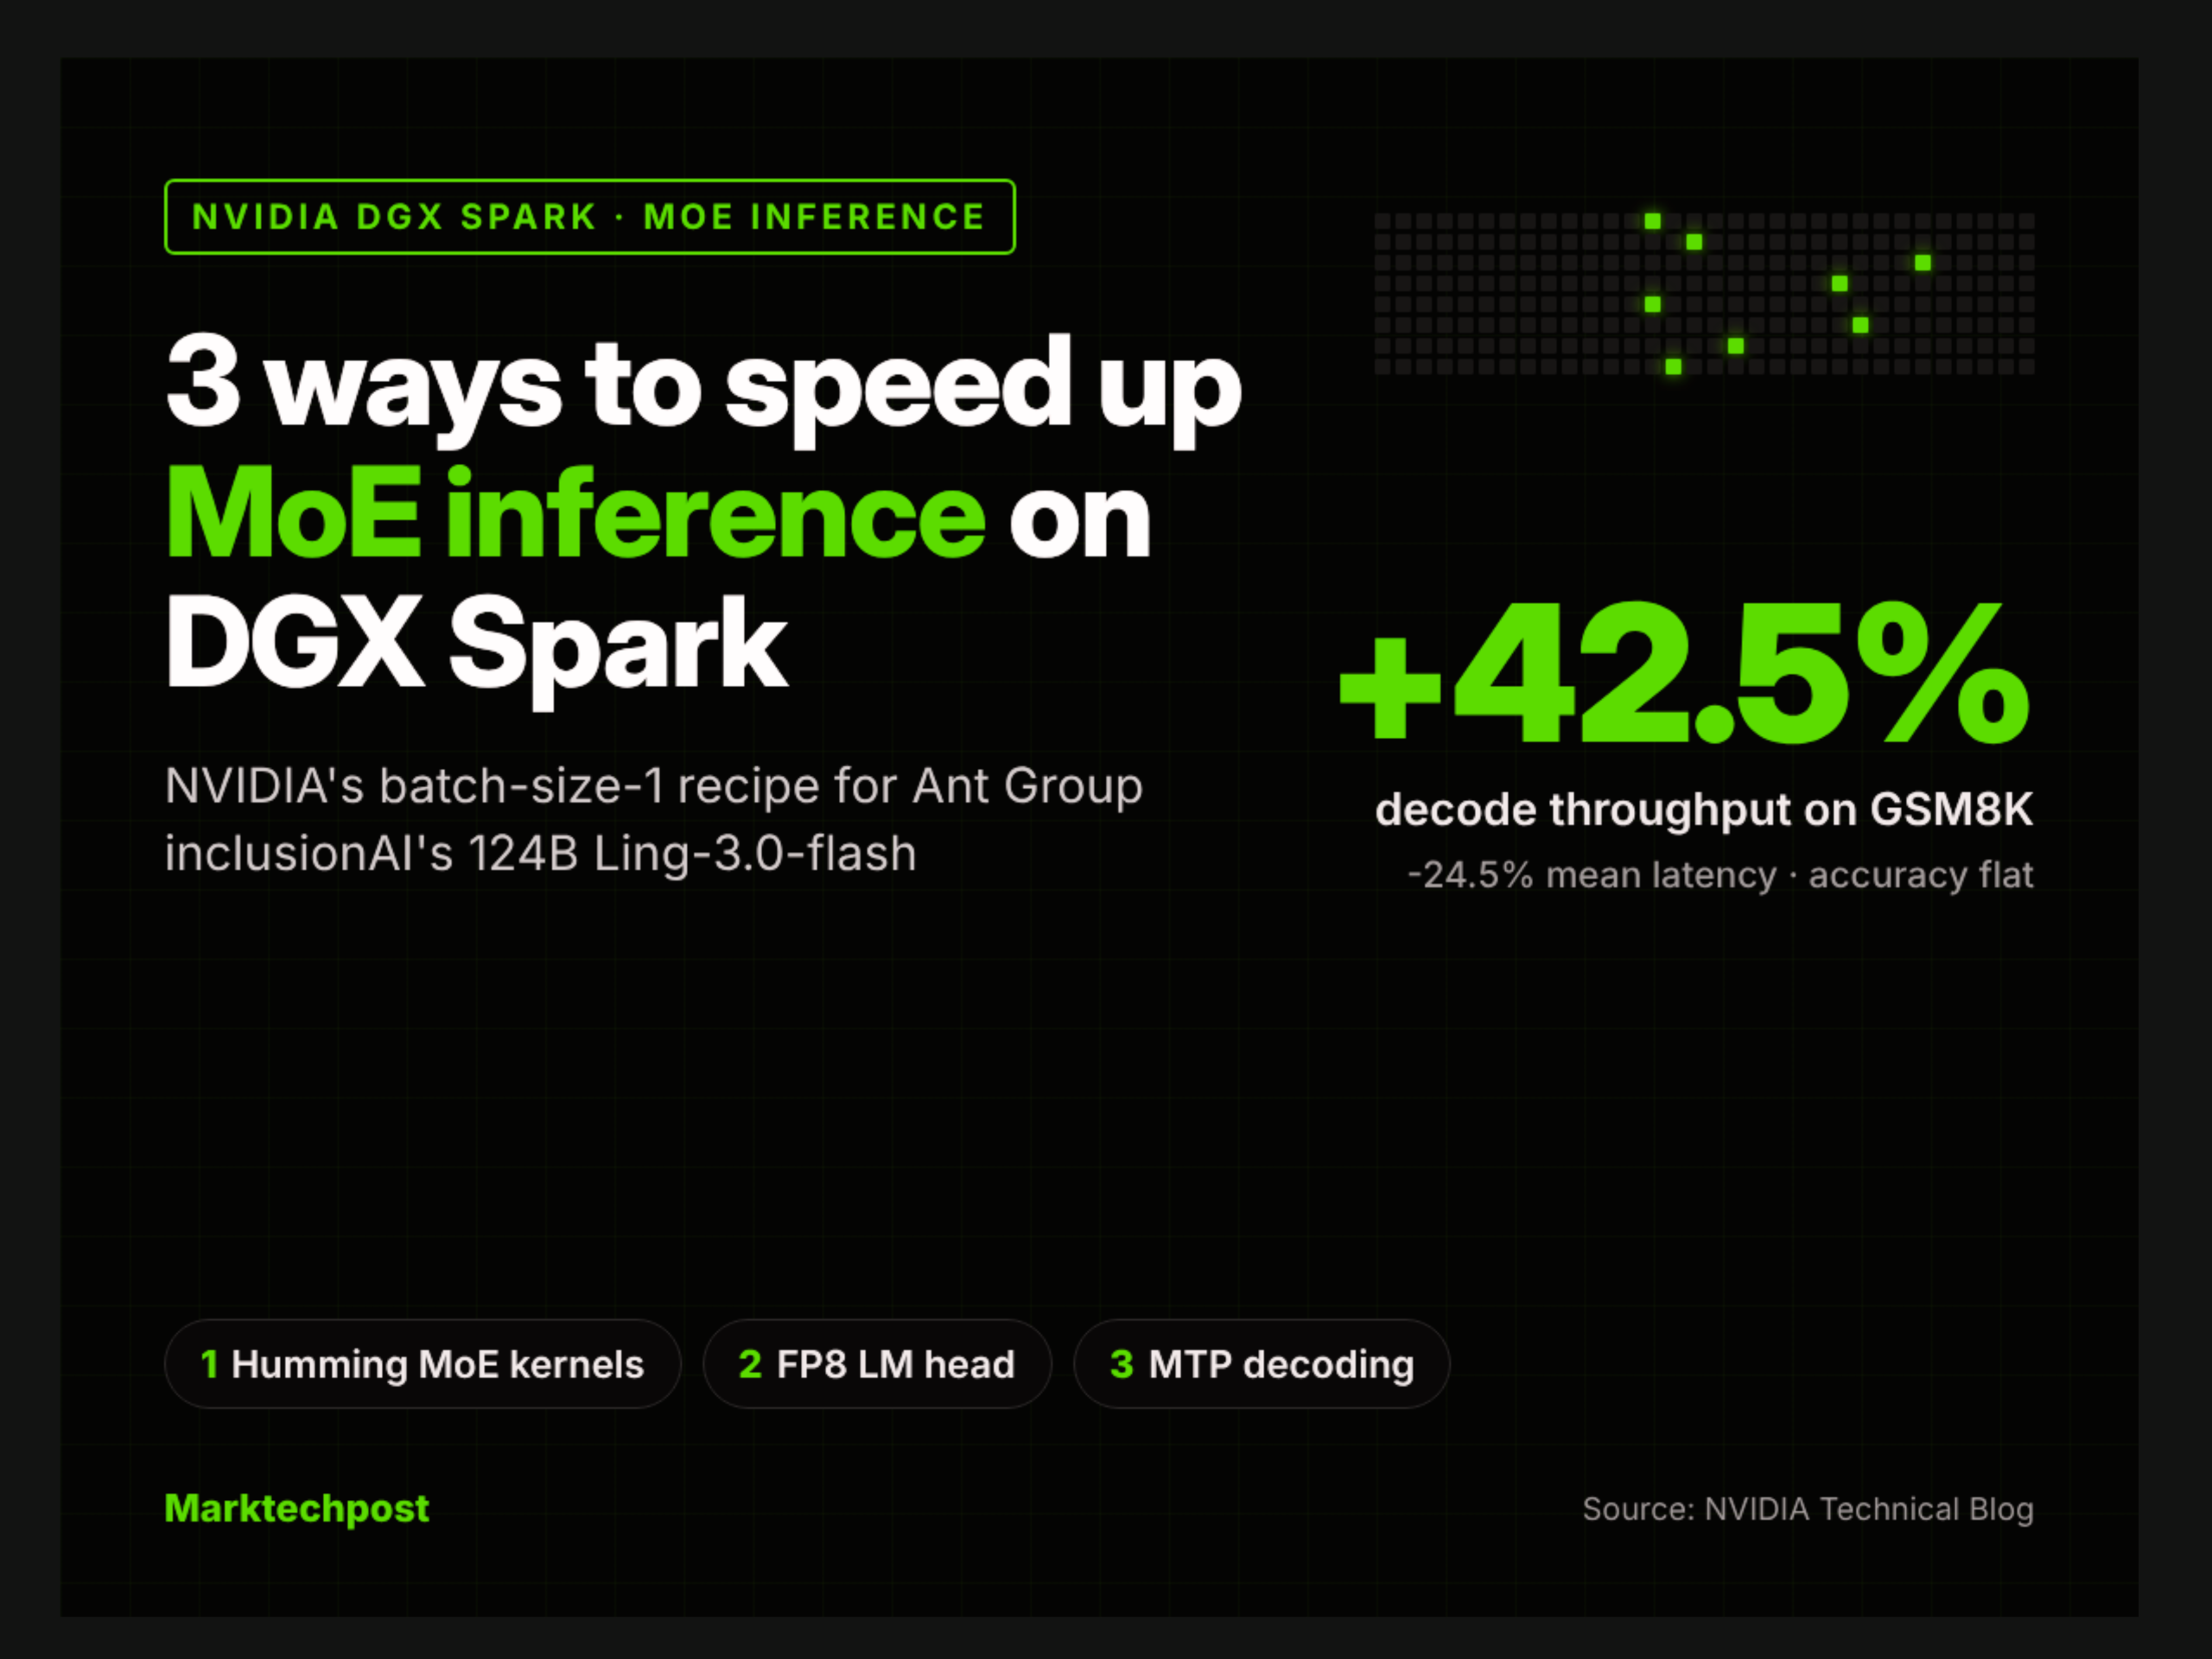
NVIDIA Shows 3 Ways to Speed Up MoE Inference on DGX Spark, Lifting Ling-3.0-flash Throughput 42.5%
MarkTechPost
Read the full articleNVIDIA improved inference speed for Ant Group's Ling-3.0-flash 124B-parameter MoE model on a single DGX Spark desktop system by 42.5% using three optimizations: a new MoE kernel backend, FP8 output layer, and speculative decoding, with no accuracy loss.