Reduce inference cold starts on Amazon SageMaker HyperPod with model caching

AWS Blog
Read the full article
Amazon SageMaker HyperPod now supports model caching, which preloads large language model weights and container images onto cluster nodes. This reduces pod cold start times from tens of minutes to seconds by avoiding repeated network downloads during autoscaling.

More in Machine Learning

Machine Learning5 min read

PyTorch Conference 2026: Google and Meta Open-Source TorchTPU for Native PyTorch on TPUs

InfoQ (AI, ML & Data)
Machine Learning5 min read

Scientists overcome a hidden obstacle to more powerful quantum computers

Science Daily
Machine Learning32 min read

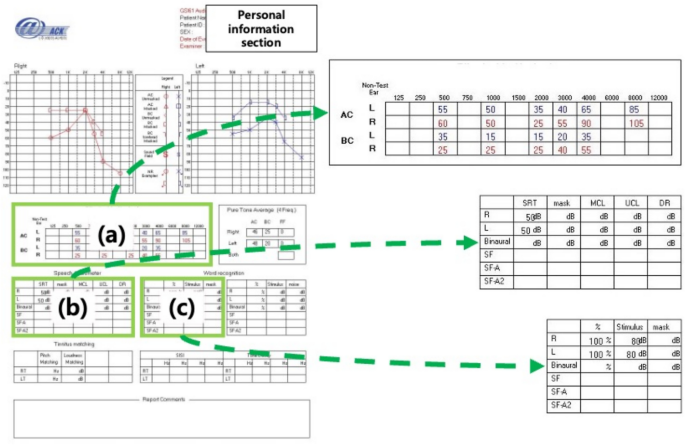
Development of an automated method for audiometric data extraction and analysis using voting optical character recognition

Nature