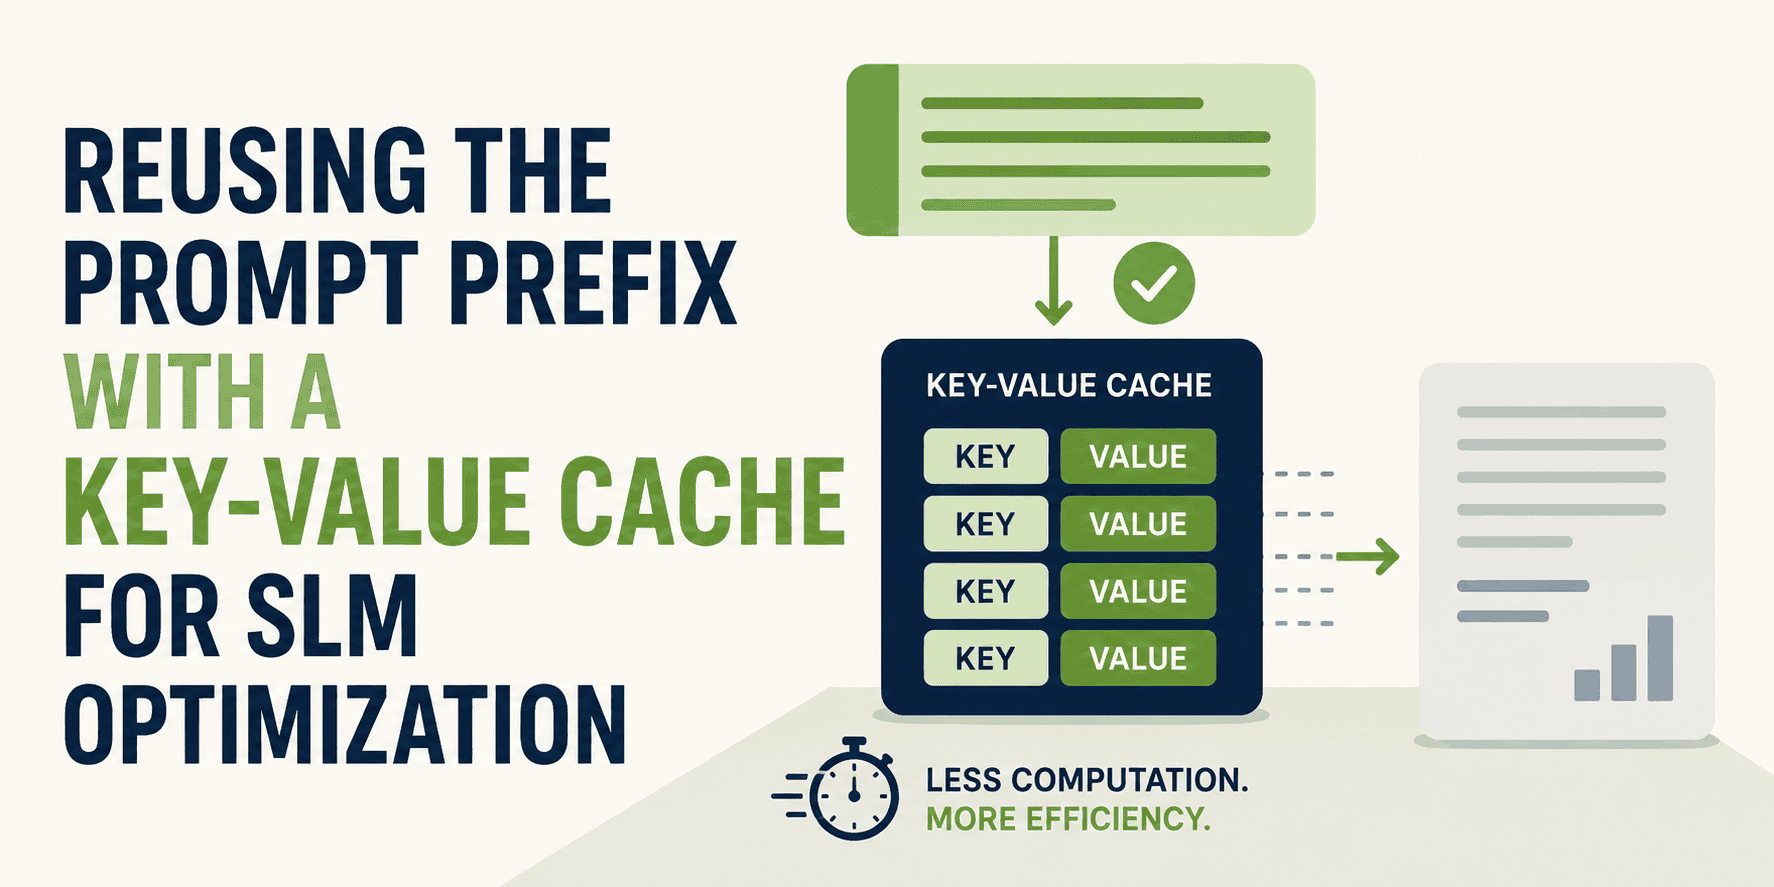


Reusing the Prompt Prefix with a Key-Value Cache for SLM Optimization
KDnuggets
Read full postResearchers demonstrate optimizing small language model (SLM) inference by reusing prompt prefixes with a key-value cache, reducing redundant computation in repeated prompt scenarios using Qwen2.5-0.5B-Instruct on a Macbook Air.