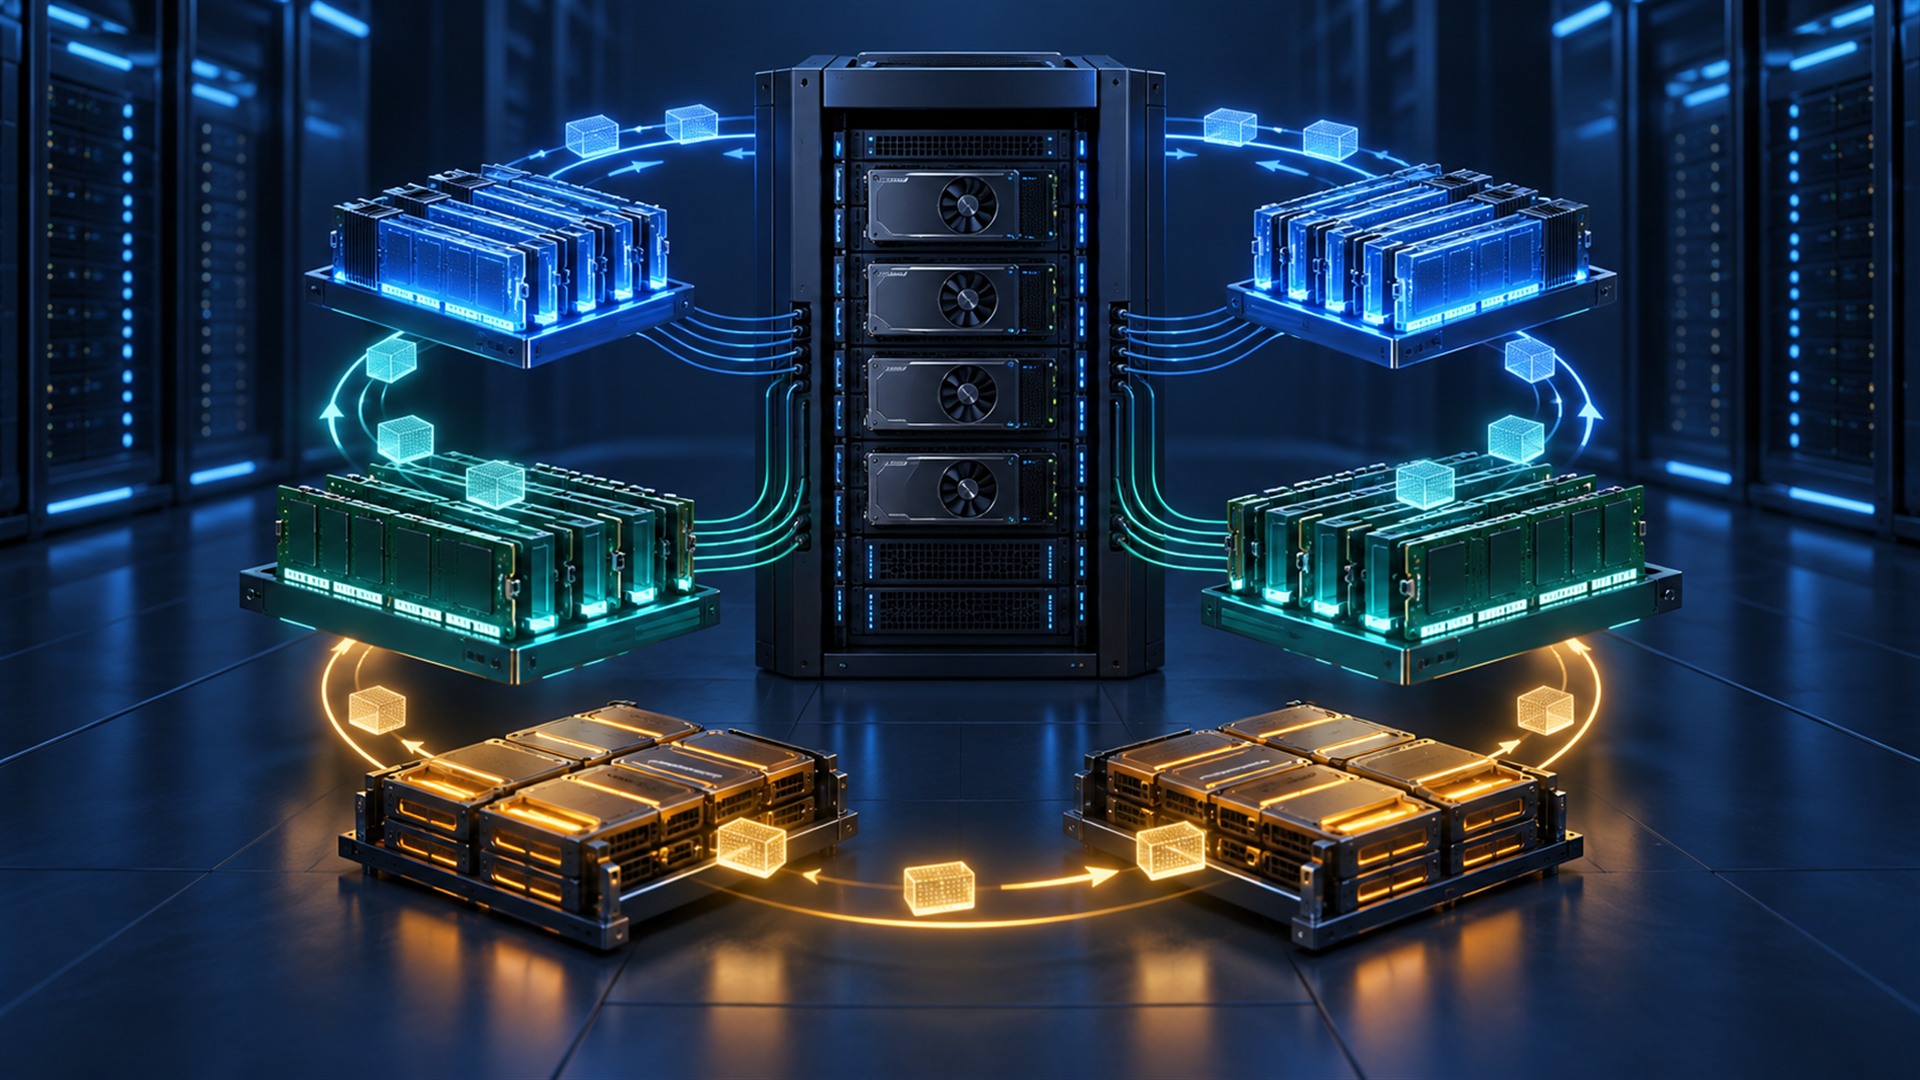
Tensormesh Launches Platform to Cut LLM Inference Costs Through KV-Cache Reuse
Unite.AI
Read the full articleTensormesh launched the Tensormesh Platform on October 14, 2026, to reduce large language model inference costs by managing reusable key-value cache states across GPU, CPU, and storage. This platform aims to cut redundant prompt processing in enterprise AI deployments by enabling efficient reuse of intermediate model states for repeated inputs.