What Are Native Audio Models? How Speech-to-Speech AI Skips Transcription
Unite.AI
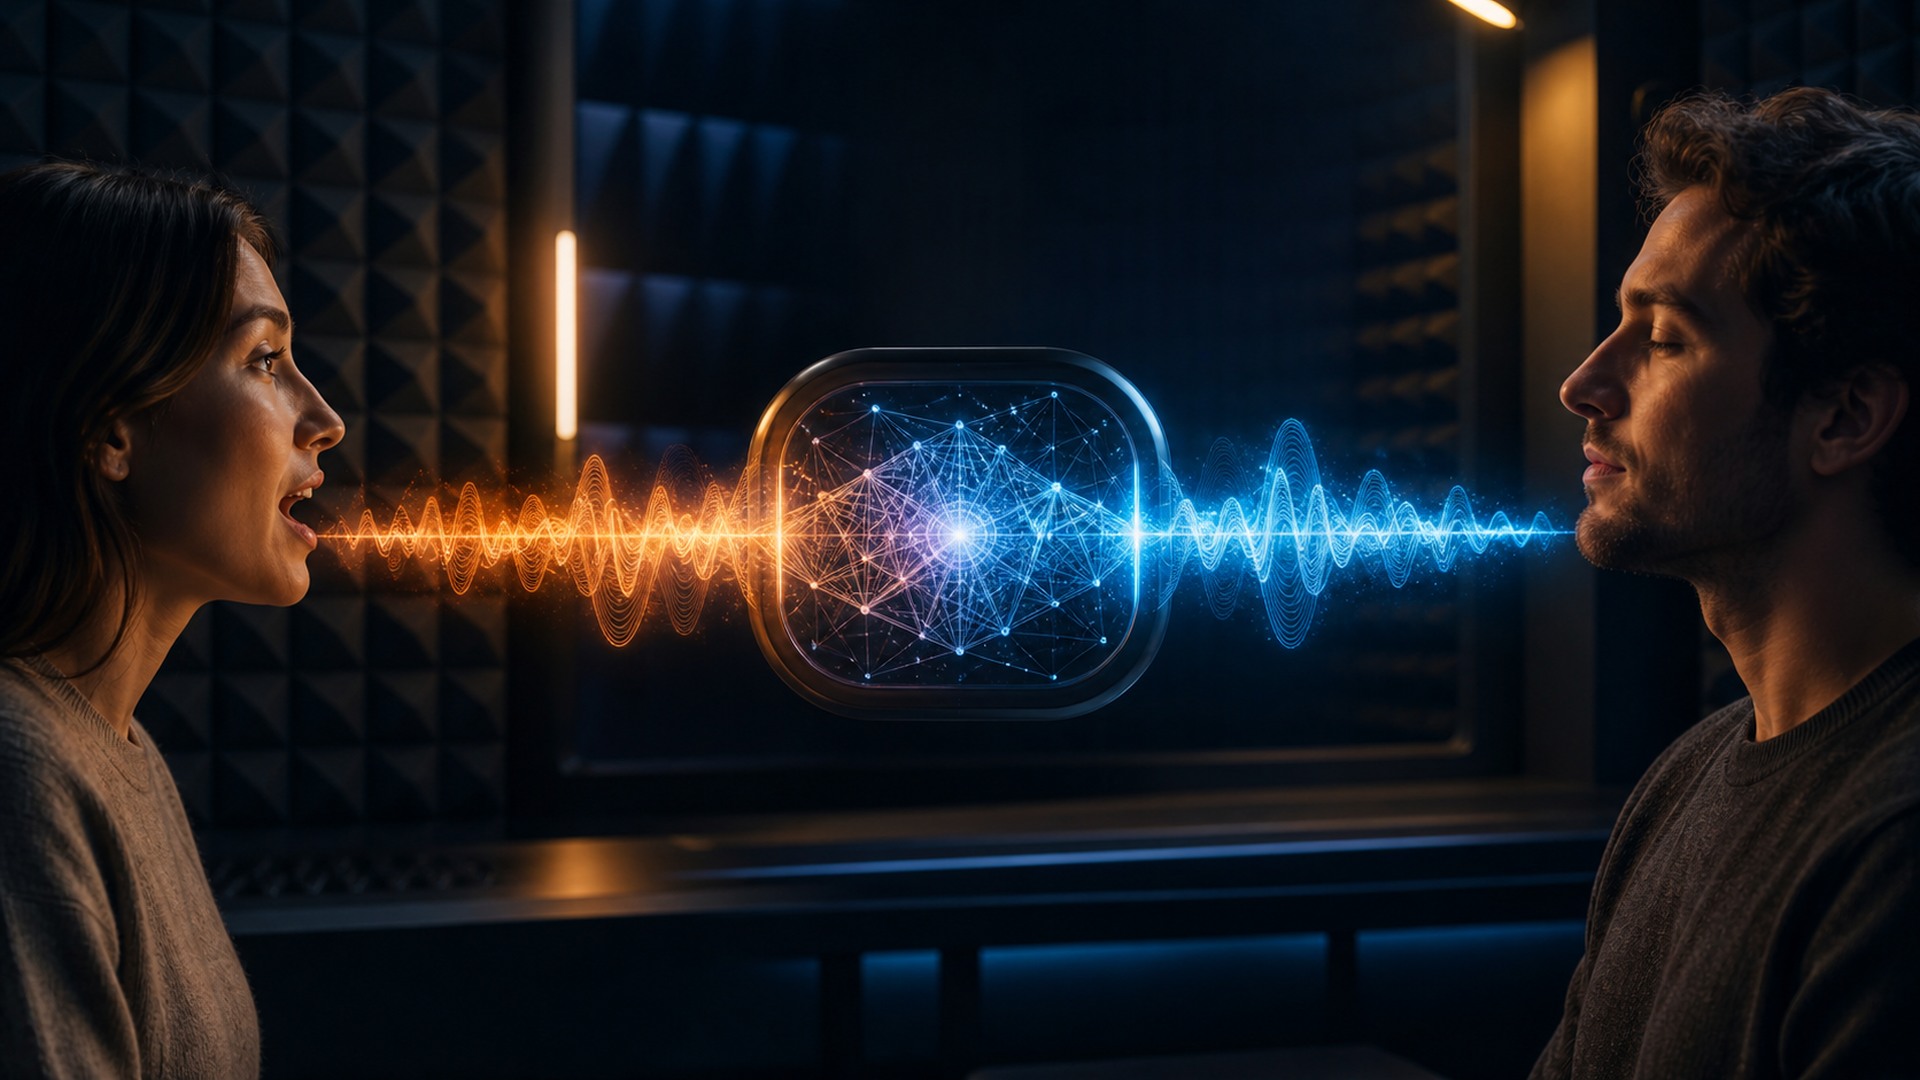
Read the full articleNative audio models directly process and generate acoustic signals, preserving speech nuances lost in transcription. They differ fundamentally from systems that transcribe speech to text before synthesis, impacting performance evaluation and control mechanisms.