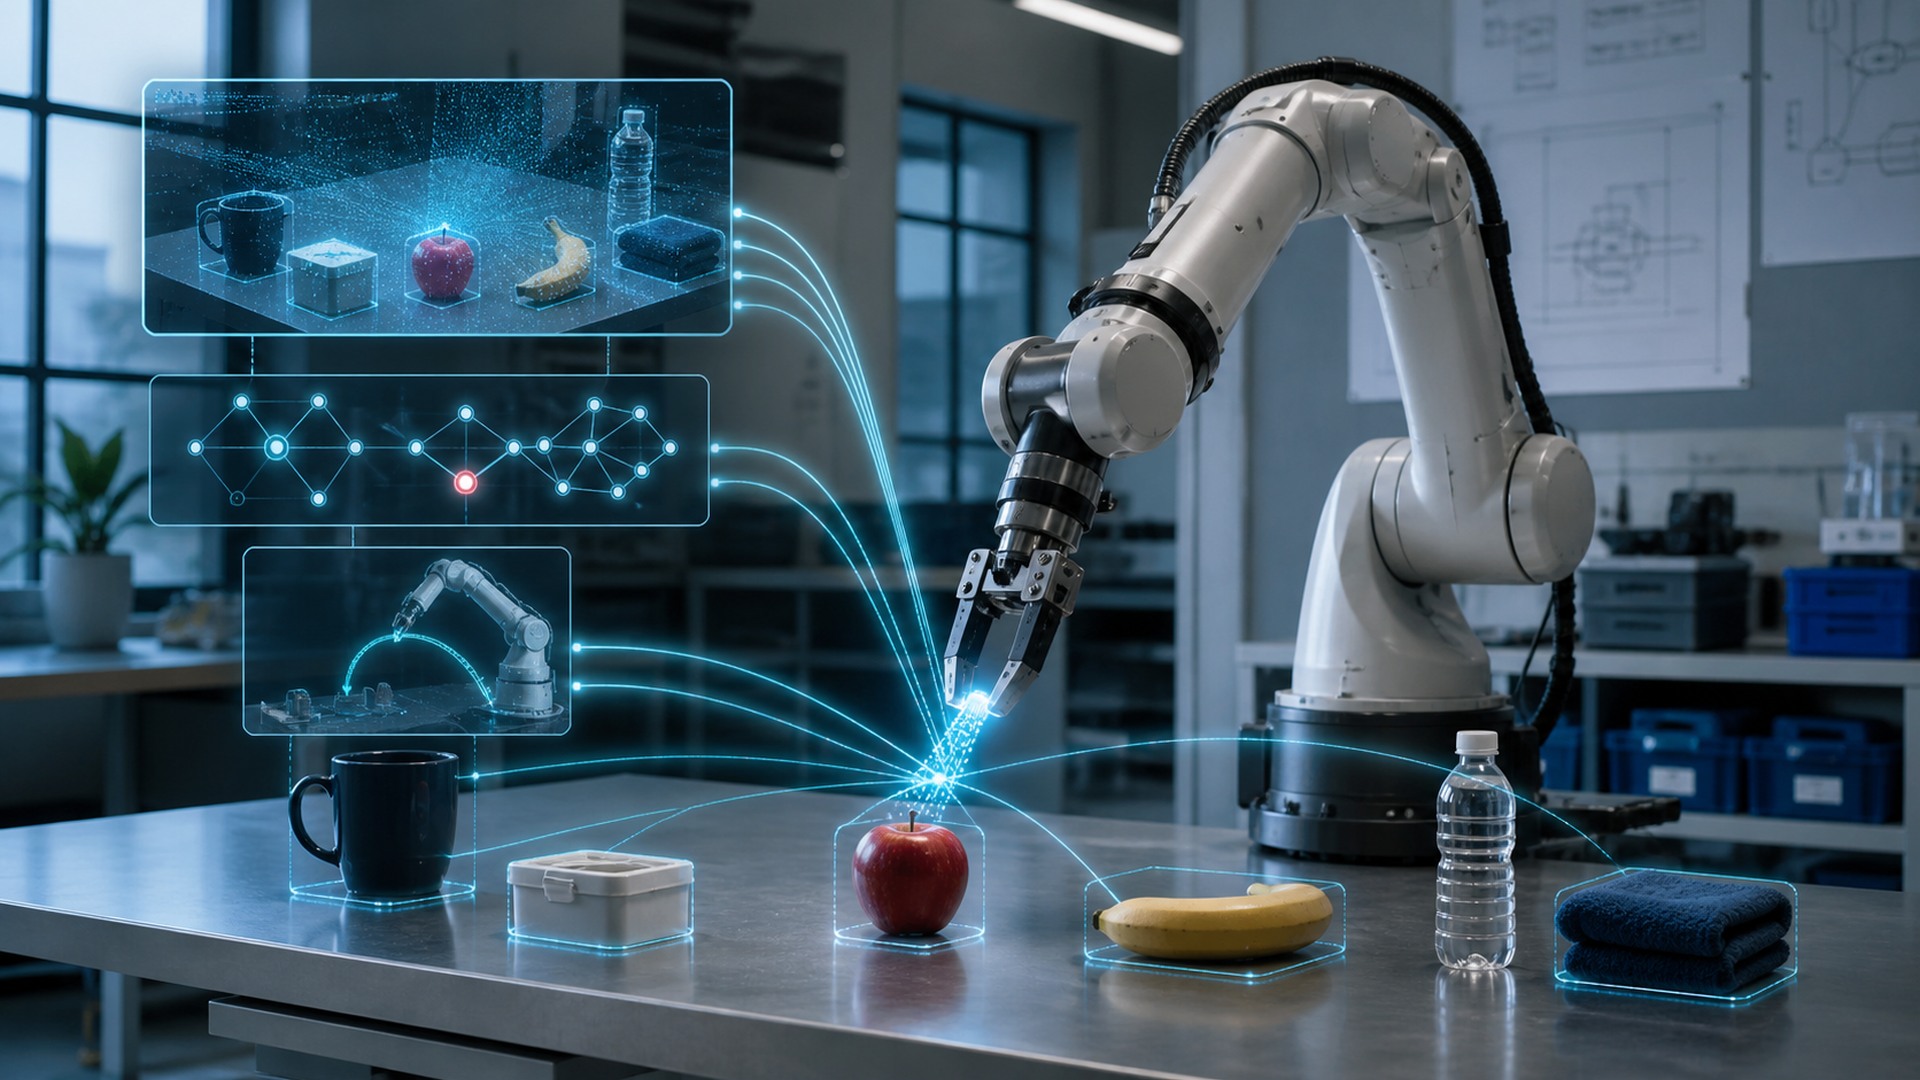
What Are Vision-Language-Action Models? The Foundation of General-Purpose Robots
Unite.AI
Read the full articleVision-language-action models integrate visual inputs and language instructions to guide physical actions in embodied systems, operating through a five-stage process from observation to action correction. This framework distinguishes these models from fixed-task robot controllers by emphasizing adaptable, multimodal decision-making.