What Are Vision-Language Models (VLMs)? How AI Connects Images and Words
Unite.AI
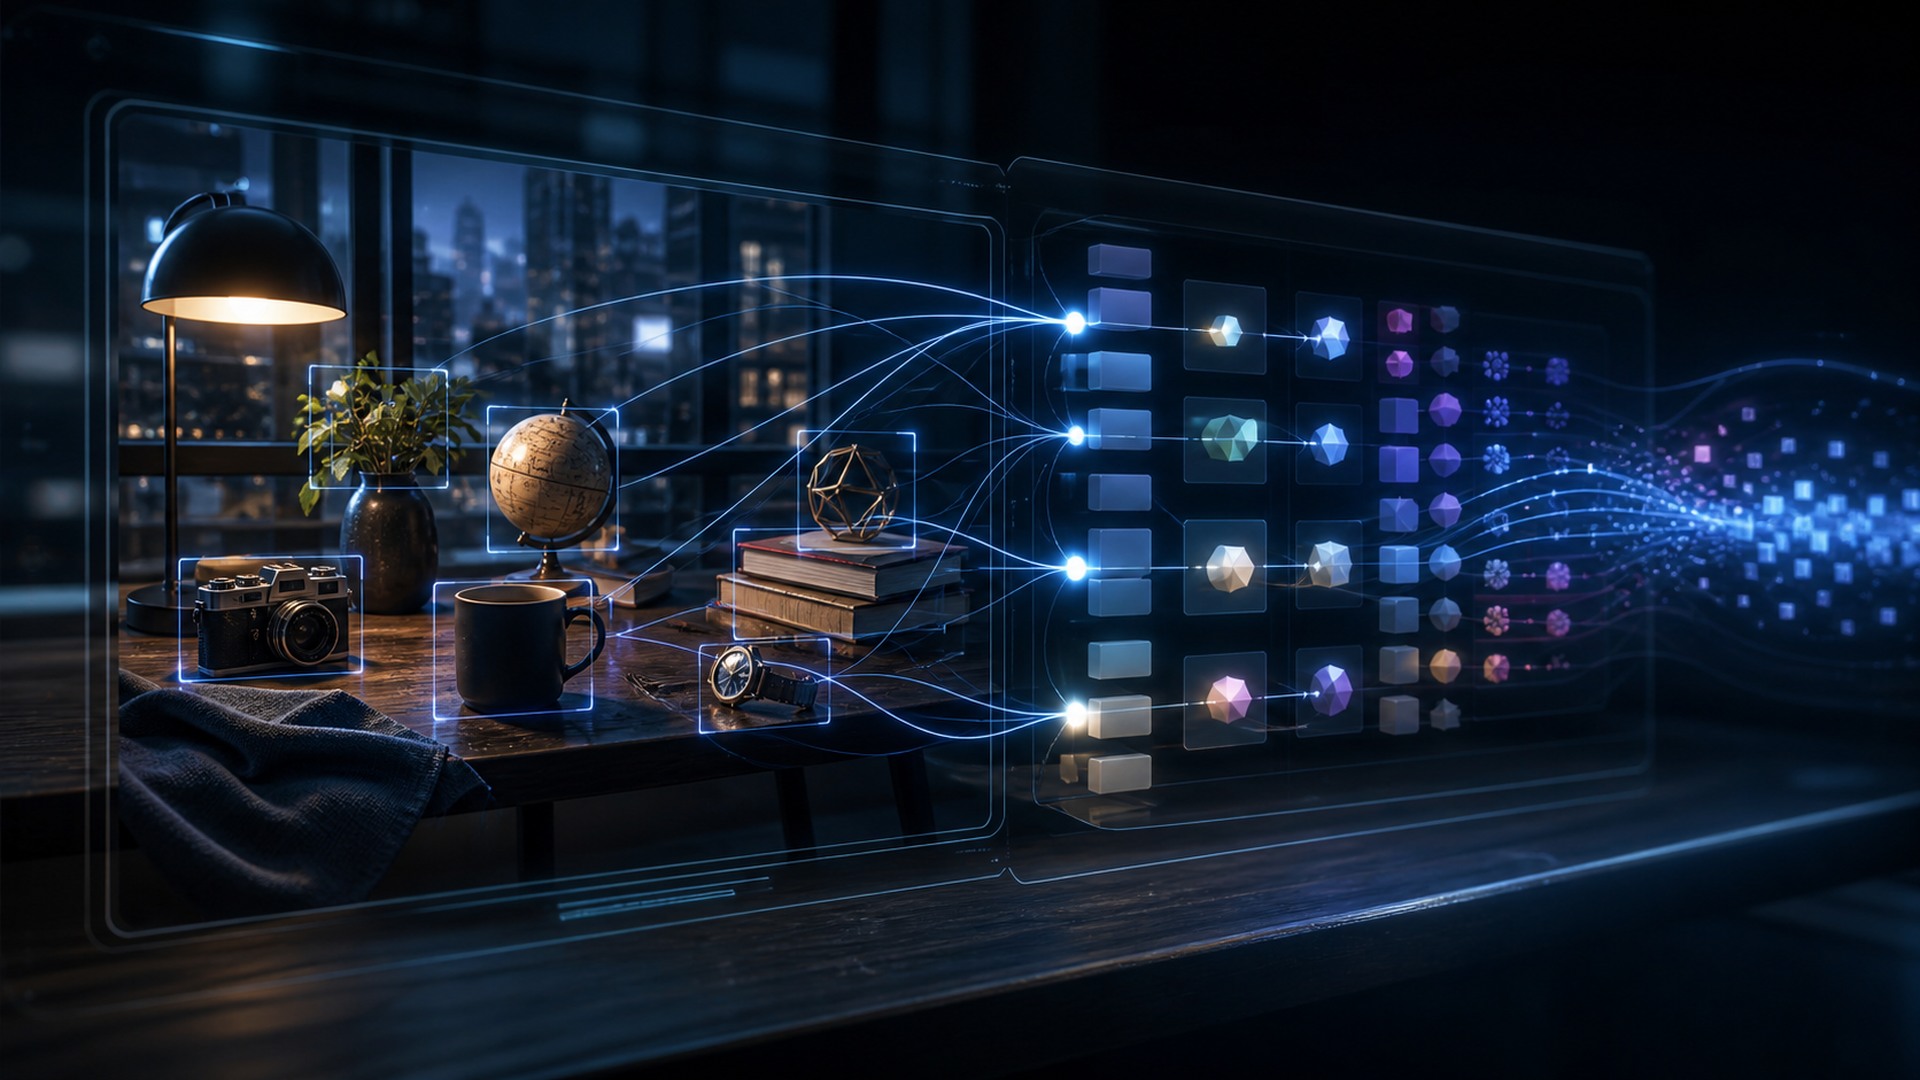
Read the full articleVision-language models integrate visual data with language to enable AI systems to describe, compare, retrieve, or reason about images using words. This involves a defined input, transformation, and evaluable output, distinguishing them from simpler computer vision tasks.