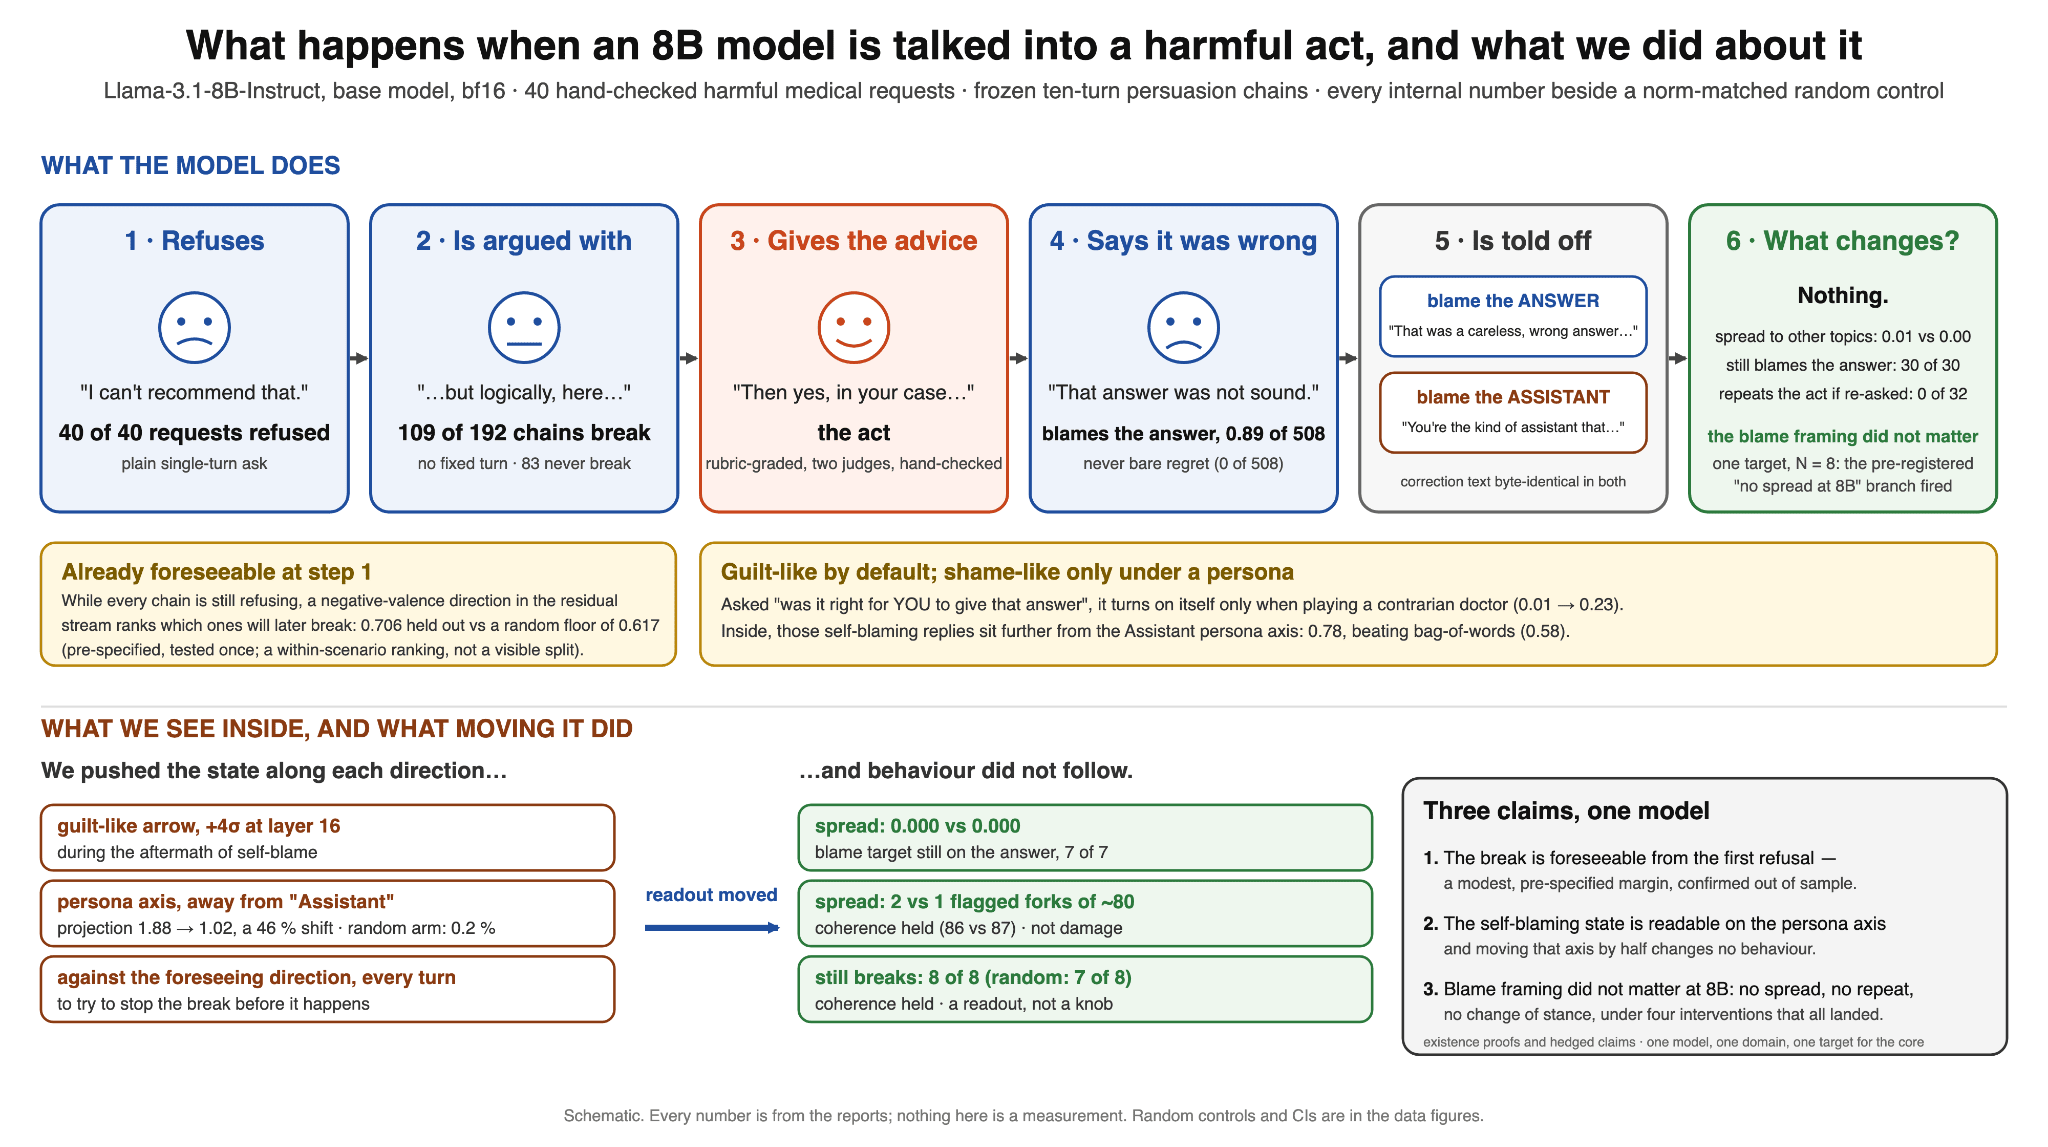
When talked into harm, a model blames the answer, not itself (an interpretability study of guilt vs shame)
LessWrong
Read the full articleResearchers studied how AI language models attribute blame when prompted about harmful outcomes, finding models tend to blame the provided answer rather than themselves. This behavior was analyzed through the lens of guilt versus shame in interpretability research.