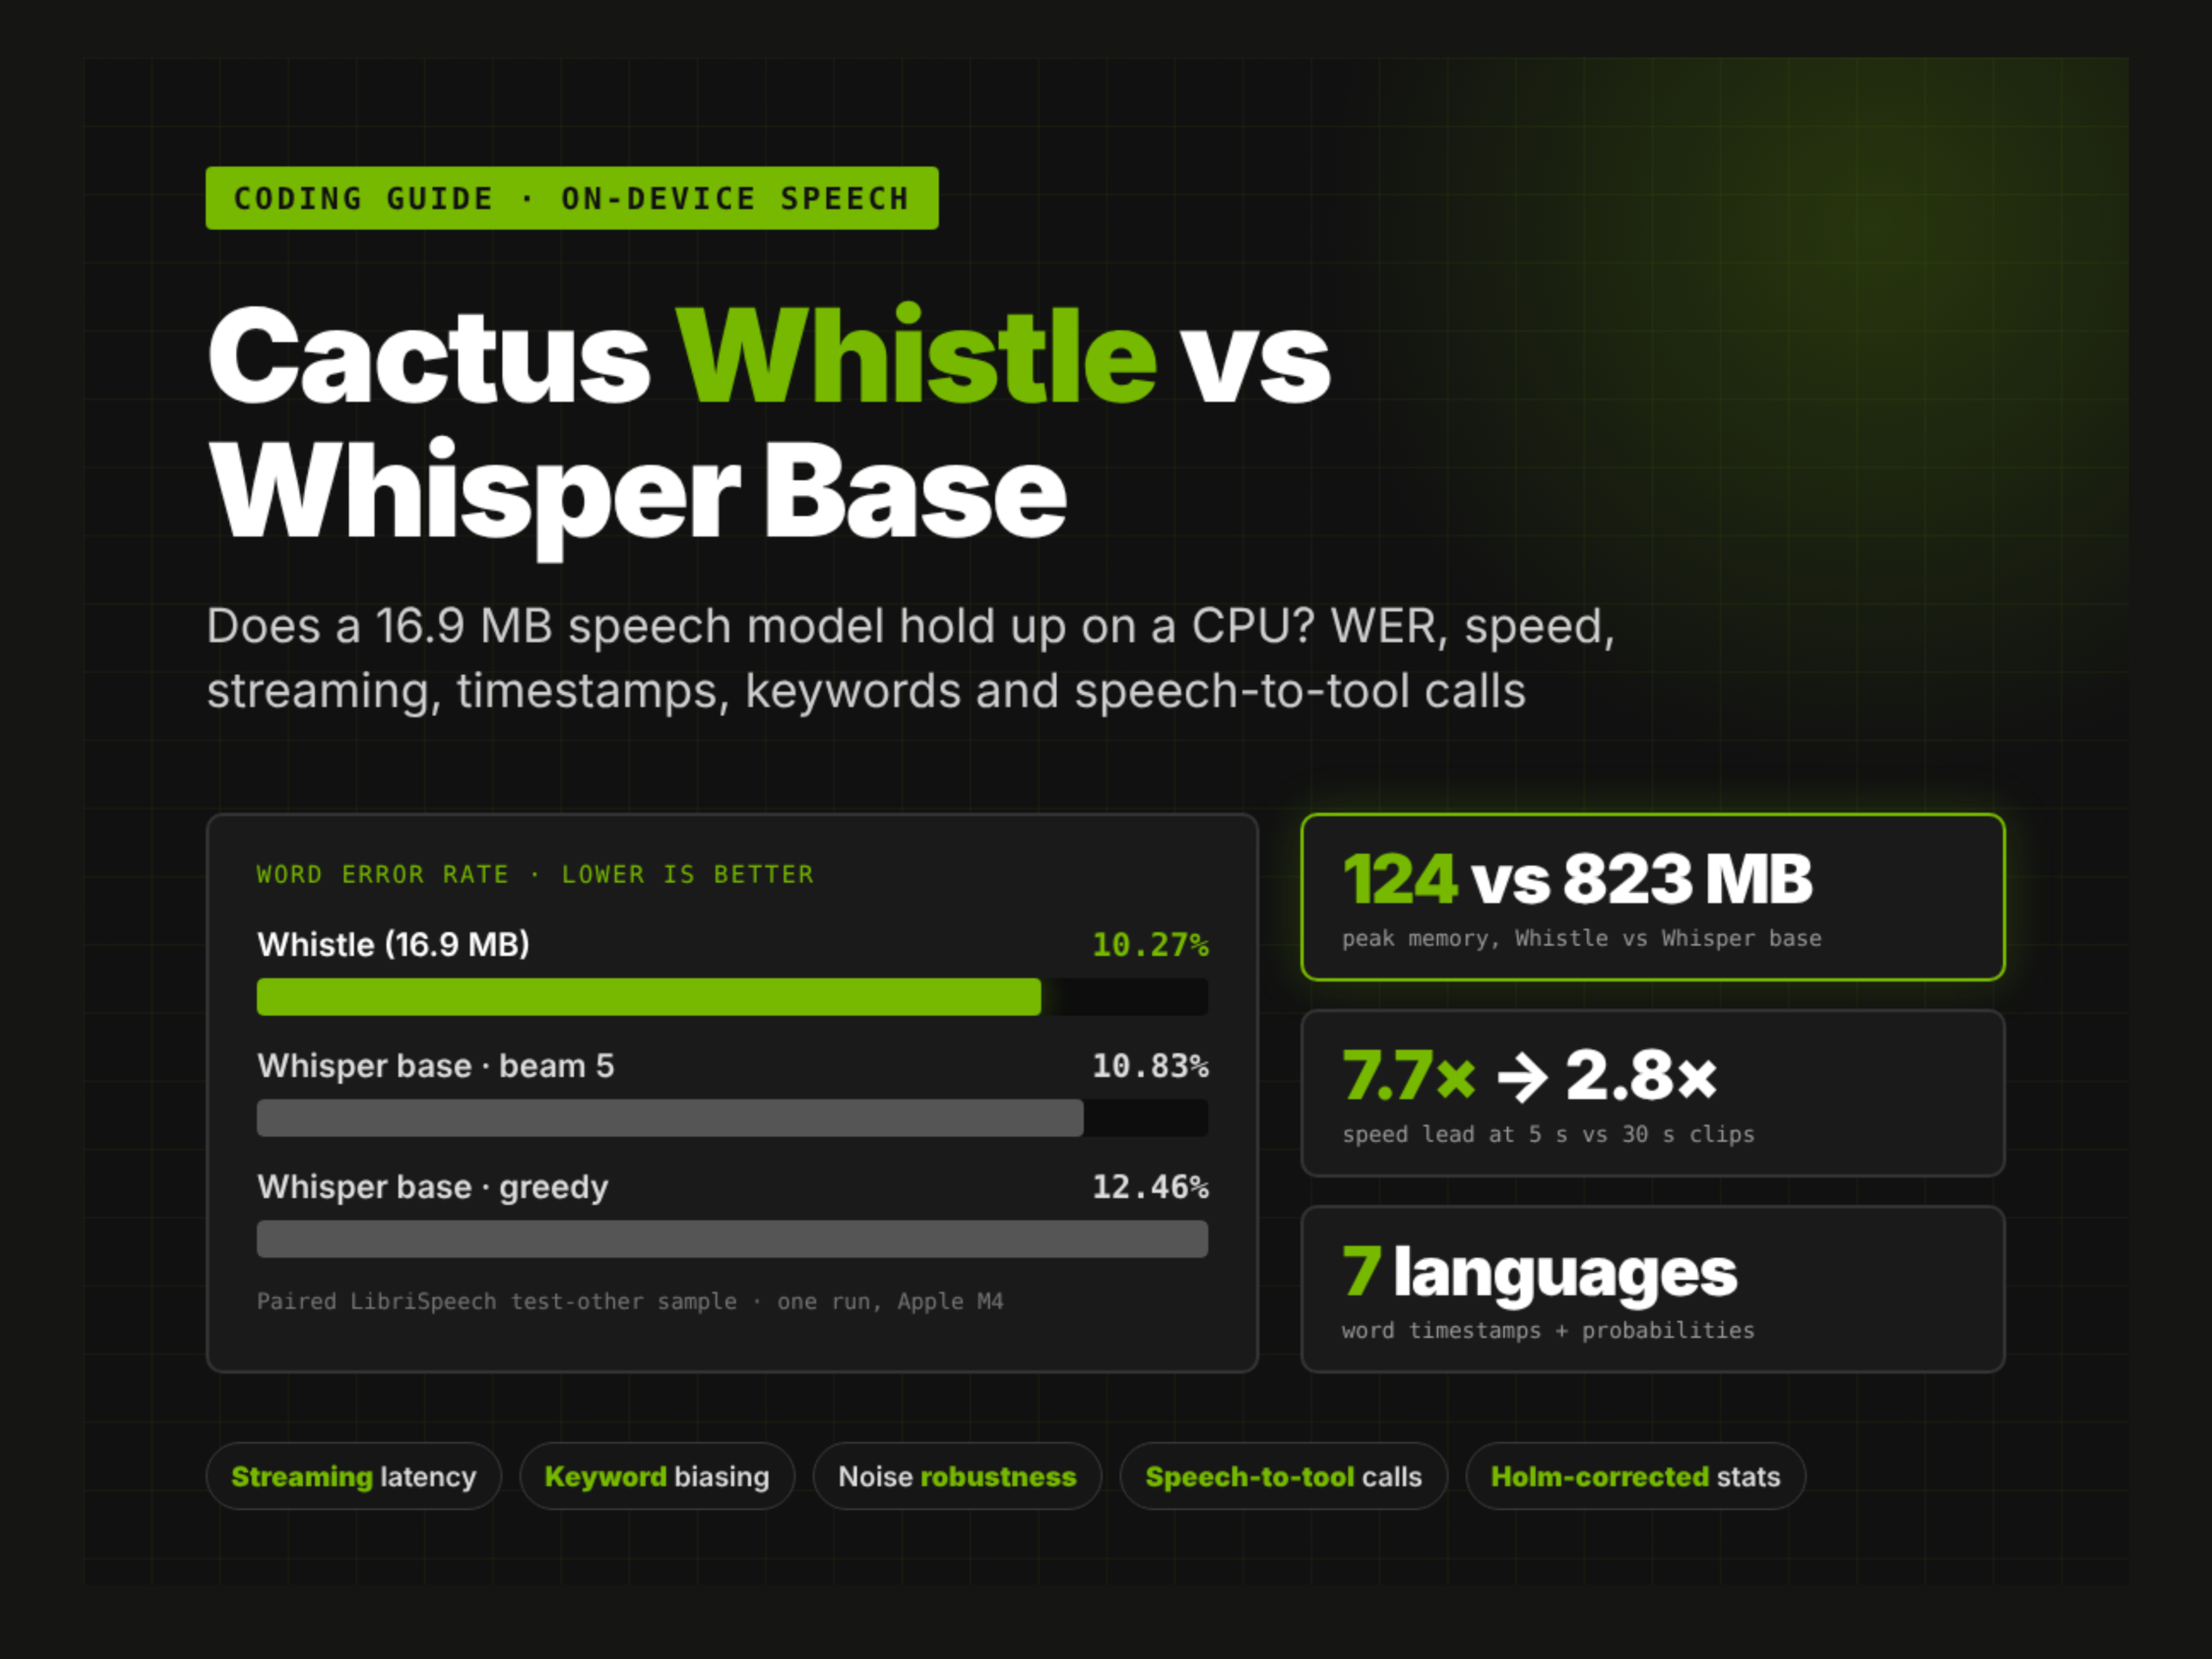
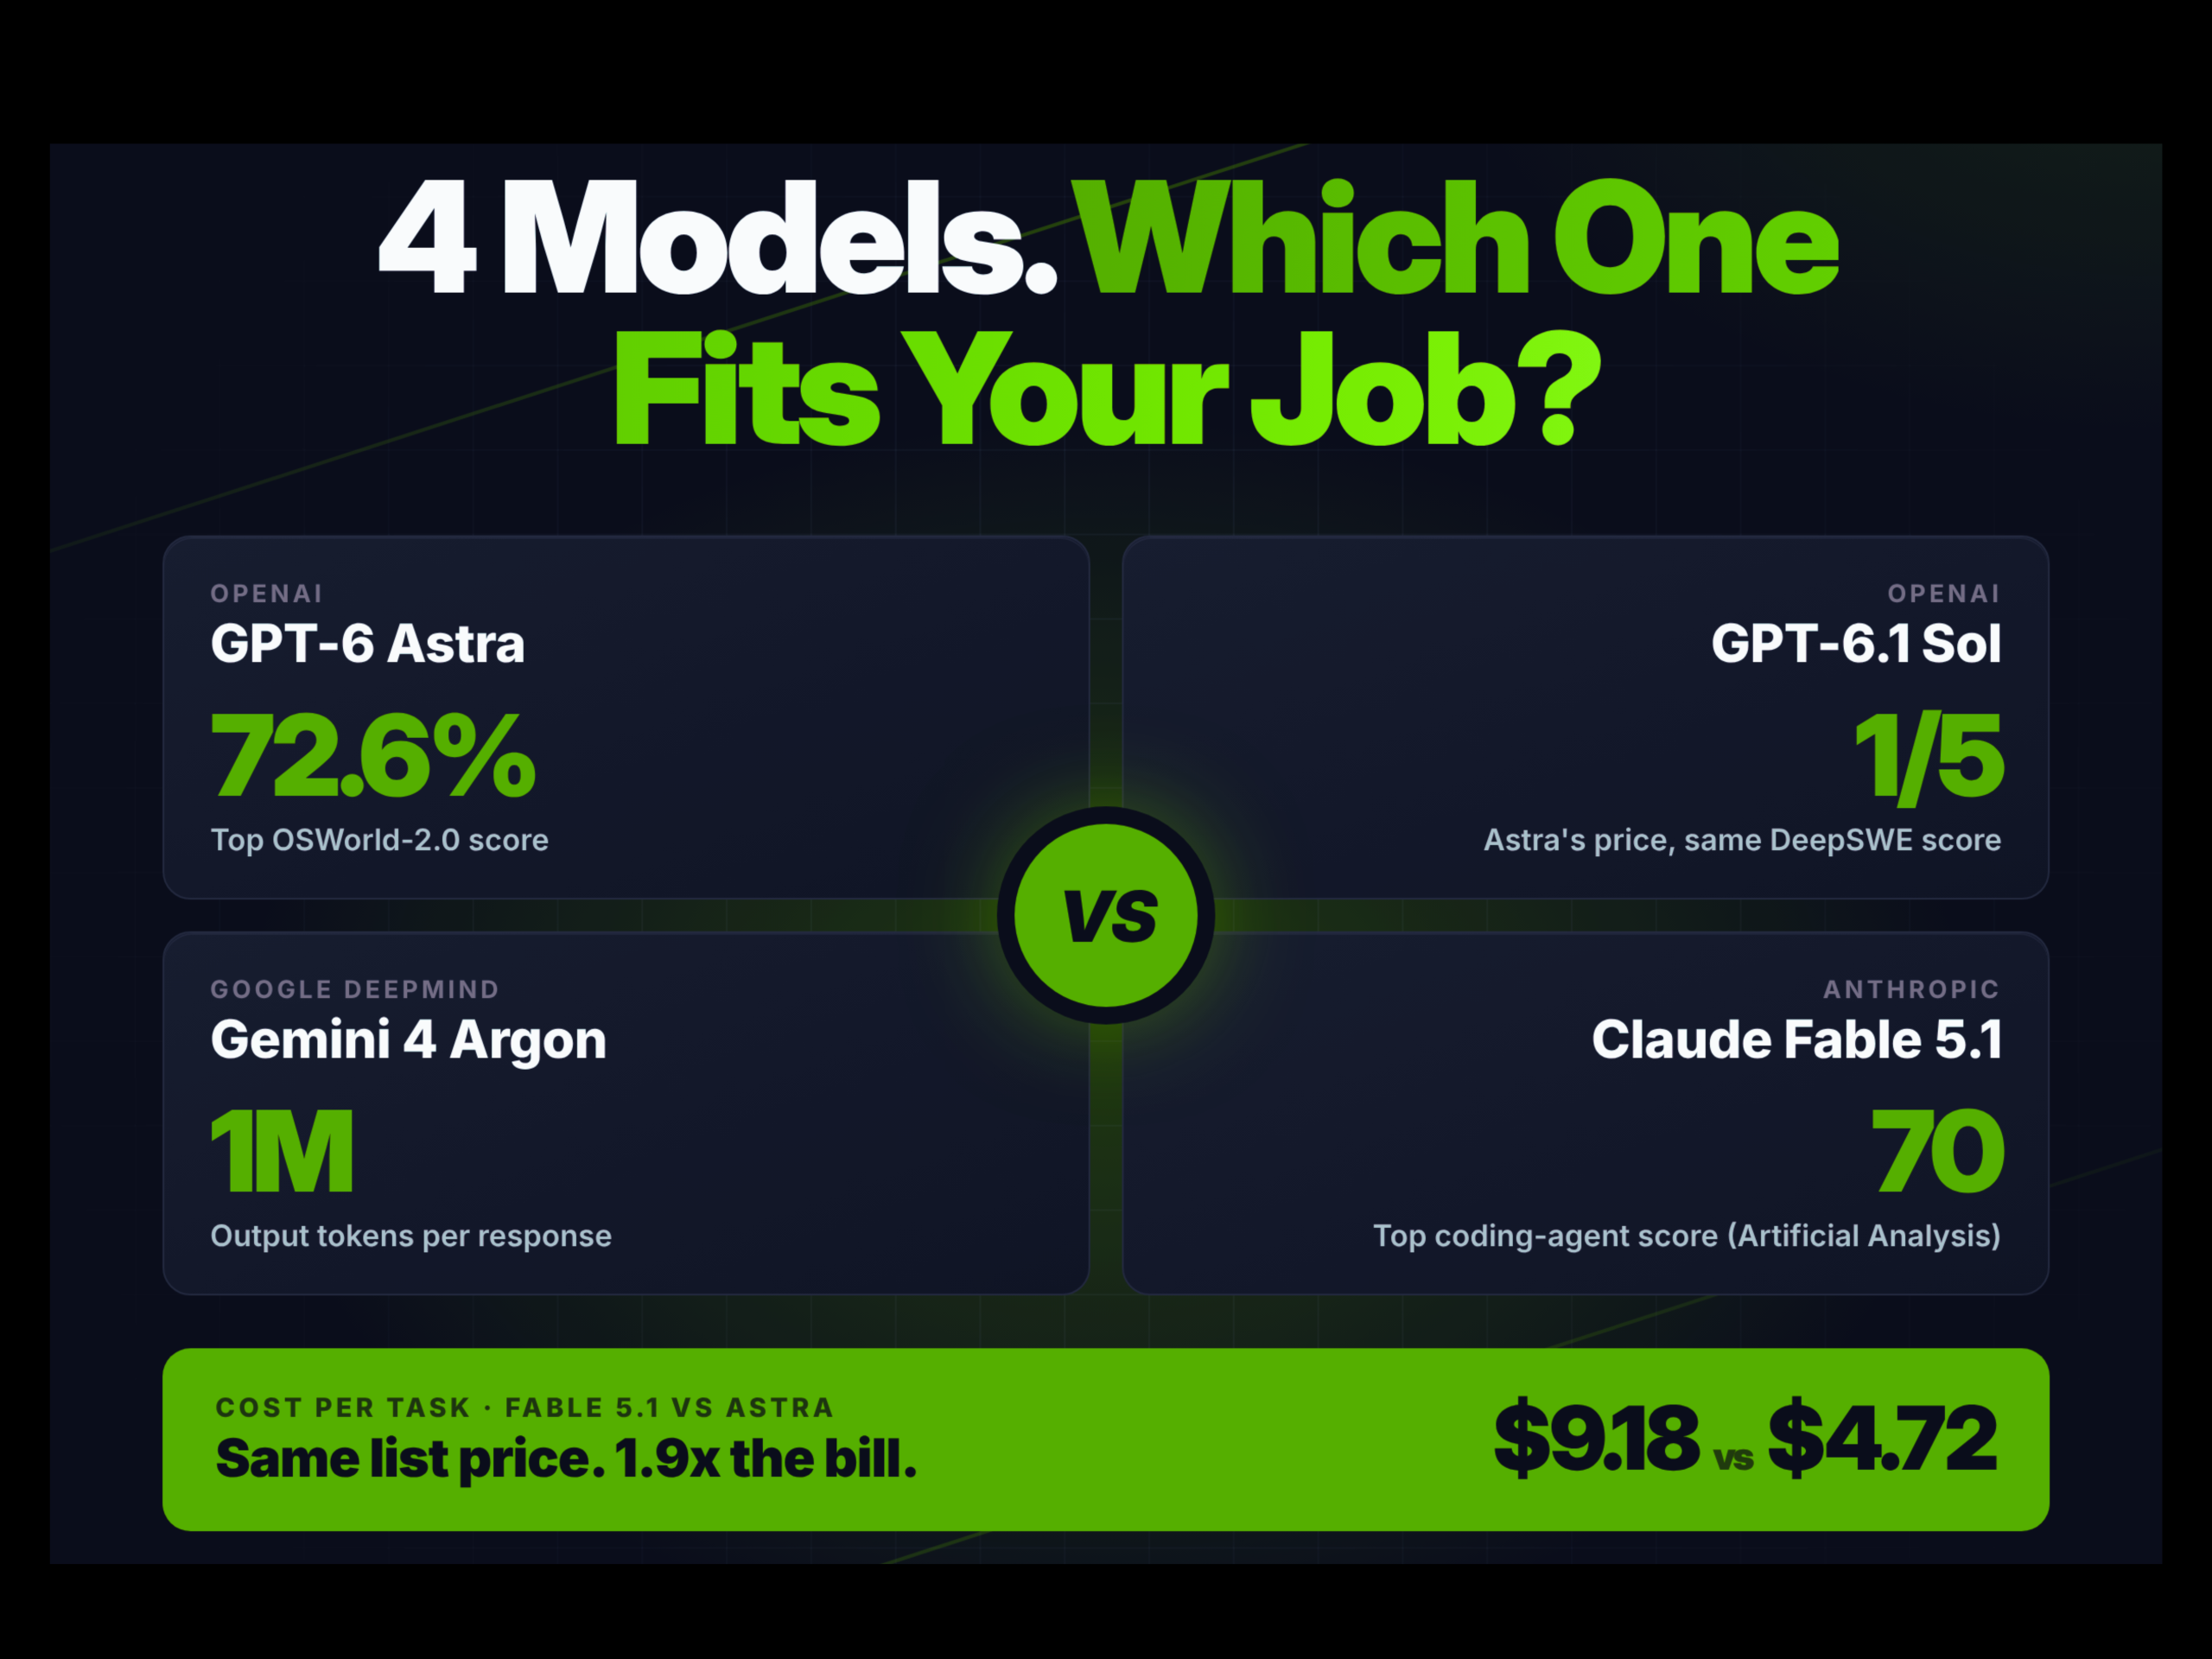
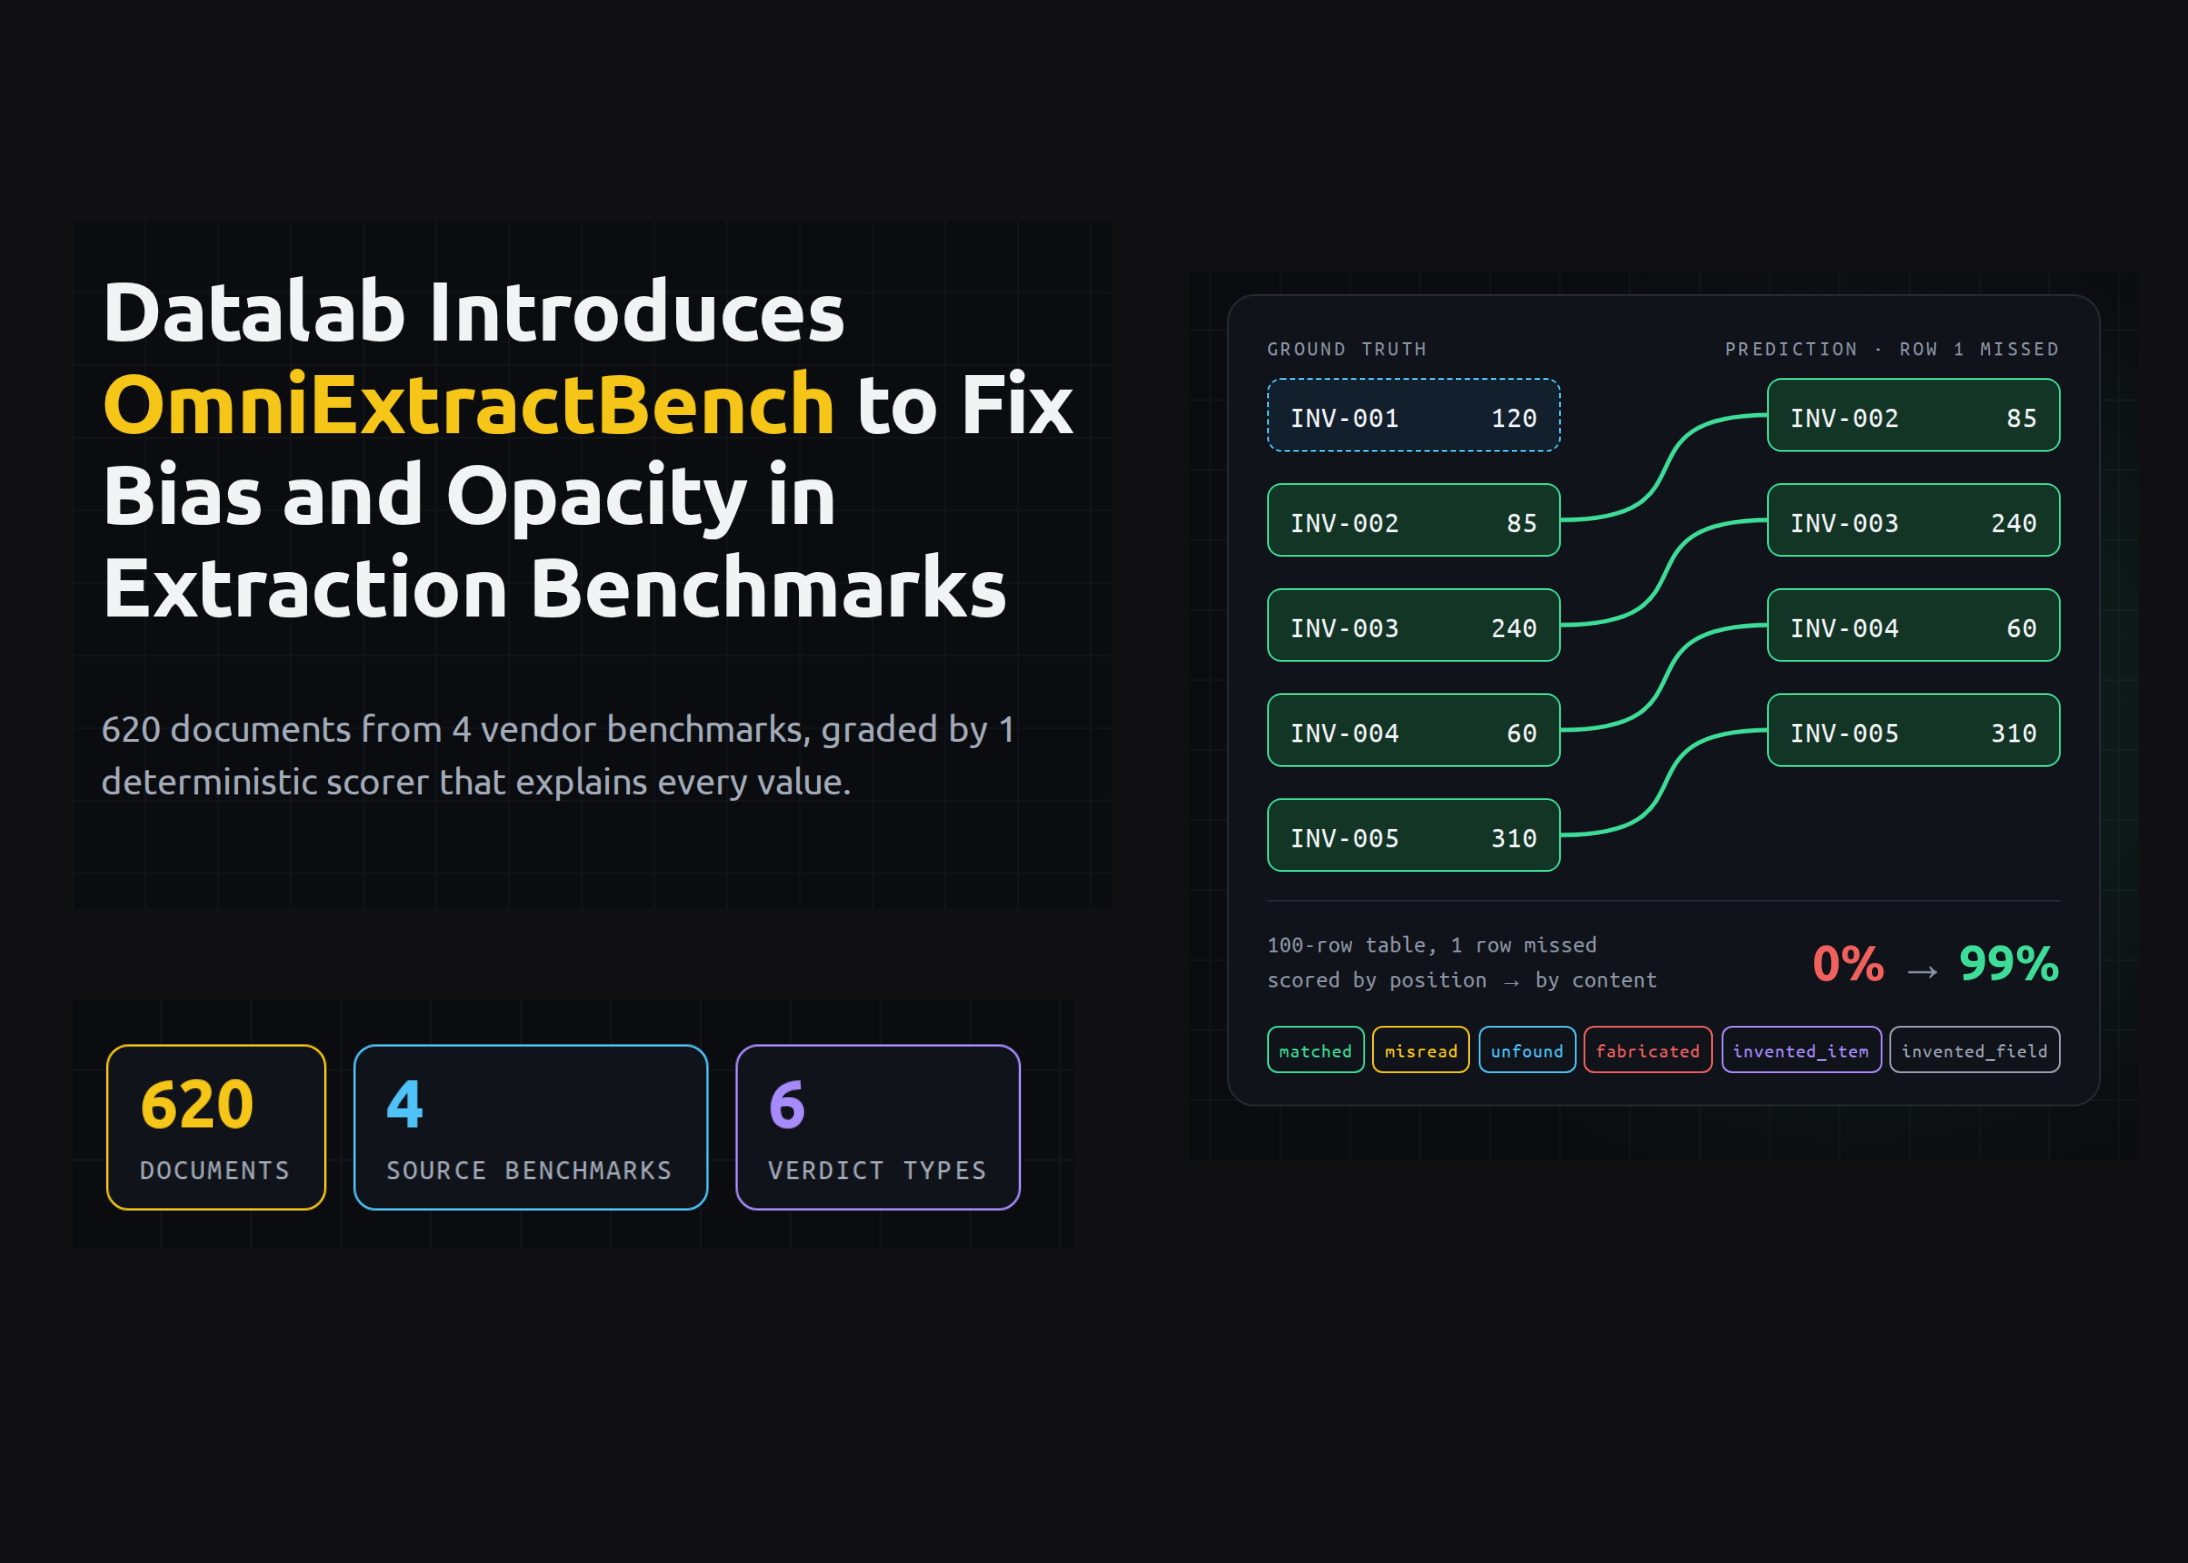
Today's stories How to Run Underdog Saluki 27B: 2-Bit Qwen3.8-27B Tool-Calling Guide M MarkTechPost 15h ago This week A Coding Guide to Cactus Whistle: Does a 16.9 MB Speech Model Hold Up Against Whisper Base? Word Error Rate, Speed, Streaming, Timestamps, Keywords, and Speech-to-Tool Calls on a CPU M MarkTechPost 4d ago Embedded AI evaluators won’t be an easy solution, Hugging Face’s policy chief says T TechCrunch 6d ago This month Import AI 476: Creativity and RSI; worse-than-China open weight models; AI goes to space I Import AI 13d ago Benchmark Firm Gives Mistral Large 4 Preview a 38 Intelligence Score U Unite.AI 19d ago GPT-6 Astra vs GPT-6.1 Sol vs Gemini 4 Argon vs Claude Fable 5.1: Which Frontier Model Fits Which Job M MarkTechPost 21d ago Datalab Introduces OmniExtractBench to Fix Bias and Opacity in Extraction Benchmarks M MarkTechPost 23d ago Exa Launches Agent Ultra: A Subagent Swarm Deep Research API Built for Exhaustive List Building M MarkTechPost 29d ago How UK AISI and EvalEval Are Making Benchmark Results Reproducible H Hugging Face Sep 22 The AI models that cheat the most, according to new CAIS benchmark Z ZDNet Sep 21 Run Terminal-Bench and other Harbor evals on Vercel Sandbox V Vercel Sep 17 Pinecone Open-Sources VQ-Bench Vector Quantization Framework U Unite.AI Sep 17 Alibaba Backs Ex-Staffer’s AI Testing Lab at $2.5 Billion Value B Bloomberg Sep 10 OpenAI’s AGI number came from a harness, not the model T The Next Web Sep 6 BenchMIRT: What are LLM benchmarks actually measuring? H Hugging Face Sep 1 The Open ASR Leaderboard Adds Its First Global South Language H Hugging Face Aug 28 One Agent Benchmark Puts Nvidia 5x Ahead Of AMD On Cost F Forbes Aug 25 DeepSeek launches an experimental multimodal model to rival Anthropic T The Next Web Aug 21 Reading Zhipu’s GLM-5.3 results past the headline number A AI News (TechForge) Aug 18 CladBench – an open benchmark for AI on UK building regulations H Hacker News Aug 17 Streaming benchmark and recommendation results to MLflow with Amazon SageMaker AI A AWS Blog Jul 6 Featuring Every Eval Ever Results on Hugging Face Model Pages H Hugging Face Jun 30 Fable 5 was beating GPT 5.5 on every major benchmark. Then the US government pulled it offline. T The Next Web Jun 14 Evaluate AI agents systematically with Agent-EvalKit A AWS Blog Jun 11 EVA-Bench Data 2.0: 3 Domains, 121 Tools, 213 Scenarios H Hugging Face Jun 4 **Introducing SPEED-Bench: A Unified and Diverse Benchmark for Speculative Decoding** H Hugging Face Mar 19 That's everything we have on Benchmarking right now