


Updates on Mixture of Experts
Every AI story we track on Mixture of Experts: 15 stories so far, each summarized in our own words and linked to the publisher that reported it.
Pulled from 125 sources
This month

Machine Learning6 min read
Alibaba just released Qwen3.8-Flash: “An early preview of the architecture in Qwen4”
The New Stack (AI)
Machine Learning9 min read
Meet FreeToken: An Edge-Native MoE Serving Engine that Runs 753B GLM-5.2 on a Single Workstation GPU
MarkTechPost
Machine Learning5 min read
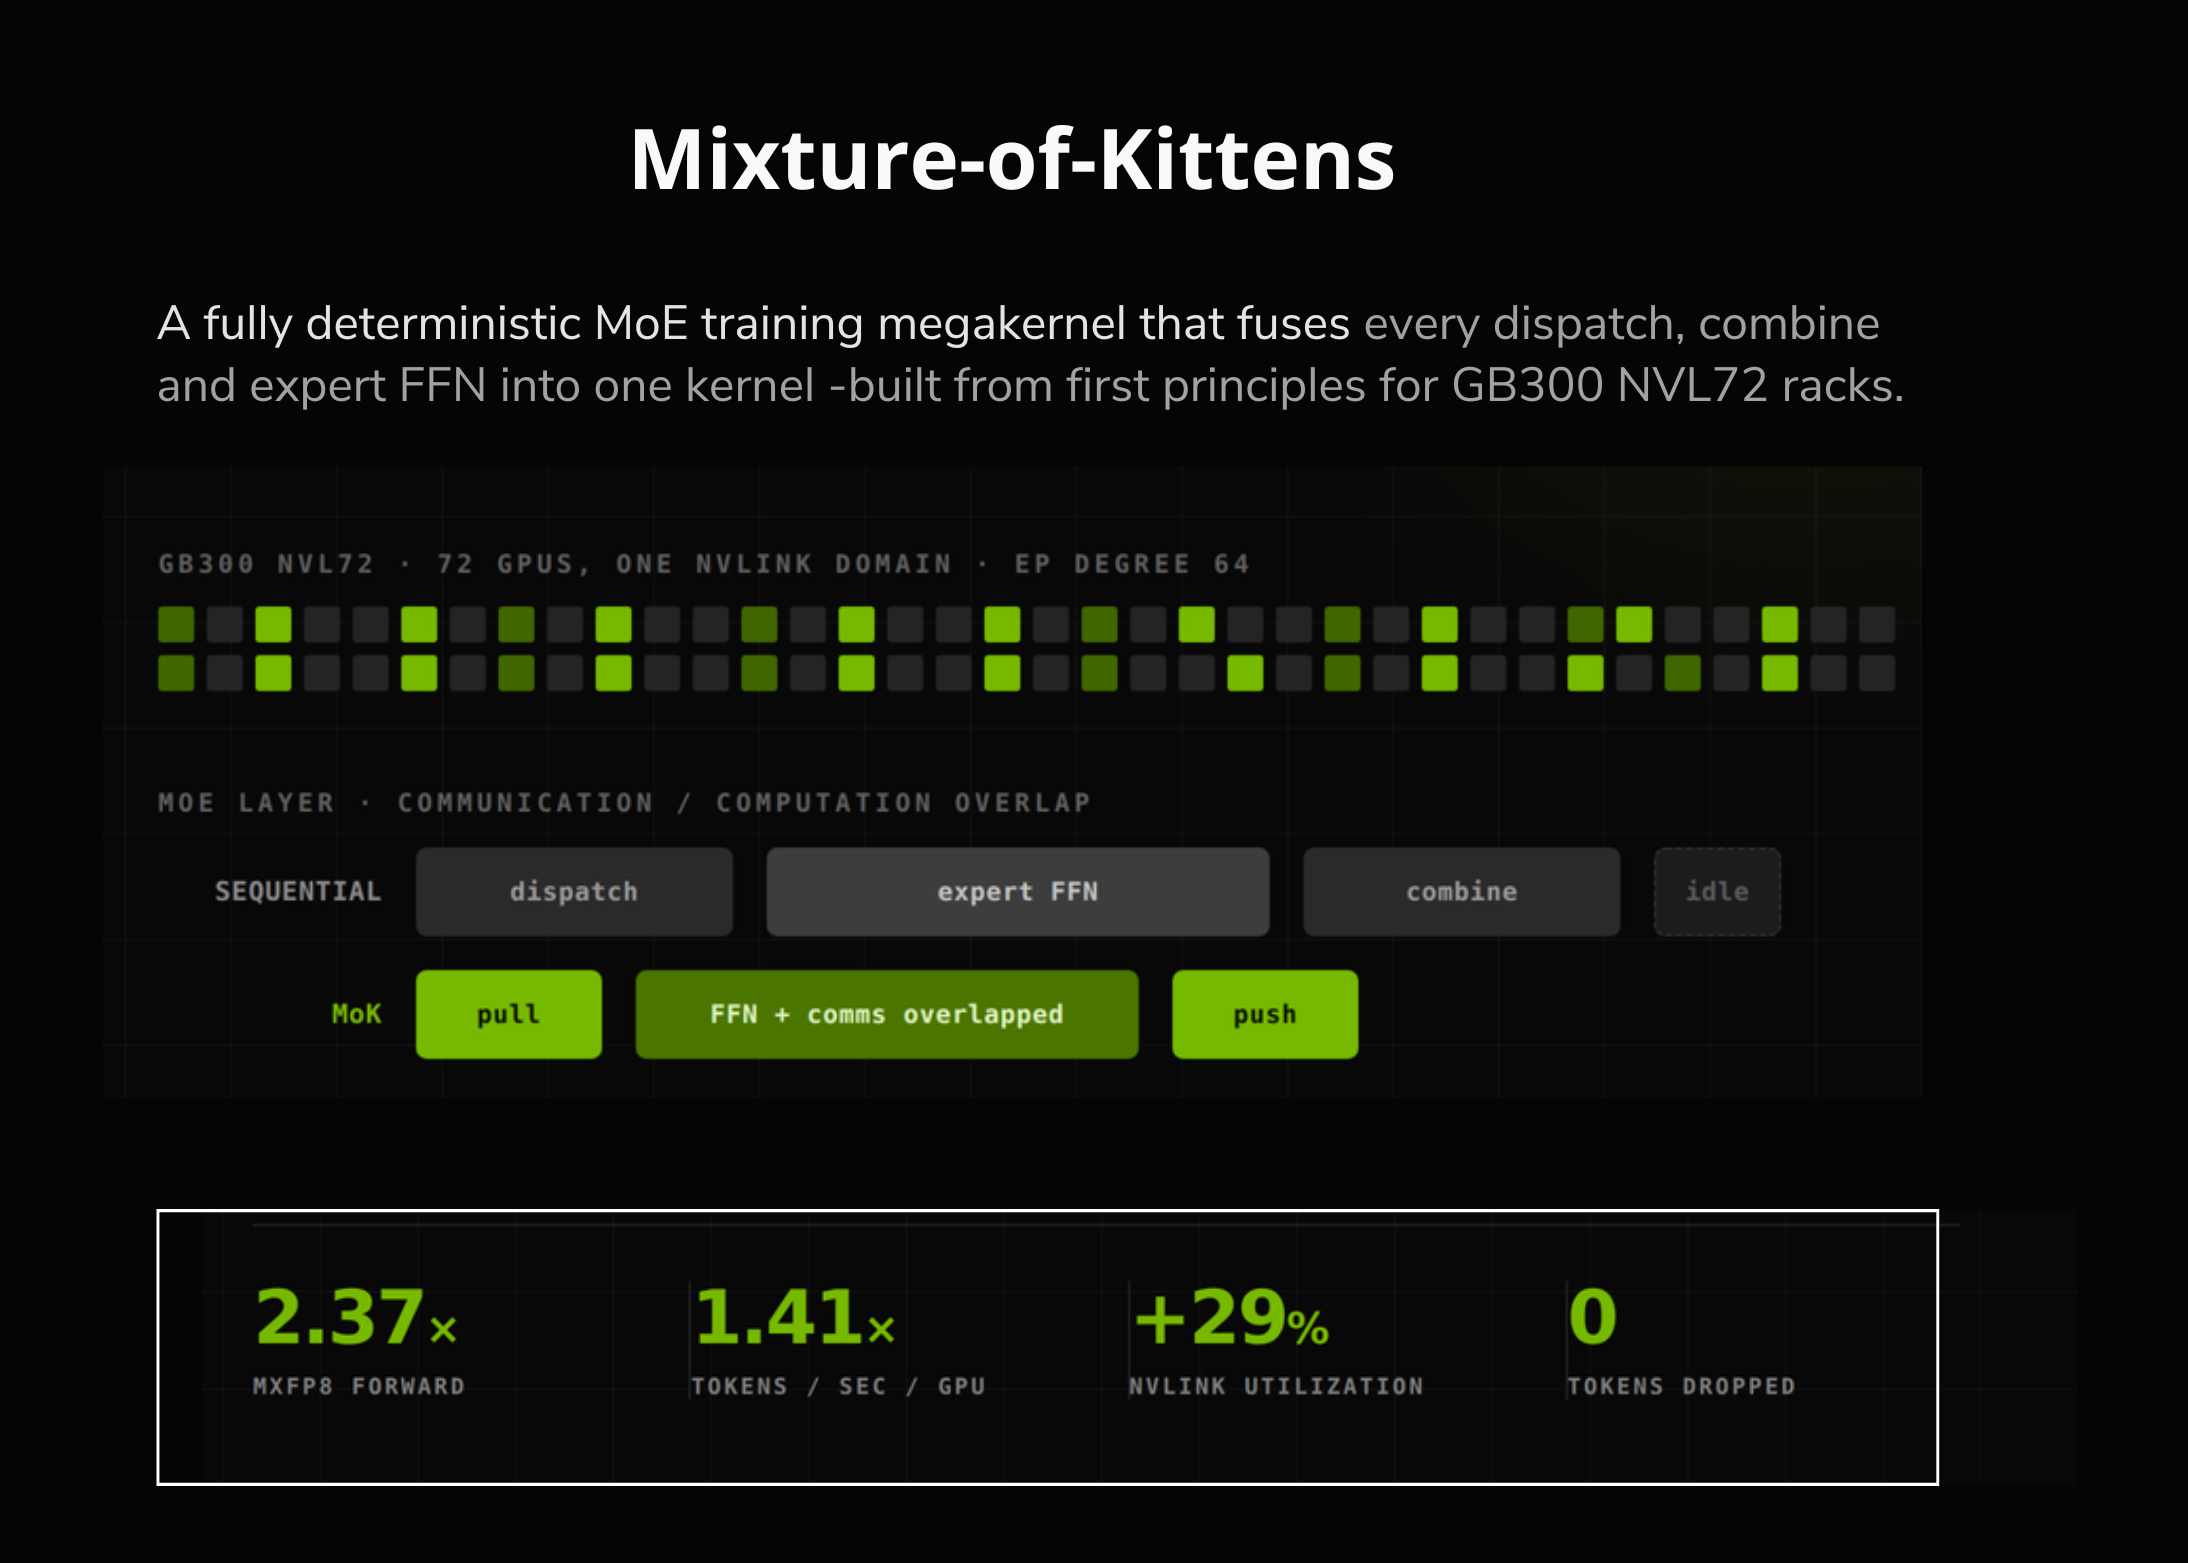
Cursor Open-Sources Mixture-of-Kittens (MoK): A Deterministic MoE Training Megakernel for GB300 NVL72 Racks
MarkTechPost
Machine Learning5 min read
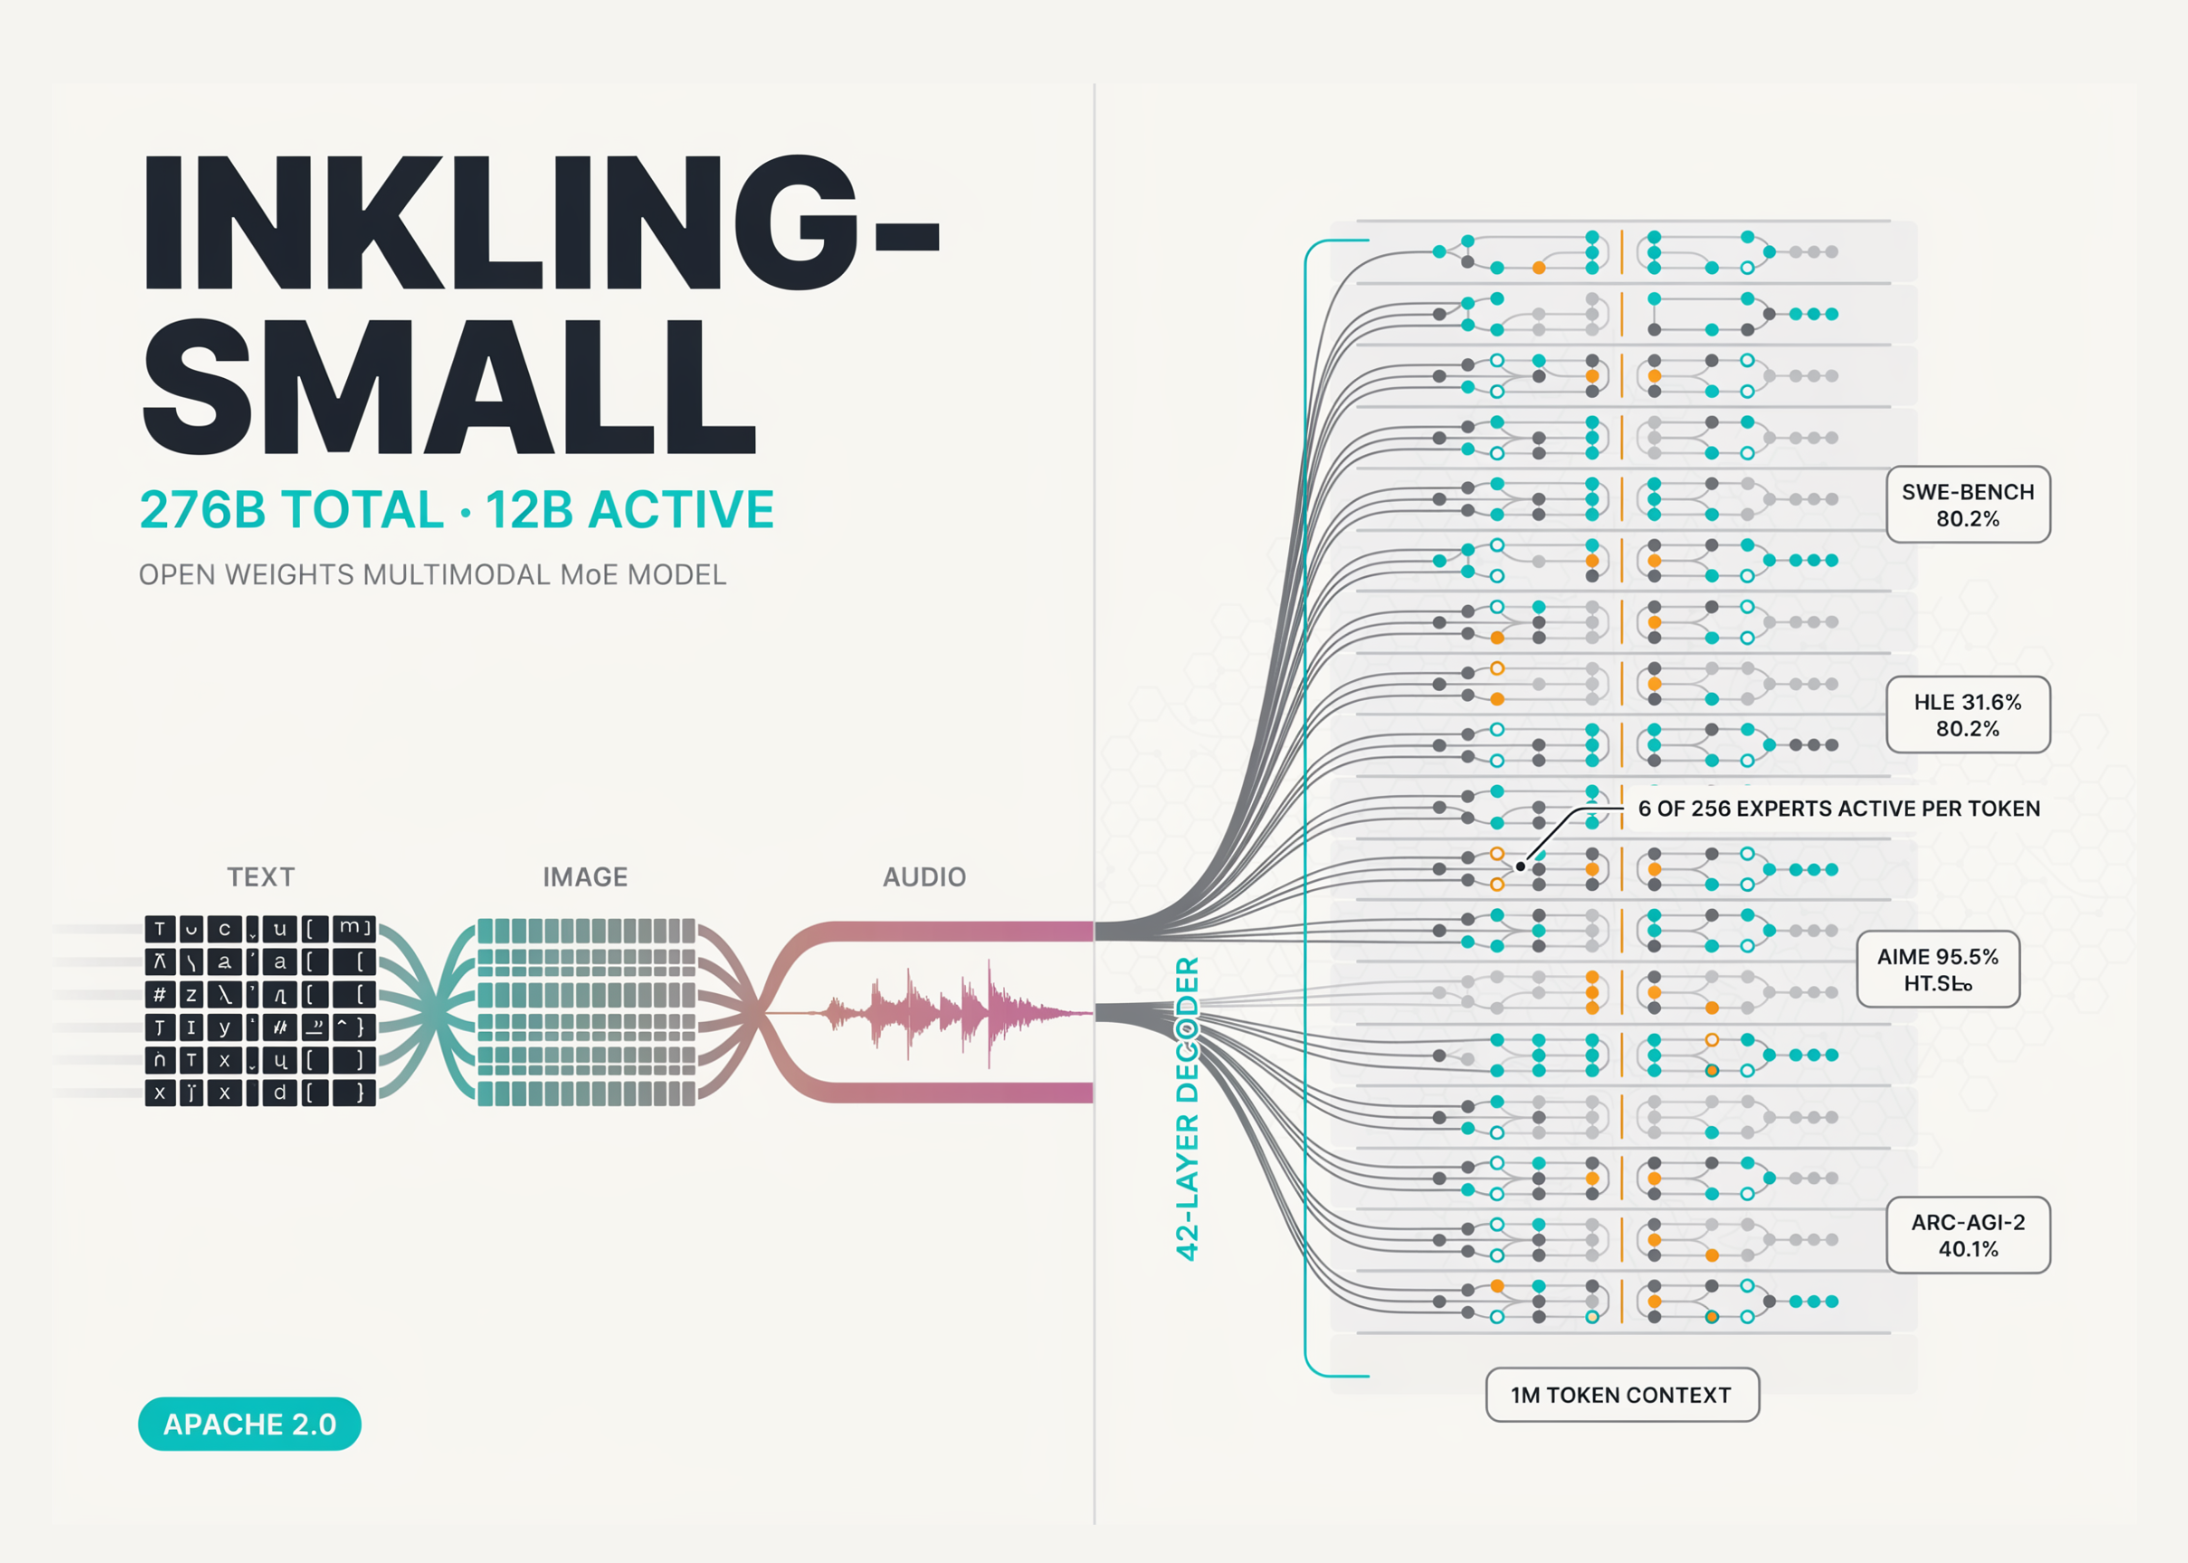
Thinking Machines Lab Releases Inkling-Small: A 276B Total, 12B Active Open Weights Multimodal MoE Model
MarkTechPost
LLM & Text Generation4 min read
AMD Releases Instella-MoE-16B-A3B: A Fully Open Mixture-of-Experts LLM With 2.8B Active Parameters Trained On Instinct GPUs
MarkTechPost

Machine Learning4 min read
DeepSeek Upgrades DeepSeek-V4-Flash-0731 with Major Agentic and Coding Gains
MarkTechPost
Machine Learning5 min read
Moonshot AI Open-Sources MoonEP: A Perfectly Balanced Expert Parallelism Library for MoE Training
MarkTechPost


That's everything we have on Mixture of Experts right now