


Updates on Model Deployment
Every AI story we track on Model Deployment: 24 stories so far, each summarized in our own words and linked to the publisher that reported it.
Pulled from 125 sources
This month
Machine Learning5 min read
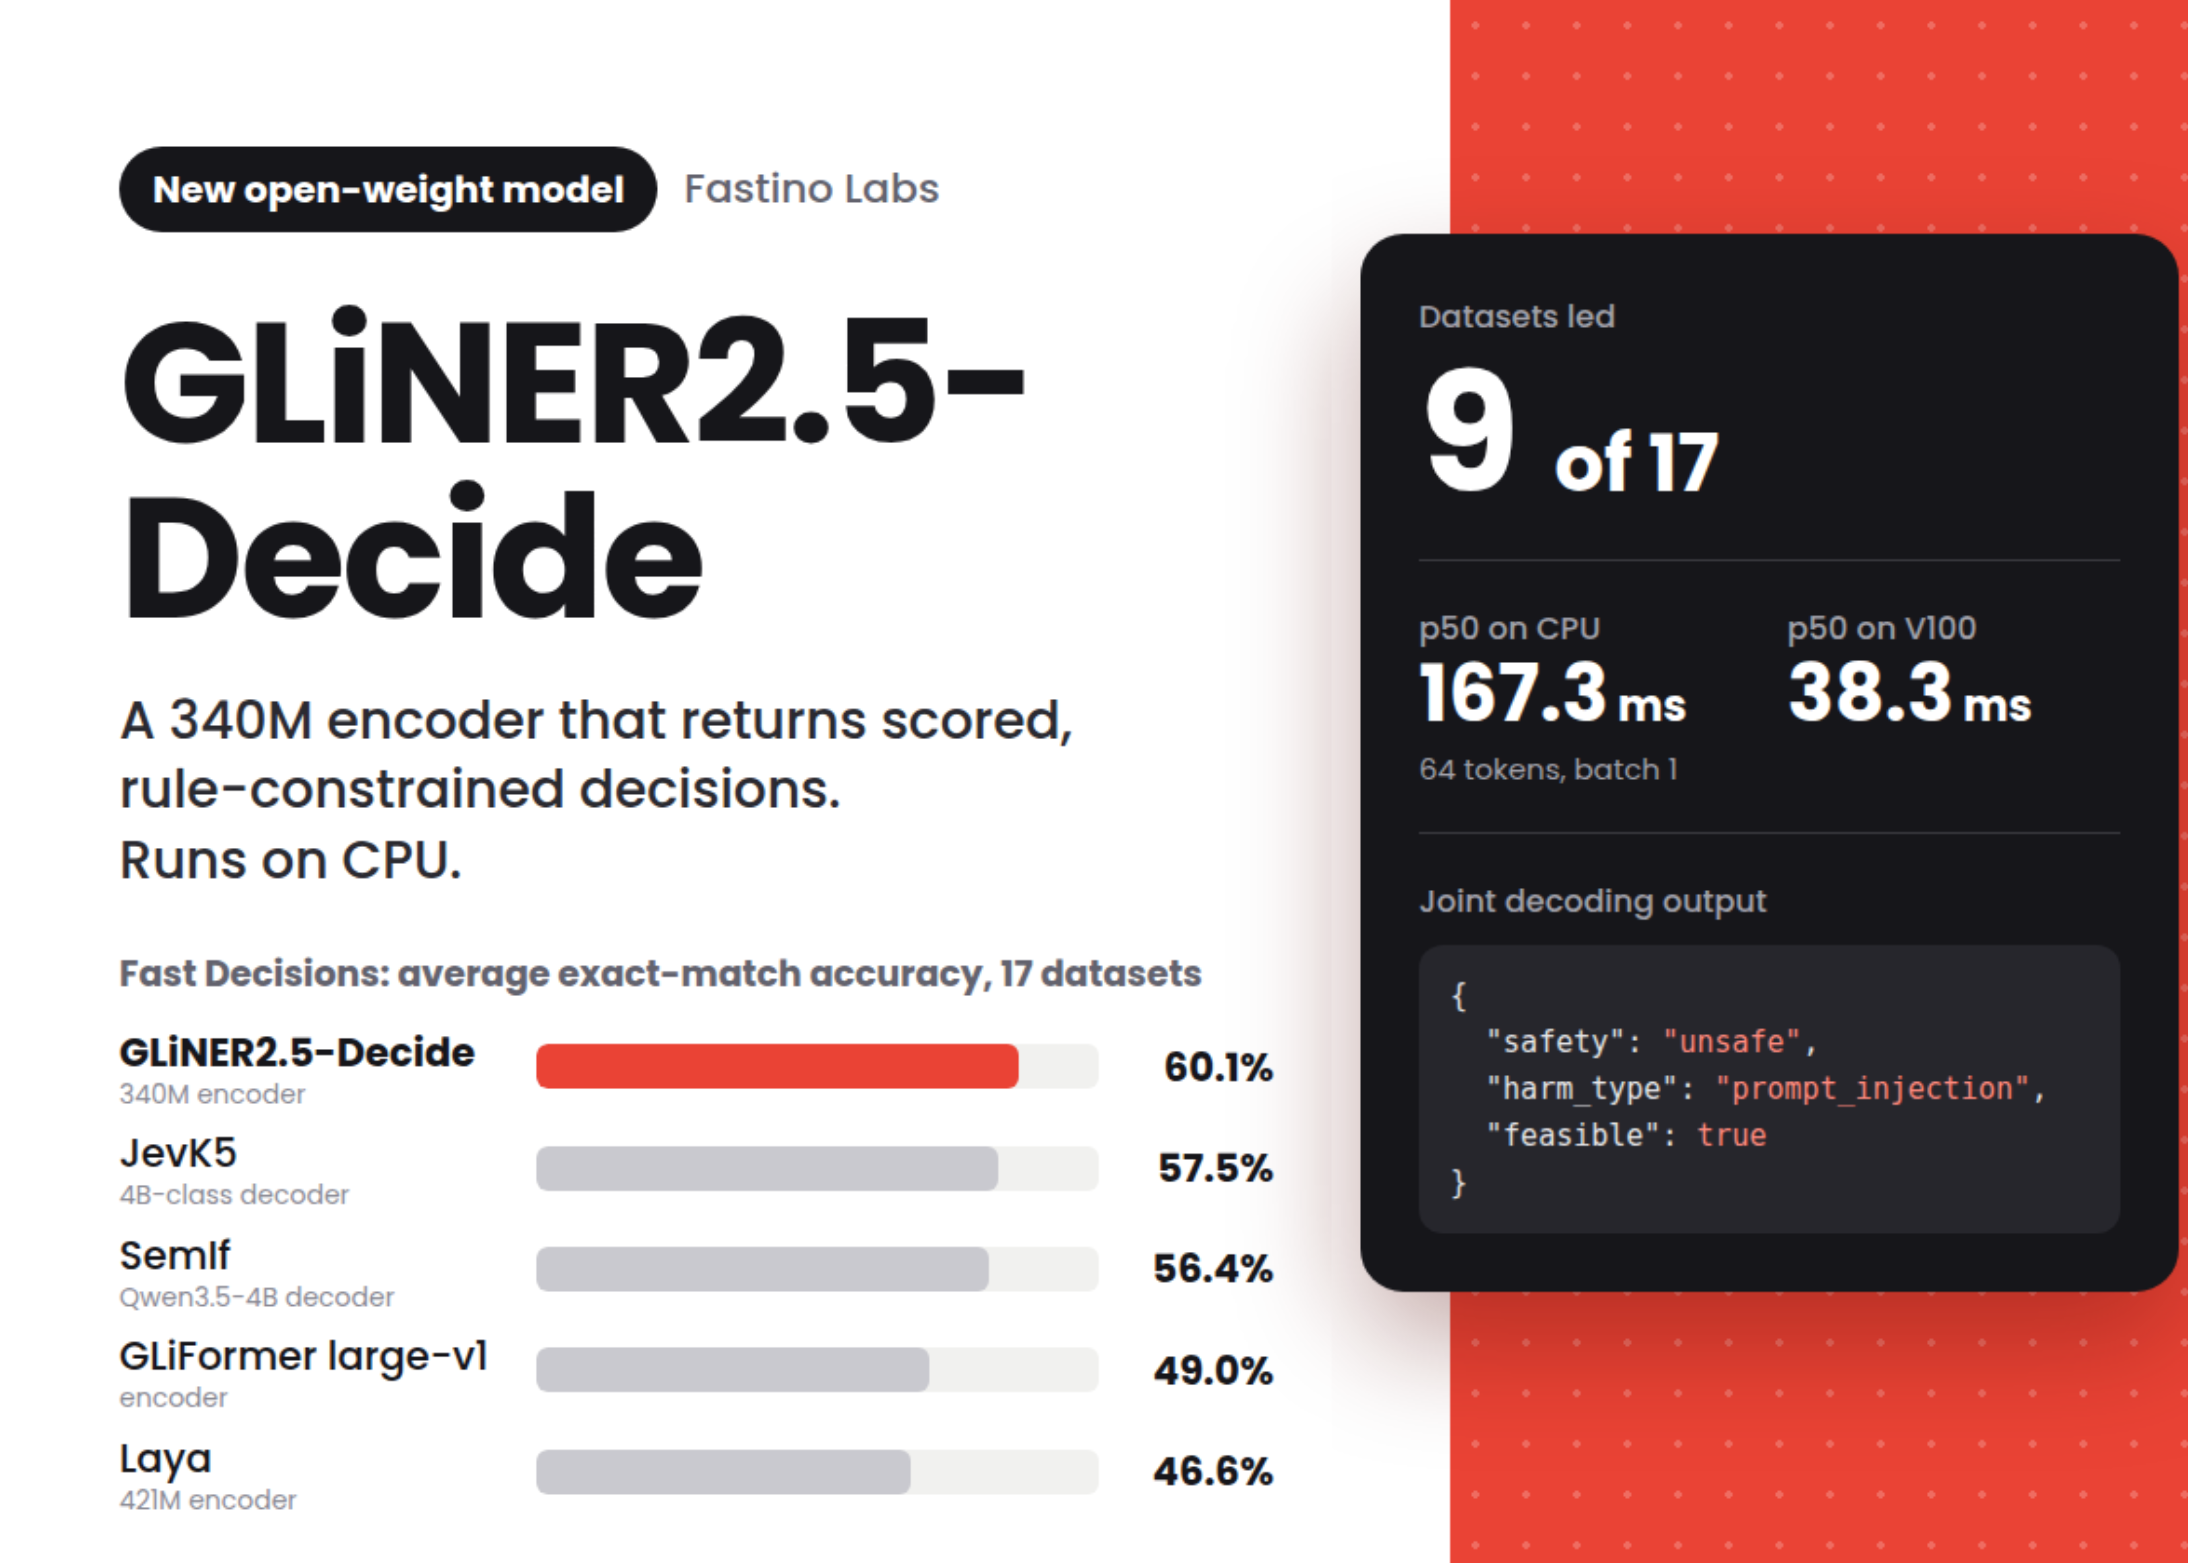
Fastino Releases GLiNER2.5-Decide: A 340M Open-Weight Decision Model That Runs on CPU
MarkTechPost
Business & Enterprise7 min read
Simplify and support your TorchServe workloads using Ray Serve Deep Learning Containers
AWS Blog

Machine Learning17 min read
Bring your own model with Amazon SageMaker AI: Script mode in SDK v3
AWS Blog
Dev4 min read
NVIDIA Releases TensorRT Model Connect in Public Preview: Hugging Face Checkpoint to Native C++ Inference in Two Commands
MarkTechPost

LLM & Text Generation2 min read
SpaceXAI releases Grok 4.6, claiming GPT-5.6 Sol and Claude Fable 5-level intelligence
Covered by 6 sources
AI Research6 min read
Mistral AI Releases Shieldstral 1.0 3B: An Open-Weights Policy-Adaptive Multimodal Safety Classifier Matching Models 7× Its Size
MarkTechPost
Machine Learning5 min read
From Hugging Face to Amazon SageMaker Studio in one click
Covered by 2 sources

Cost effective deployment of vision-language models for pet behavior detection on AWS Inferentia2
AWS Blog

Startup Gimlet Labs is solving the AI inference bottleneck in a surprisingly elegant way
TechCrunch

Accelerate custom LLM deployment: Fine-tune with Oumi and deploy to Amazon Bedrock
AWS Blog
That's everything we have on Model Deployment right now