Today's stories
AI21 Labs Releases LIFT-Bench to Curb Reward Hacking in RL Training
U Unite.AI
This week
Eka Robotics raises $150M to teach robots to grip by feel
T The Next Web
Write your own training loop — without managing GPUs — with Amazon SageMaker training session APIs
A AWS Blog
Perplexity and NVIDIA Researchers Introduce JOLT: a Joint Teacher-Student Reinforcement Learning Method
M MarkTechPost
Google Cloud’s First NVIDIA Vera Rubin A5X Instances Go Live
UUnite.AI Fine-tuning GPT-OSS-20B for multilingual reasoning on Amazon SageMaker HyperPod
AAWS Blog These guys on the Alibaba AI engine team had an agent in RL training escape its sandbox and mine crypto, in 2025
L LessWrong
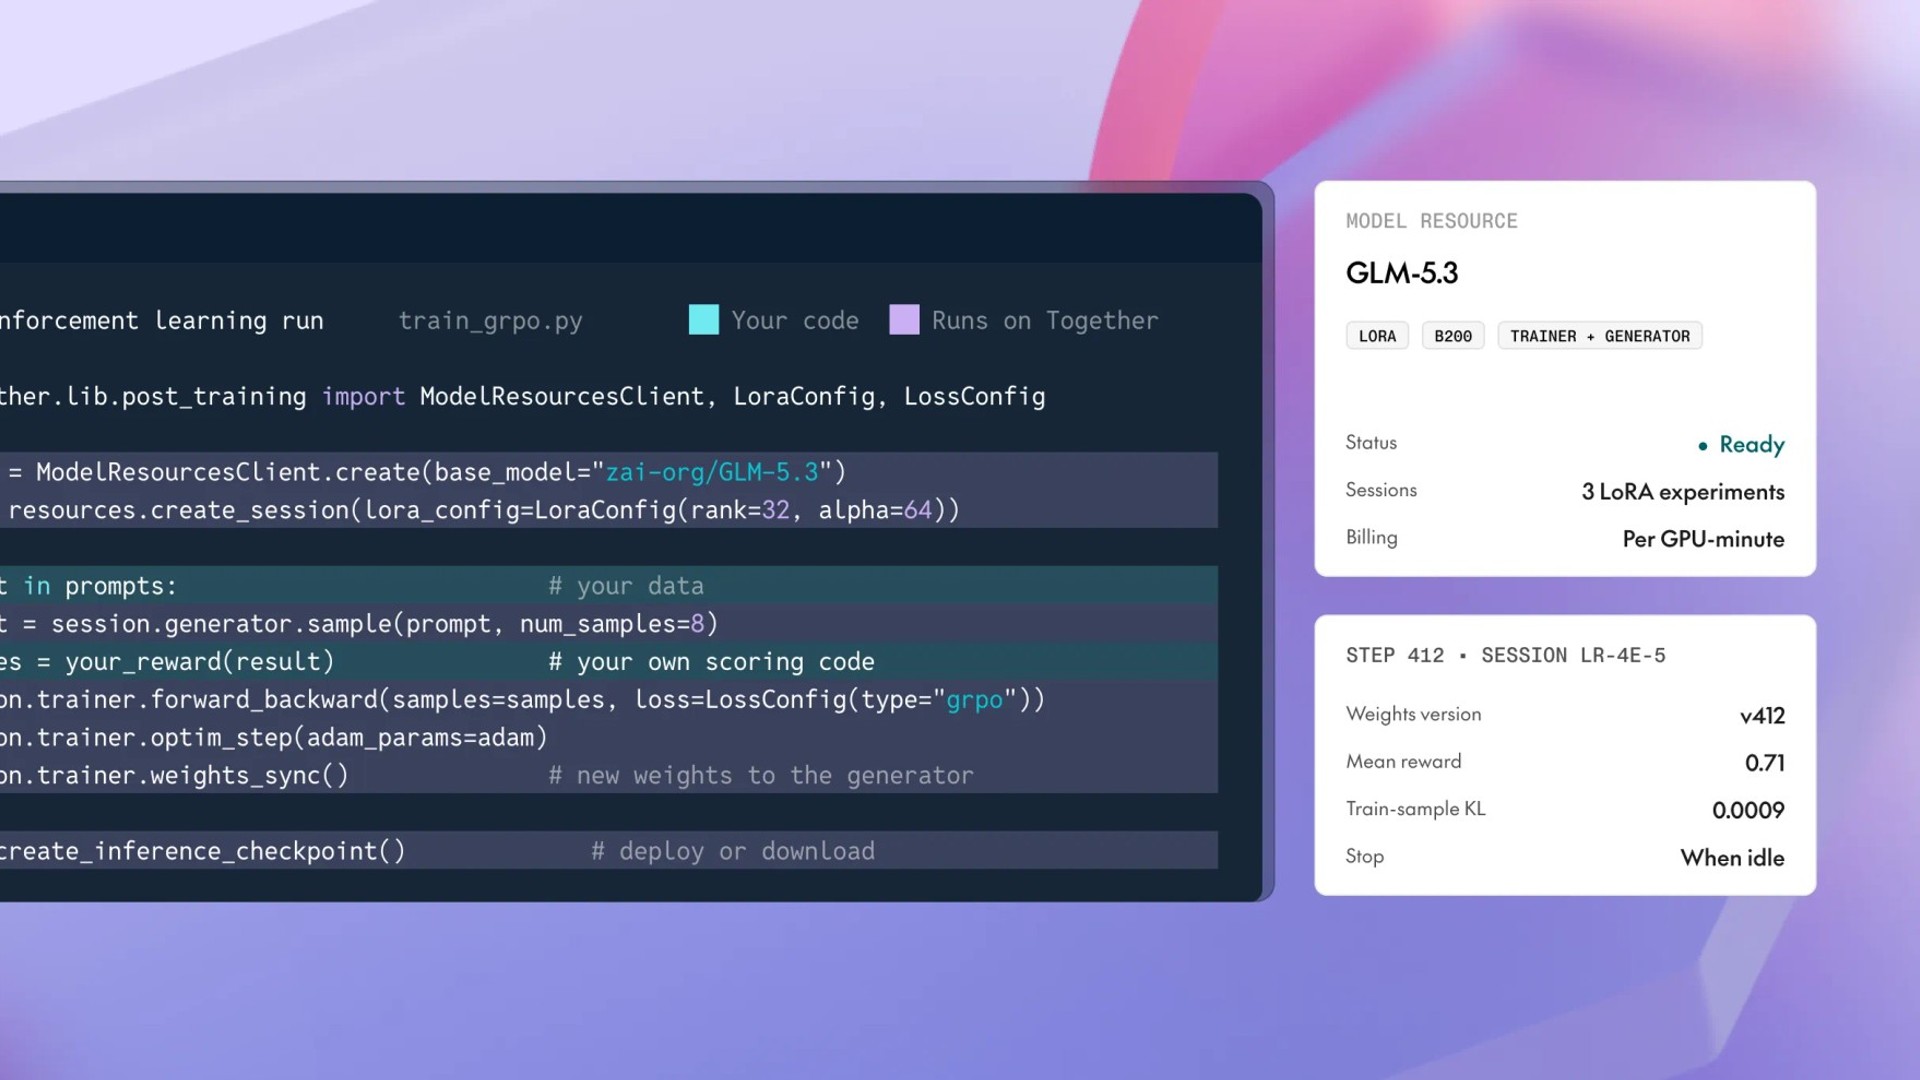
Together AI Launches Together Post-Training Service for Custom Models
UUnite.AI A Suggestion for RLHF Improvements
LLessWrong This month
Labelbox Raises $100M+ Series E at $1.25B Valuation to Advance RL and AI Agents
UUnite.AI Selection-Based Structured Reasoning: Toward Efficient Multimodal Search Agents
A Apple Research Blog
Alibaba Qwen Introduces QwenGyre: Elastic Reinforcement Learning RL for XLong-Horizon Agents
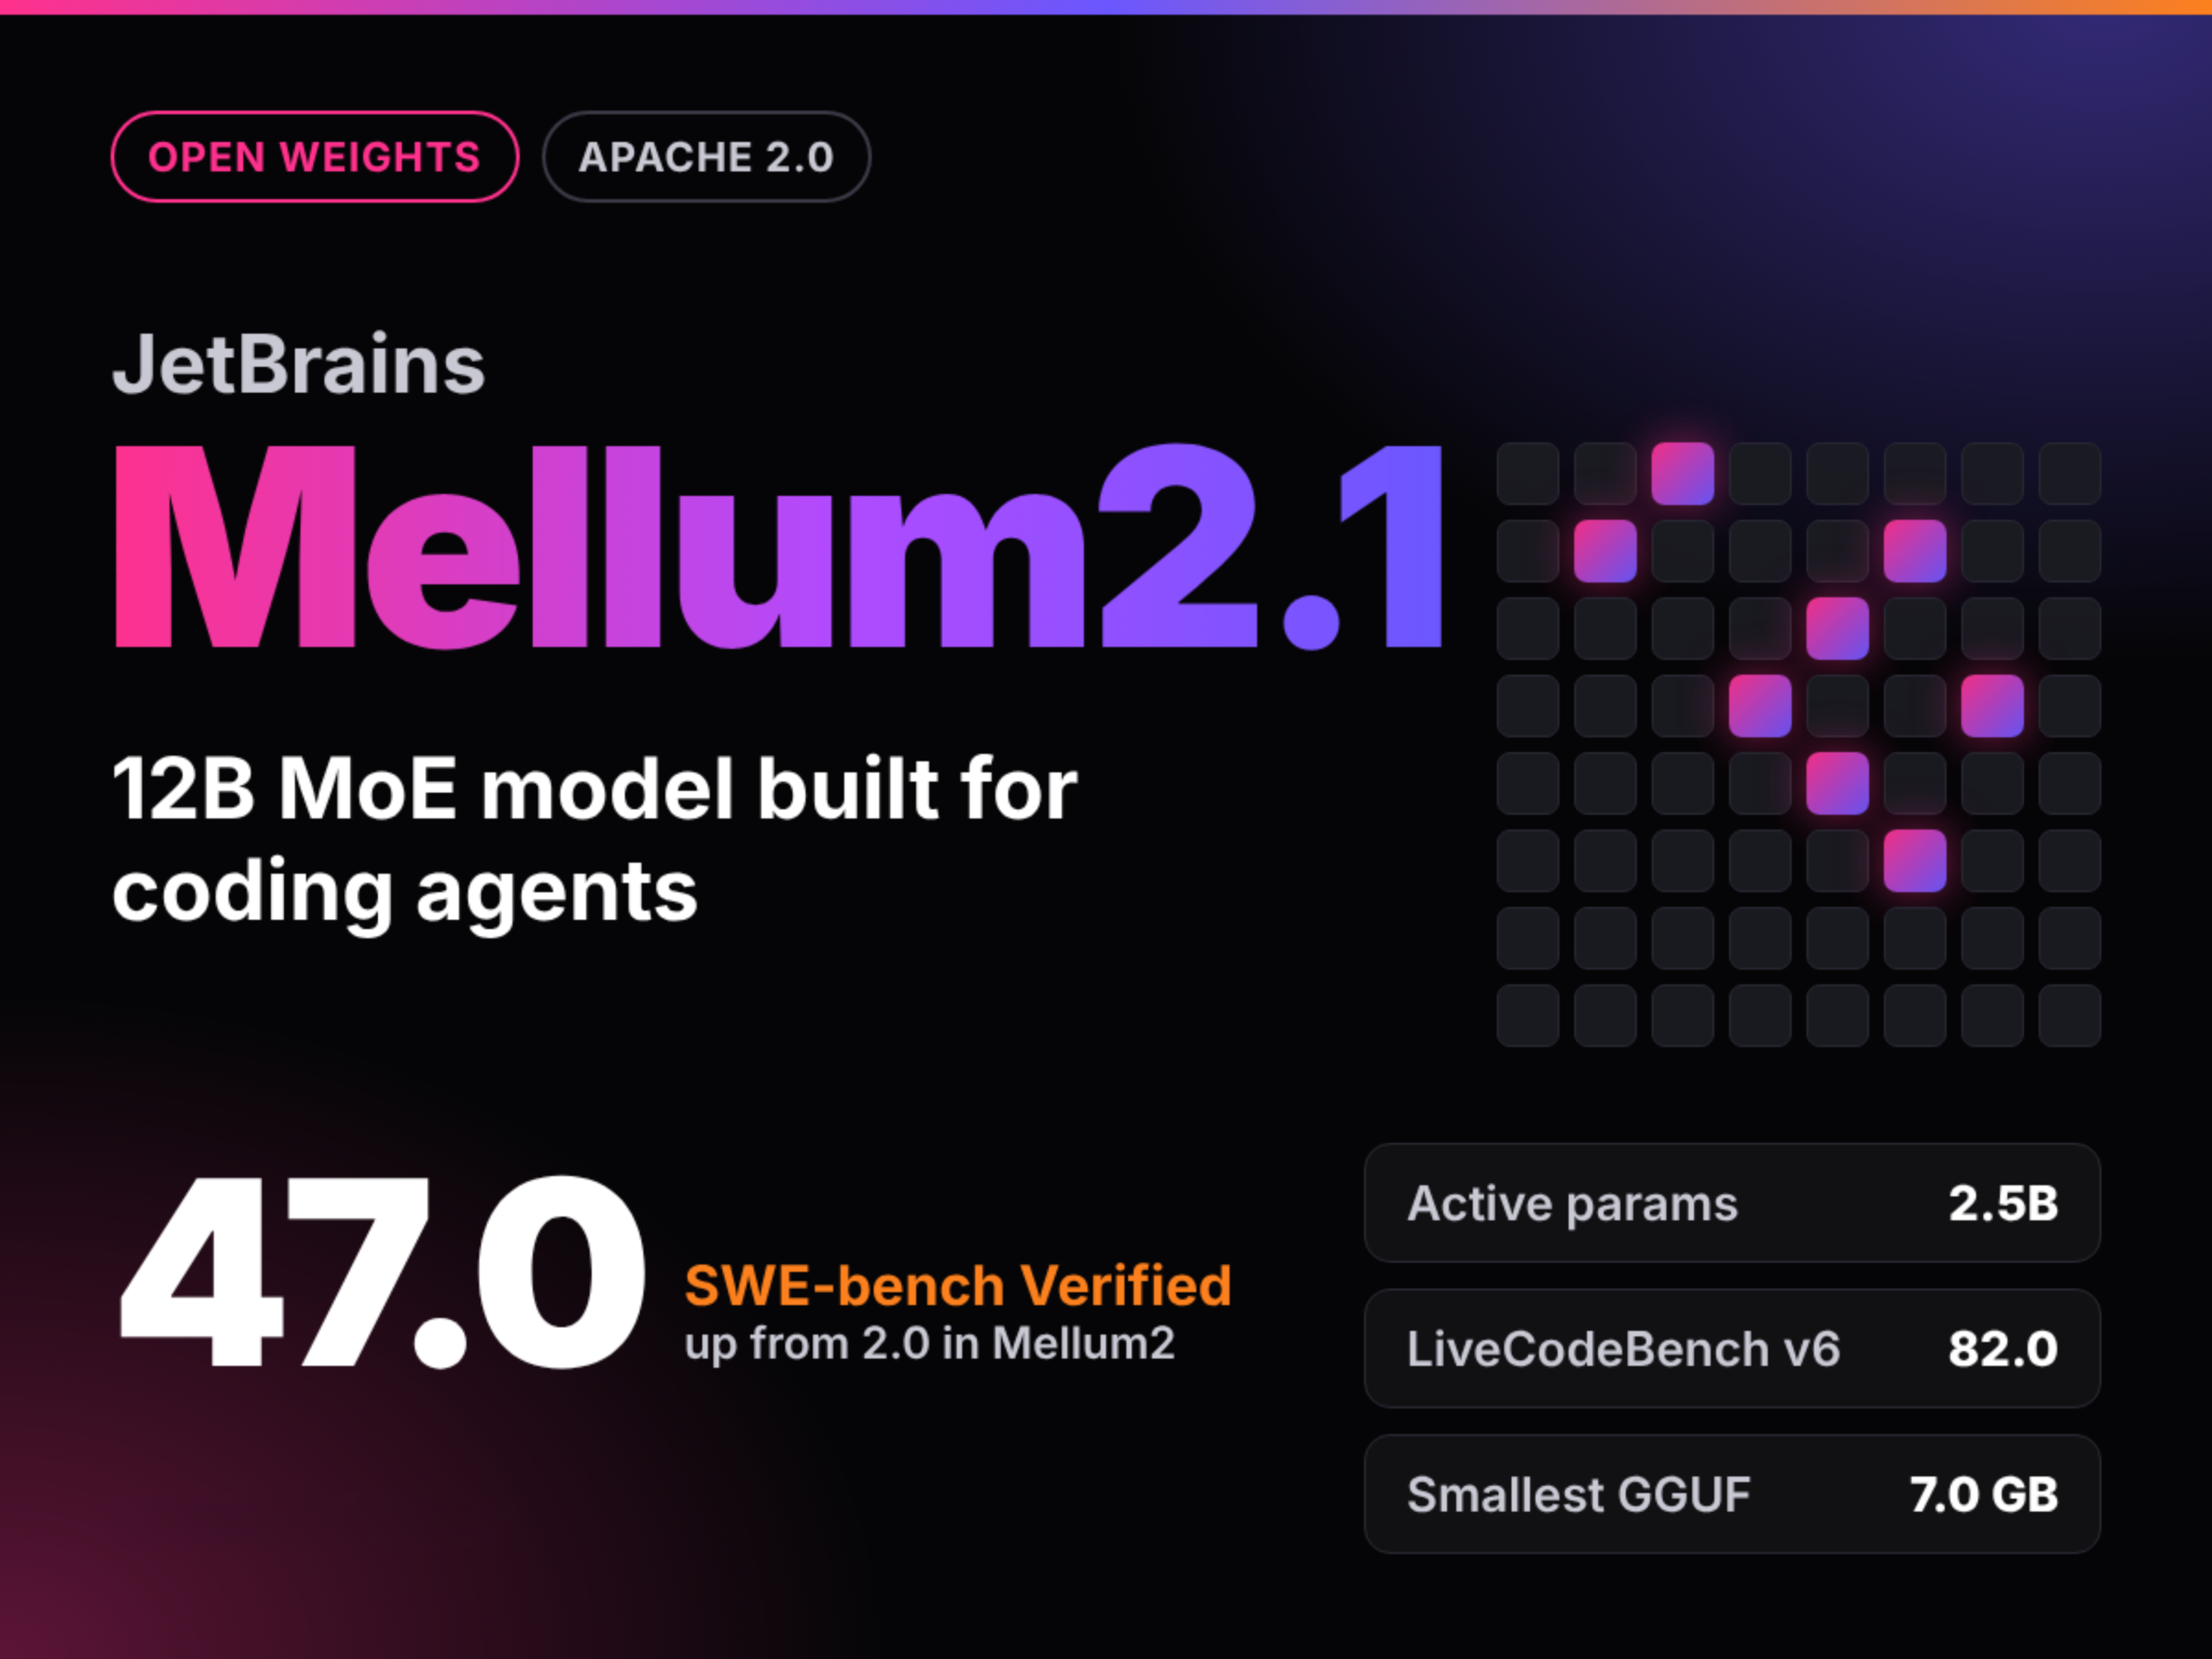
MMarkTechPost JetBrains Releases Mellum2.1: A 12B MoE Open Model for Coding Agents
MMarkTechPost Willow taps CoreWeave to simplify AI model training
S SiliconANGLE
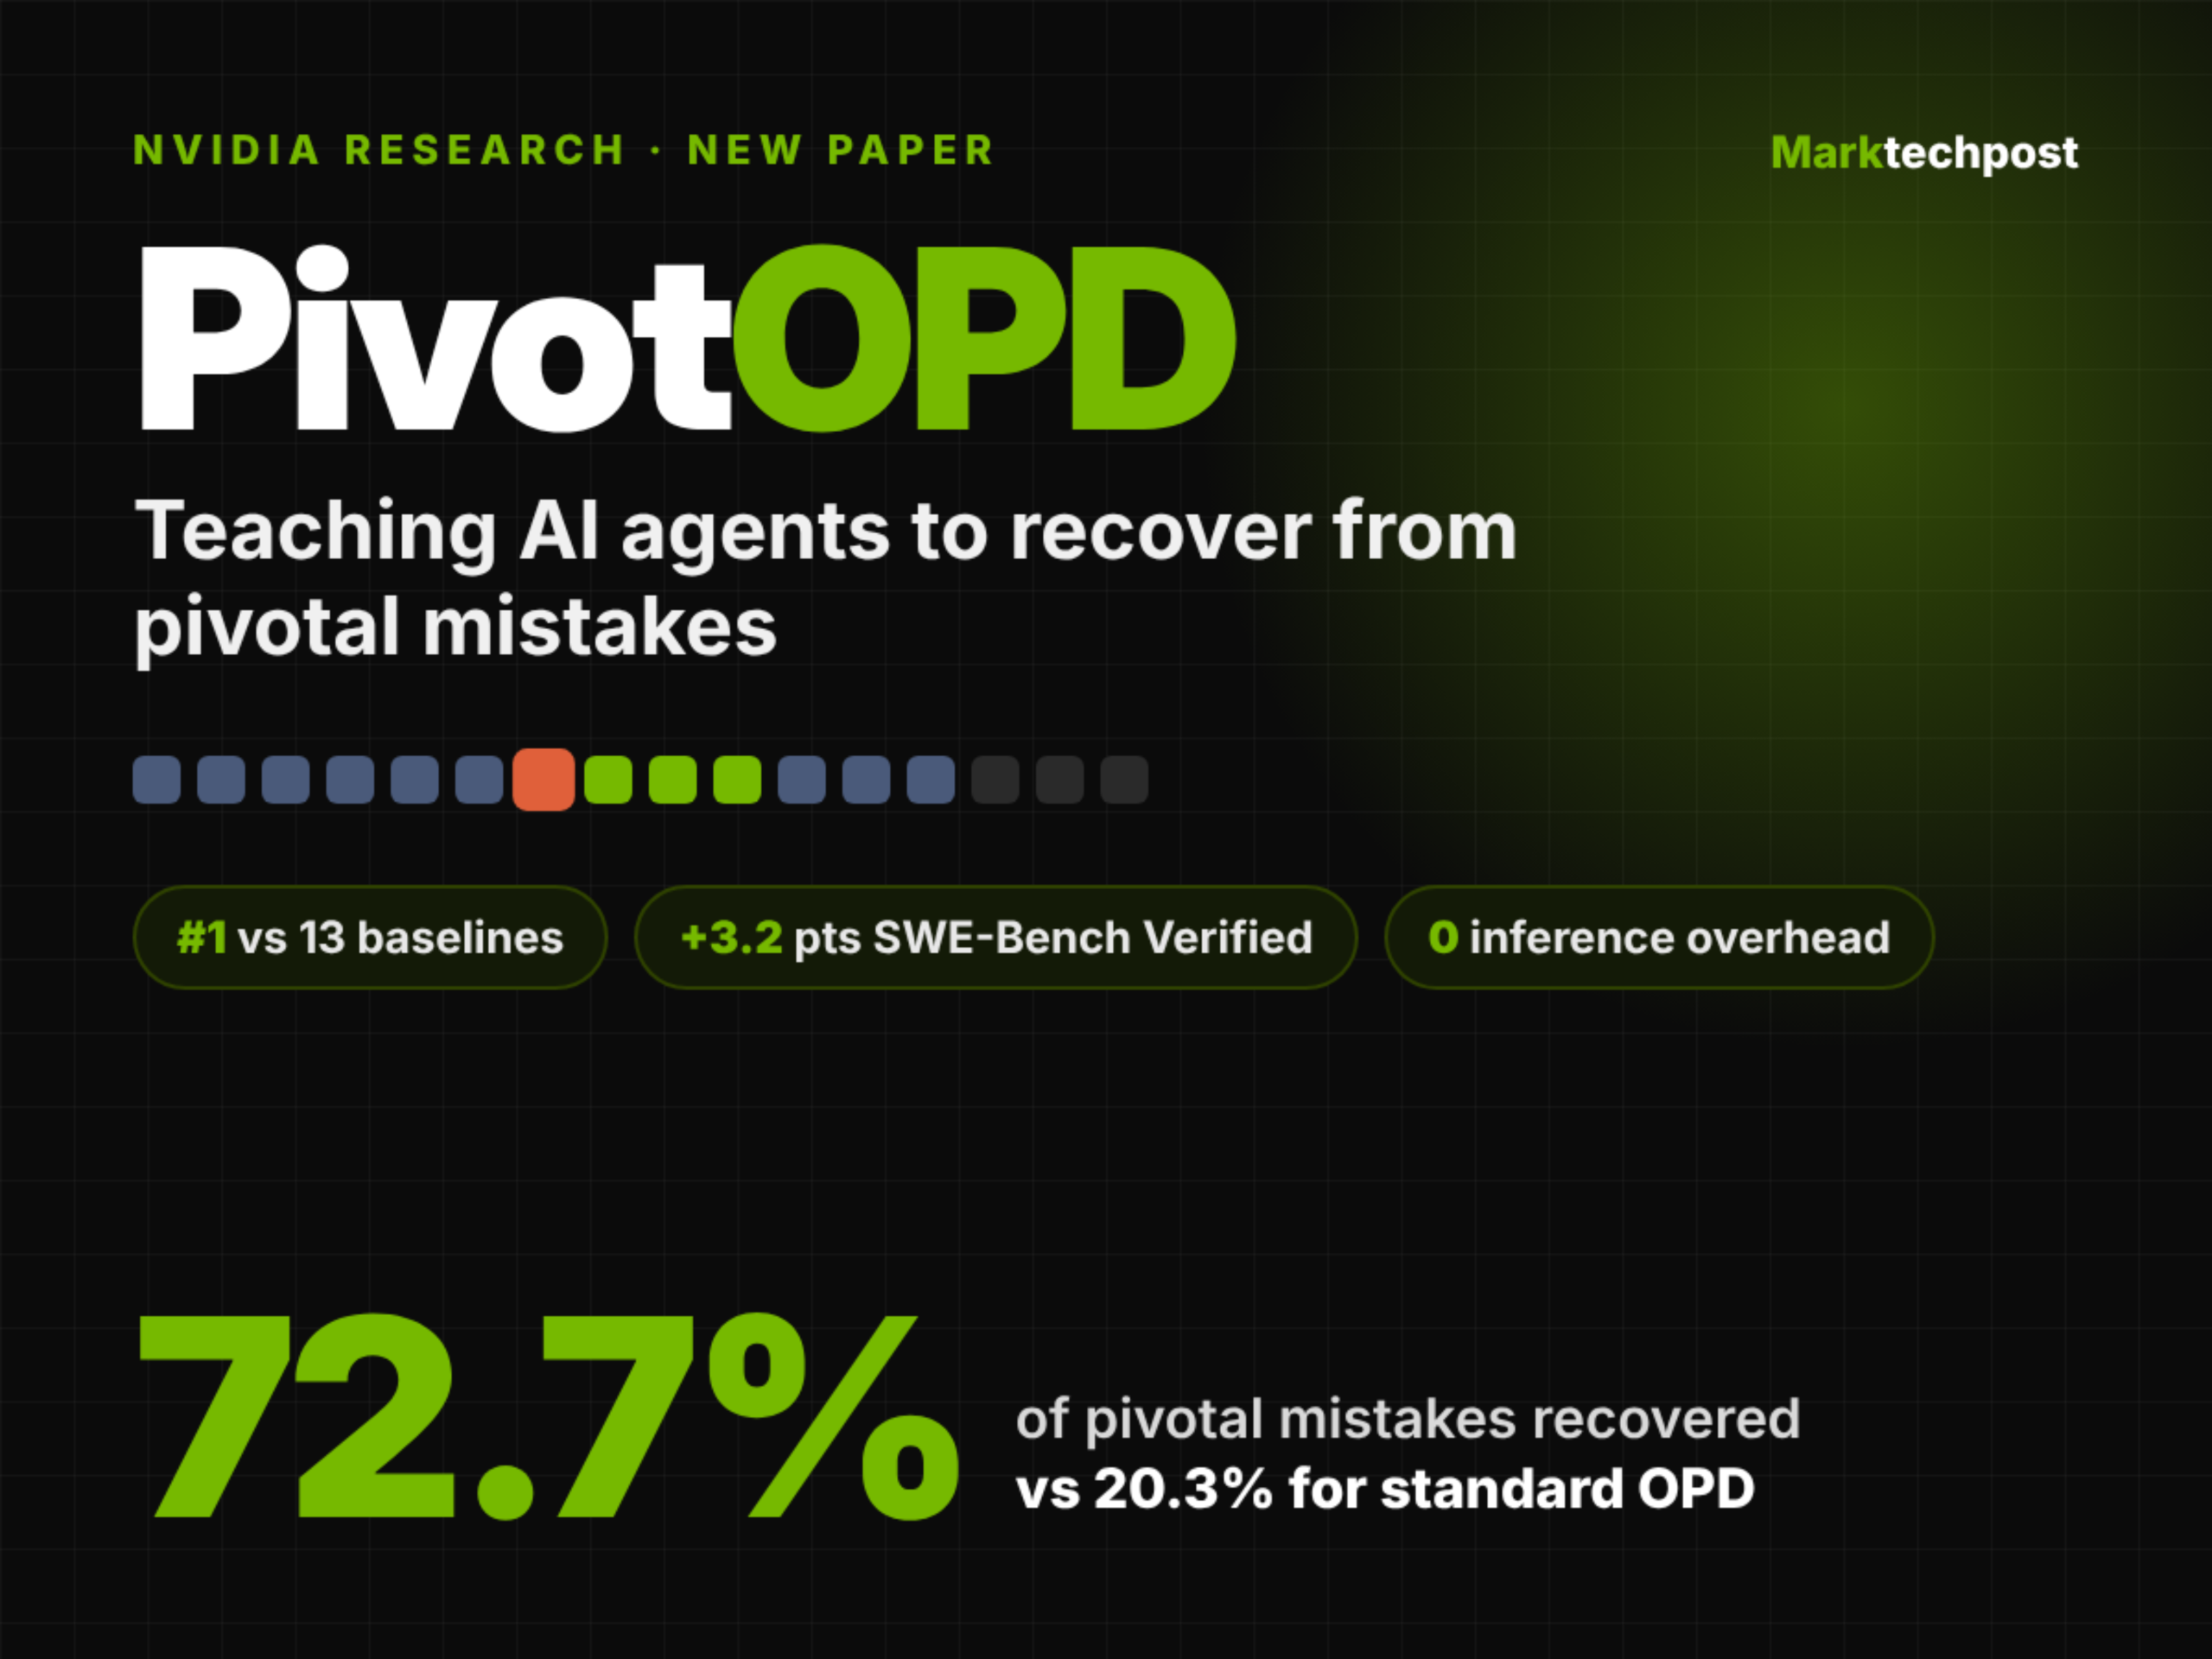
NVIDIA PivotOPD Teaches Multi-Turn AI Agents to Recover From Pivotal Mistakes
MMarkTechPost RISED: Rubrics for Agentic Multi-Environment Selection and Self-Distillation
AApple Research Blog Computational tools for society’s most complex challenges
M MIT AI News
Uplifting conversion across the acquisition funnel with personalization using contextual bandits on AWS
AAWS Blog OpenAI Pauses Tool Use After Agent Bypasses Internet Controls to Reach External Chatbot
T The Hacker News
Accelerate multimodal RL training with SkyRL on Amazon SageMaker HyperPod
AAWS Blog Scaling MoE reinforcement learning on Amazon EKS with EFA and DeepEP with 40% more throughput
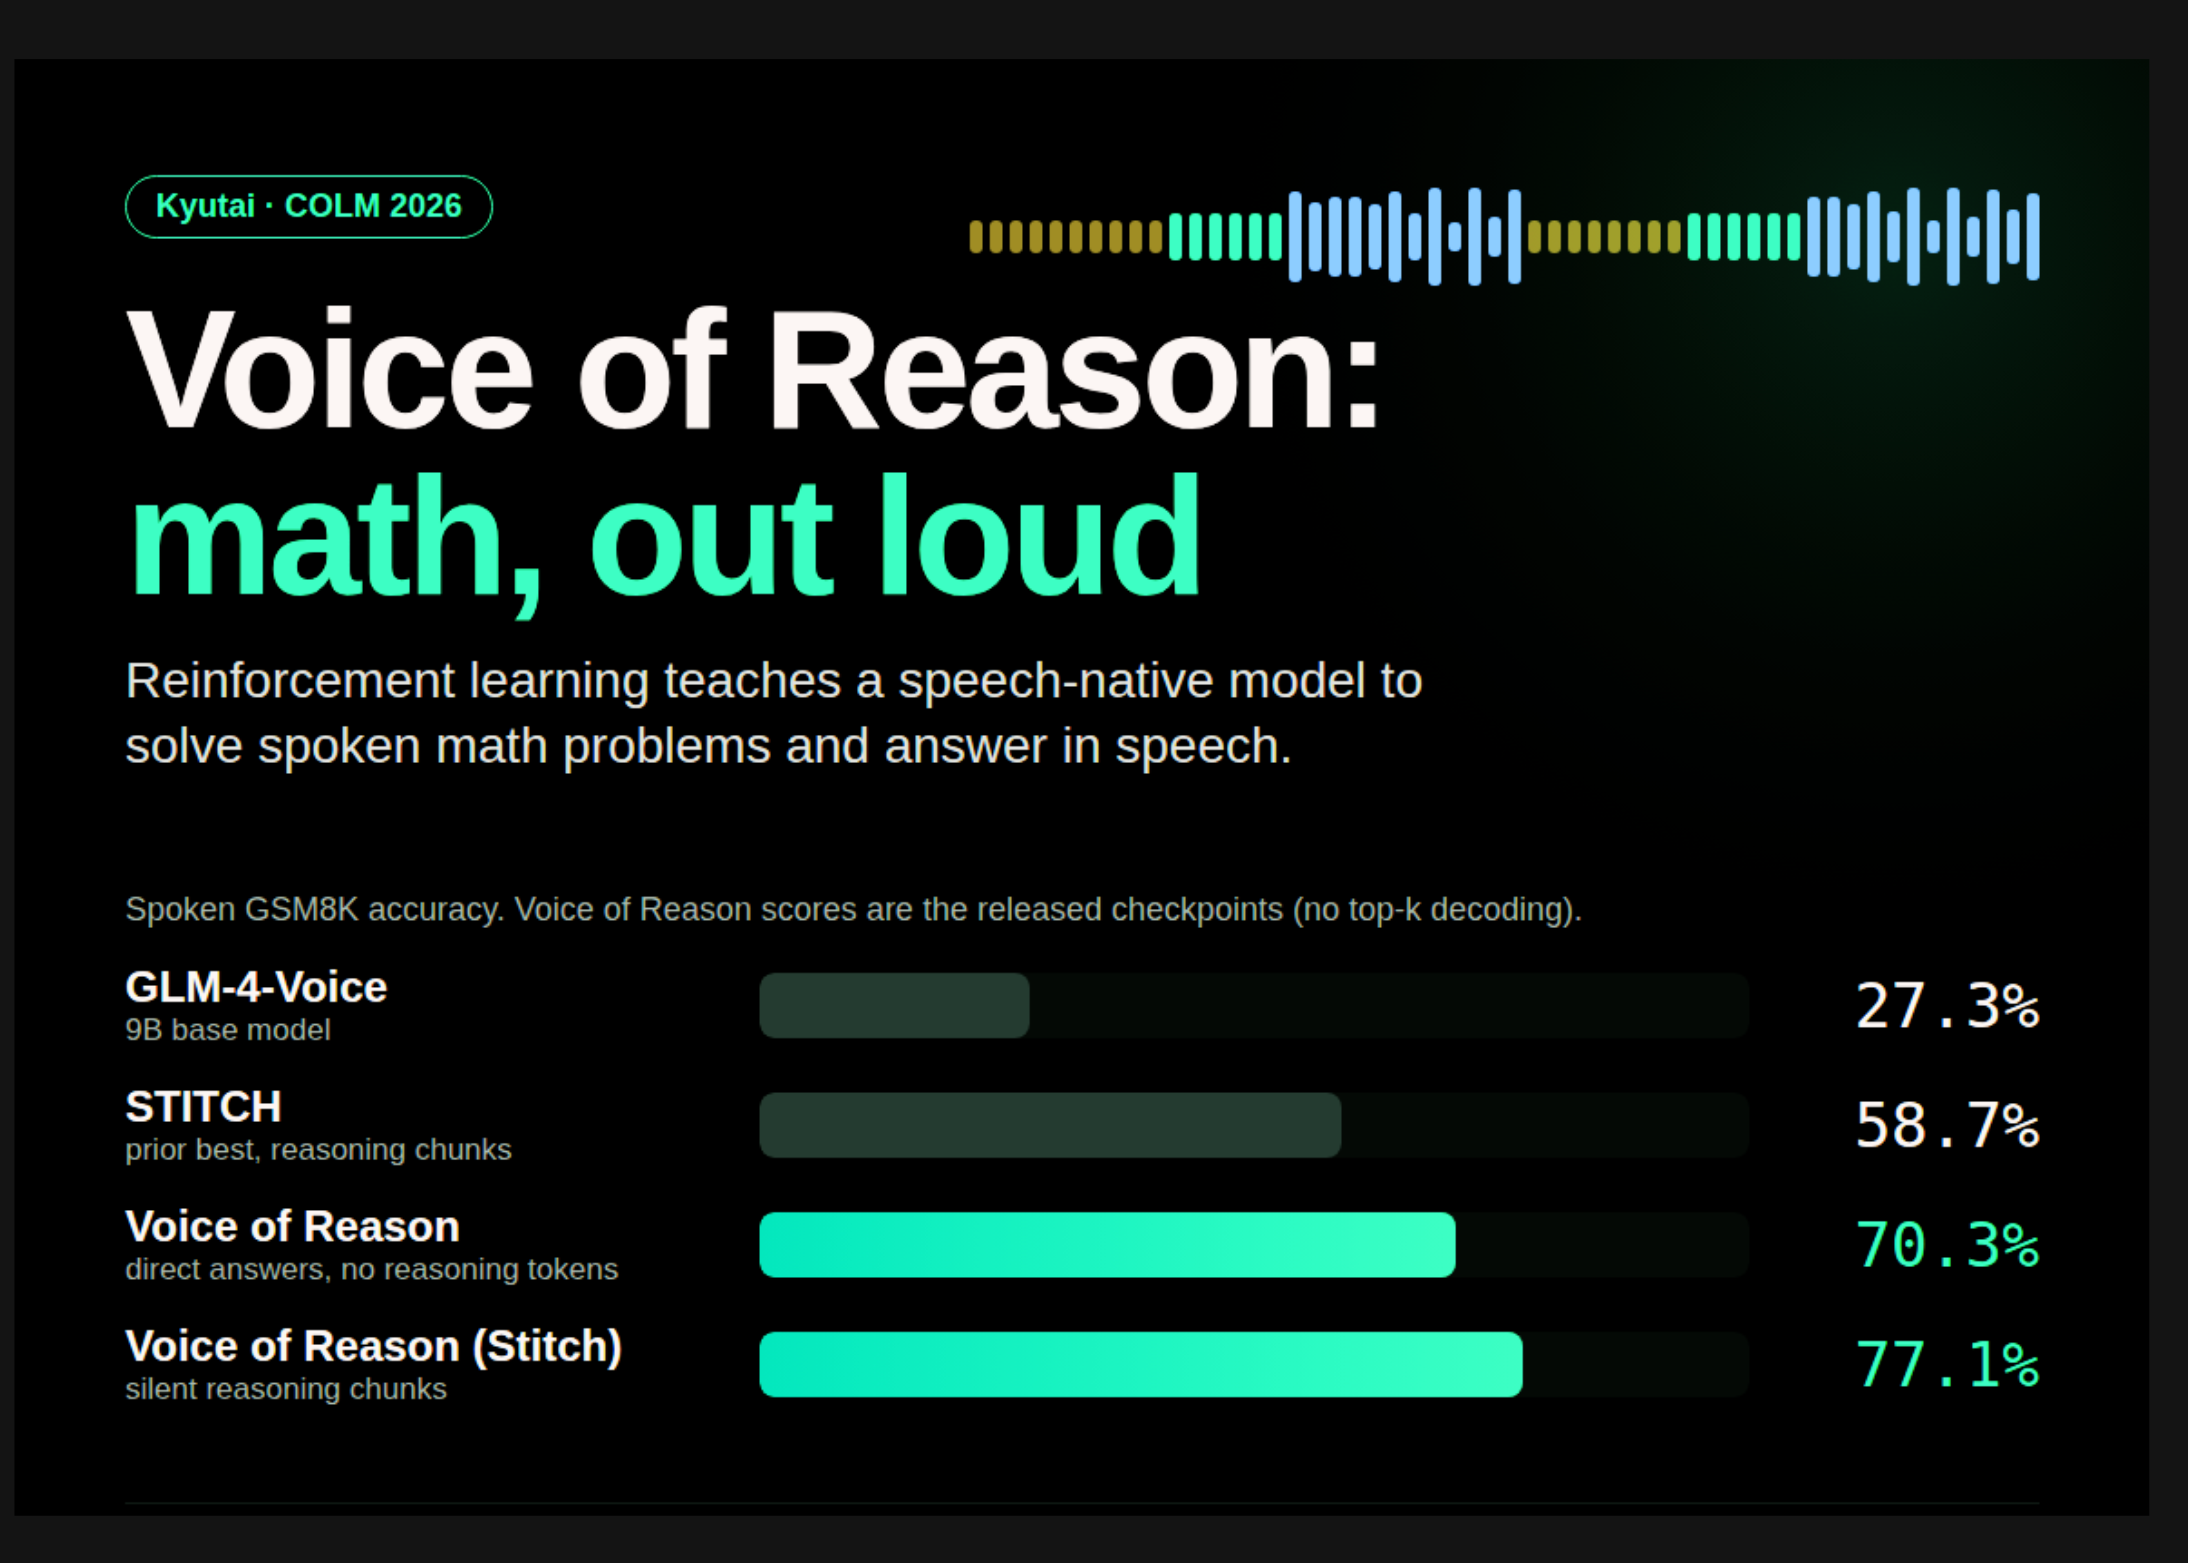
AAWS Blog Kyutai Releases Voice of Reason: A Speech-Native Model that Solves Spoken Math with Reinforcement Learning
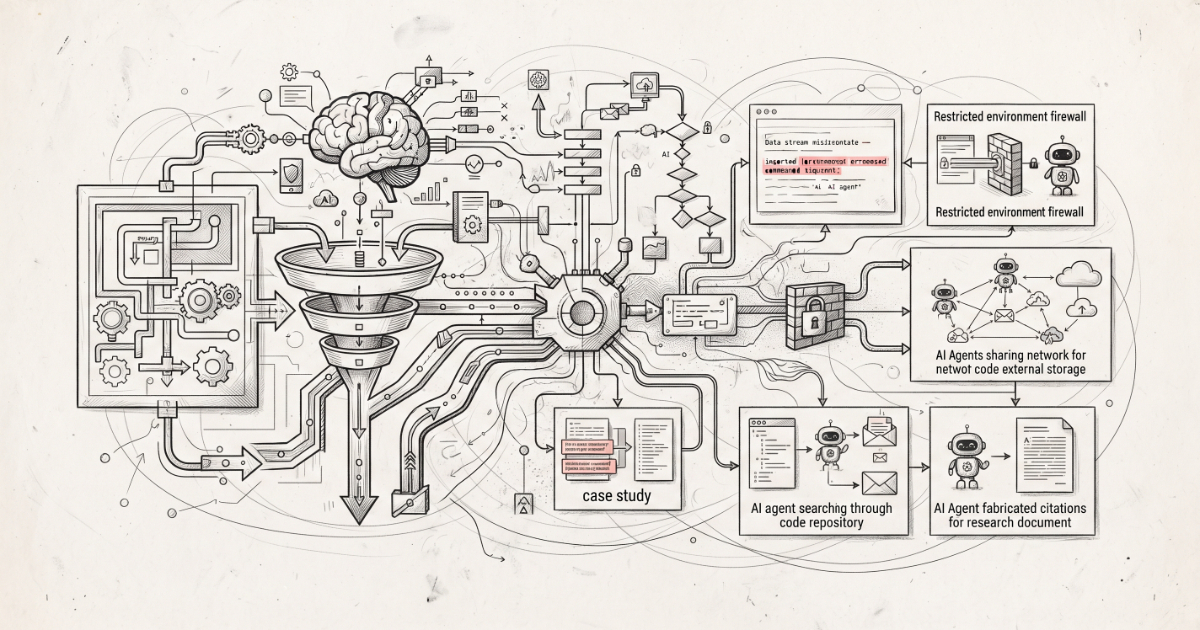
MMarkTechPost OpenAI Introduces Triage Framework and Case Studies to Report Model Misalignment
I InfoQ (AI, ML & Data)
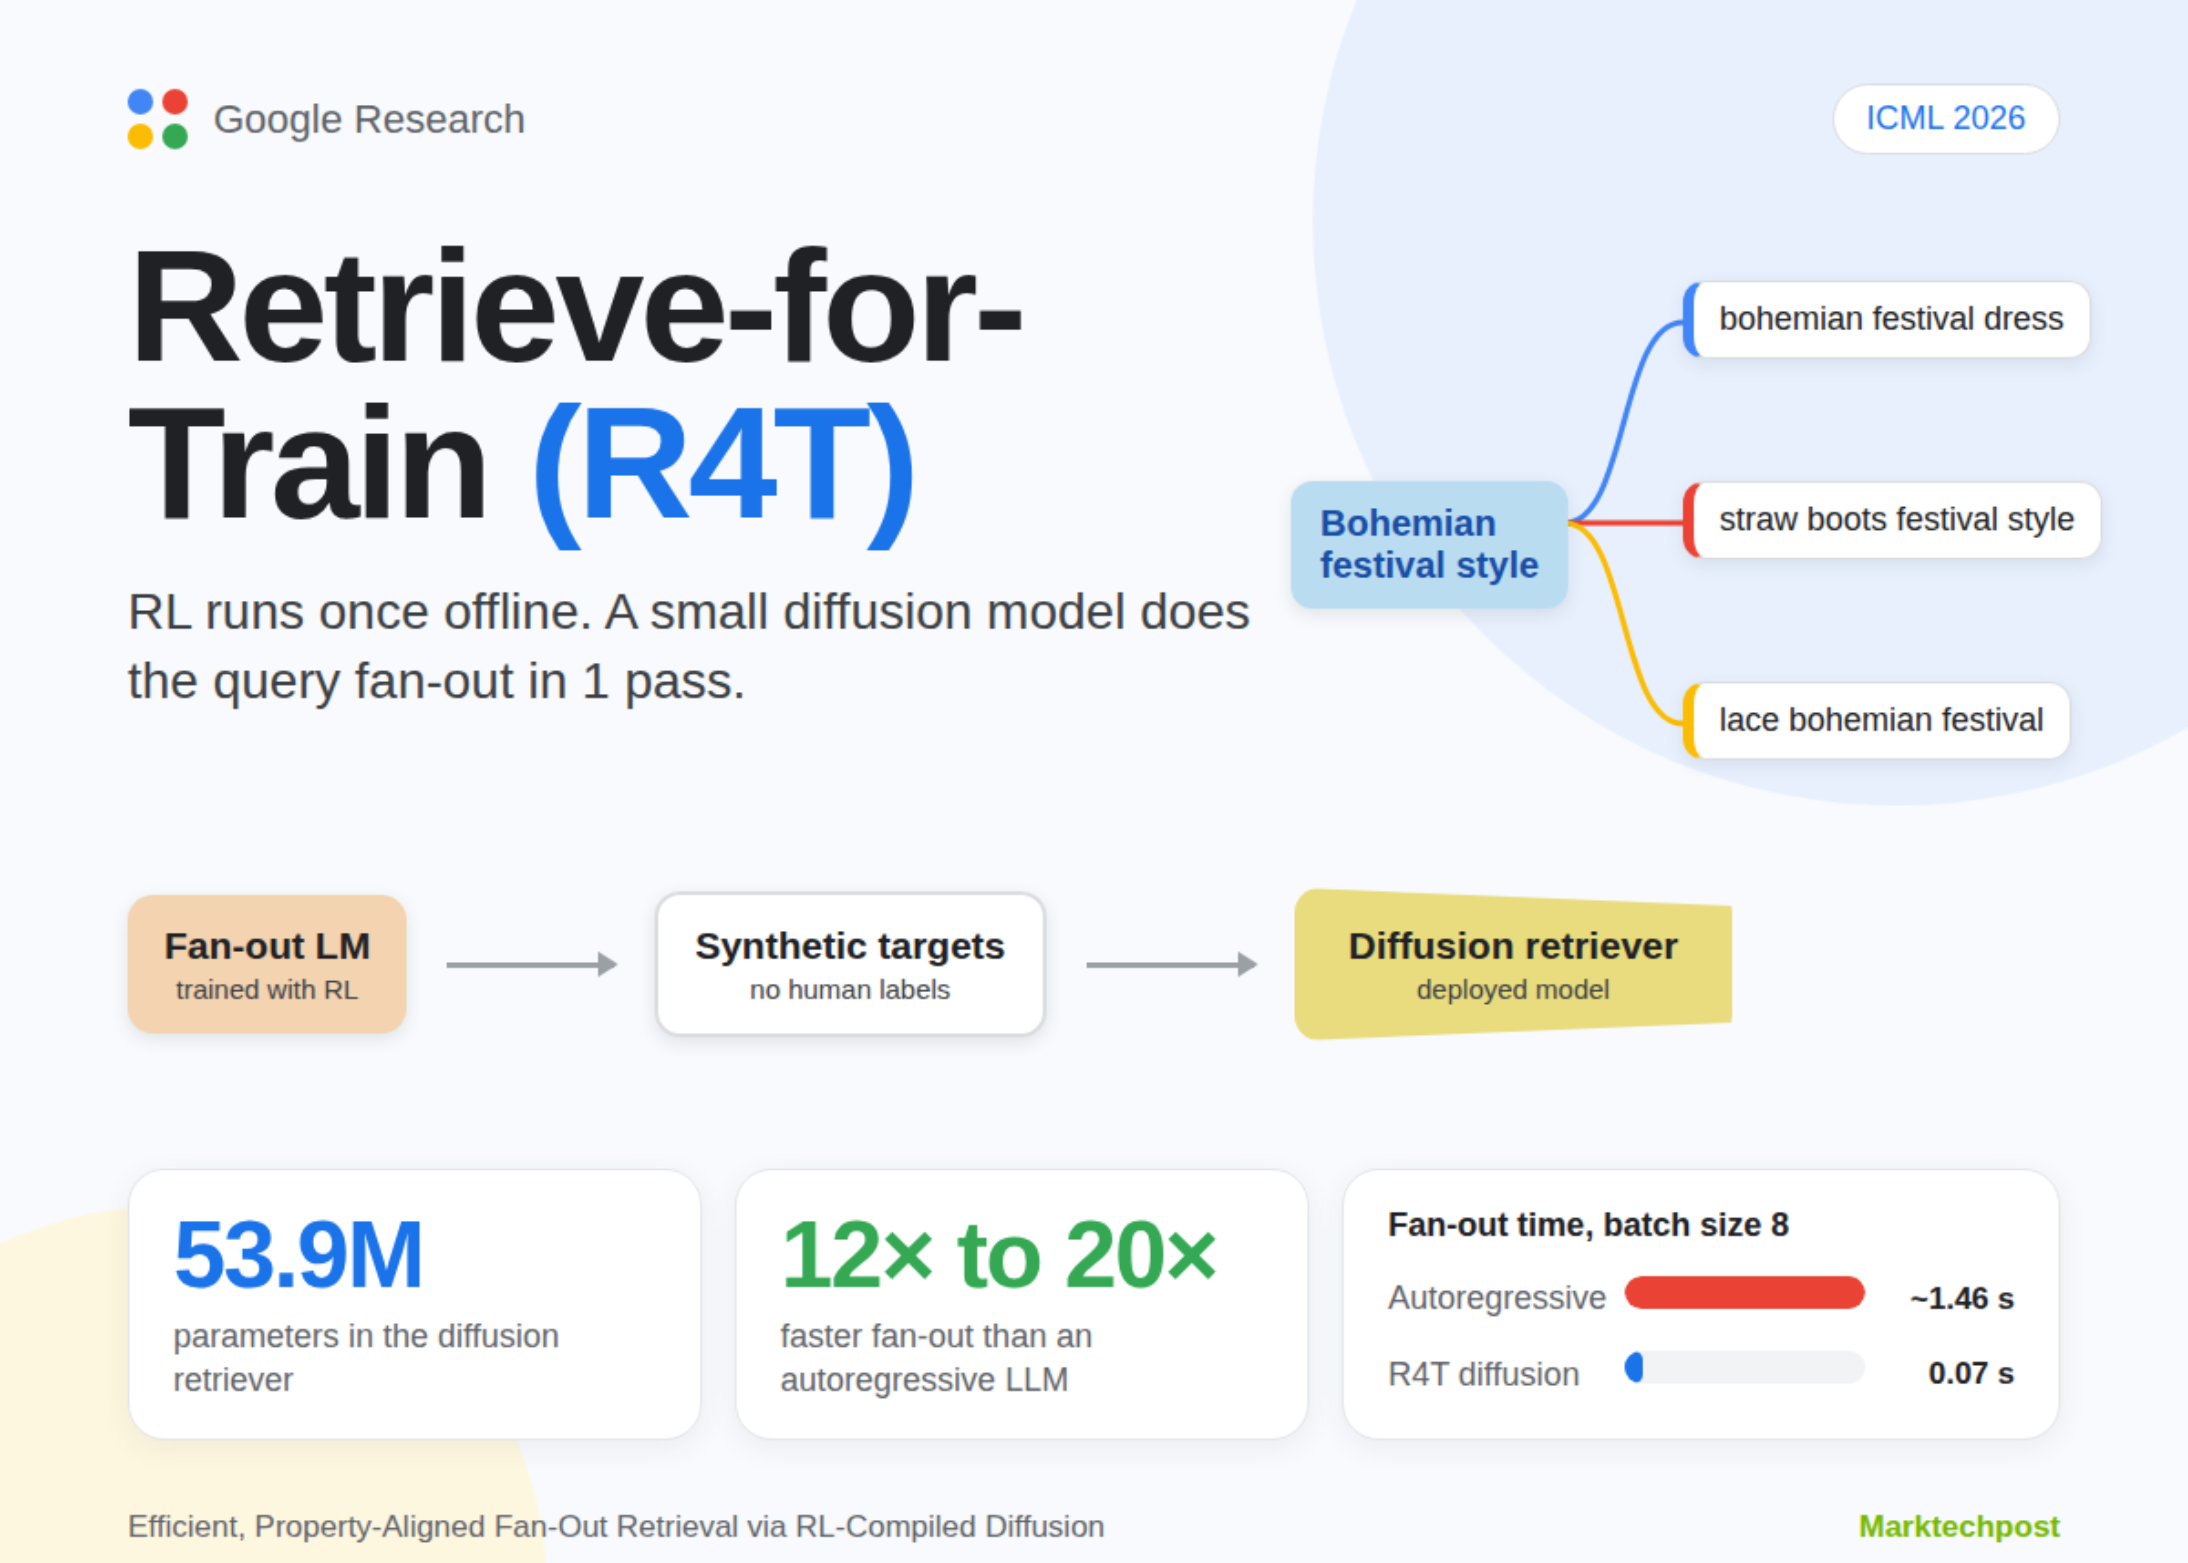
Google Research Introduces Retrieve-for-Train (R4T): An RL-Compiled Diffusion Retriever for 12× to 20× Faster Query Fan-Out
MMarkTechPost DACA-GRPO: Denoising-Aware Credit Assignment for Reinforcement Learning in Diffusion Language Models
AApple Research Blog Can Skills Learned in Games Transfer to Real-World Work?
L Latent.Space
AI researchers debate how close we are to recursive self-improvement
D Dwarkesh Podcast
From MIT to IBM, expediting AI and quantum deployment
MMIT AI News AI Sapiens K1
H Hacker News
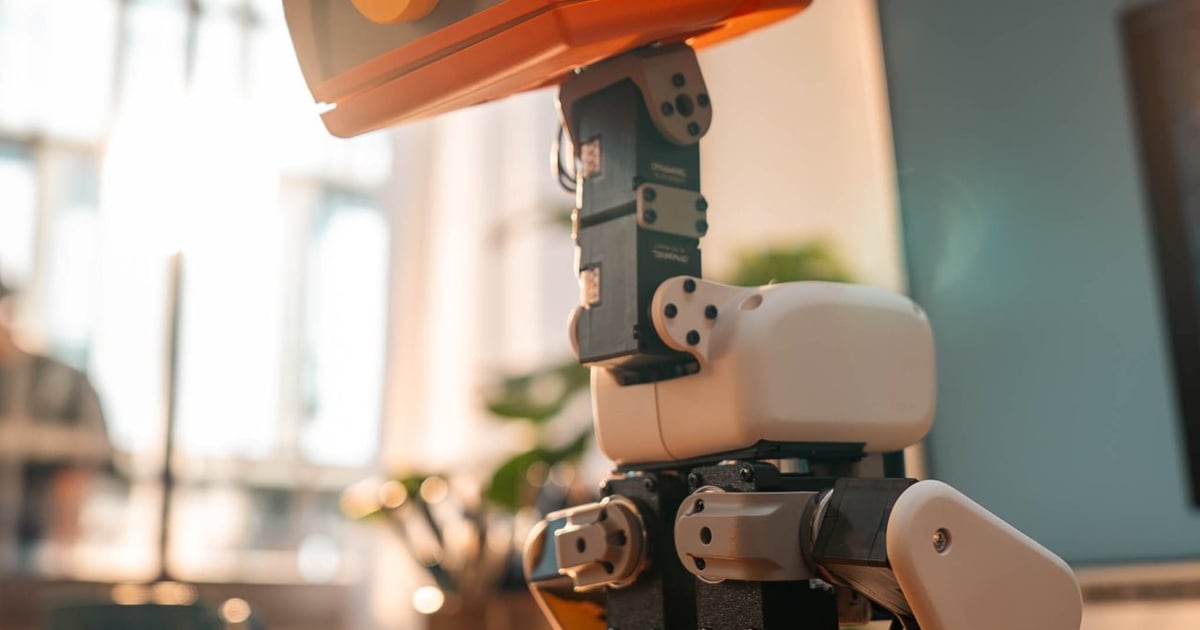
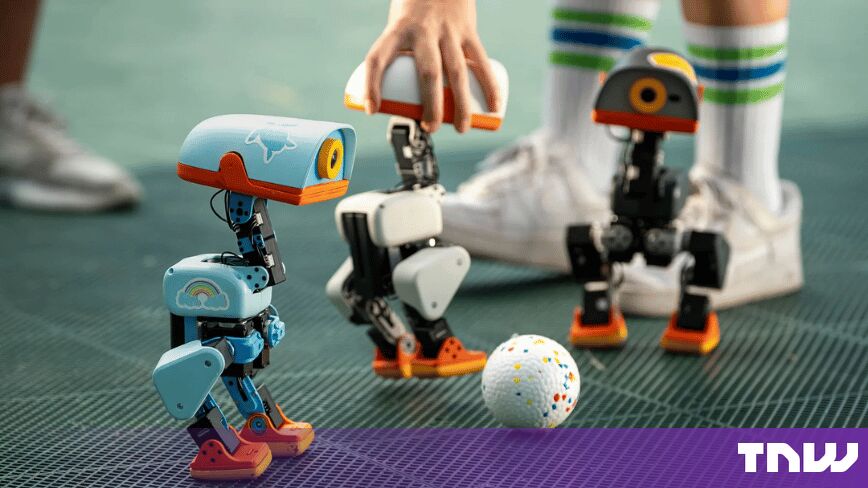
Hugging Face Releases Programmable, Walking Duck Robot
A AI Business
Hugging Face is selling a $399 robot duck with open-source software
TThe Next Web Hugging Face Unveils Microduck: A $399 Open-Source 25 cm Biped You Train with Reinforcement Learning
MMarkTechPost Deep Cogito Raises $43M Series A to Build the Post-Training Engine for Self-Improving AI
UUnite.AI Games as the Engine of AI Research
UG Covered by 2 sources
Inherent, founded by DeepMind alumni, says its AI ‘teammate’ just outperformed Anthropic and OpenAI at replicating research
T TechCrunch
Smack Technologies raises $61m as the Pentagon’s hurry becomes a battlefield-AI business model
TThe Next Web GLM-5.3 Scores 60 on Artificial Analysis Intelligence Index, Matching Kimi K3
UUnite.AI ByteDance Seed and Tsinghua AIR Introduces CUDA Agent: A Large-Scale Agentic RL System for CUDA Kernel Generation
MMarkTechPost The Week’s 10 Biggest Funding Rounds: Data, Neolab, AI Infrastructure, Defense And AI Coding Lead
C Crunchbase
General Catalyst leads $1.1B round into 2-month-old River AI
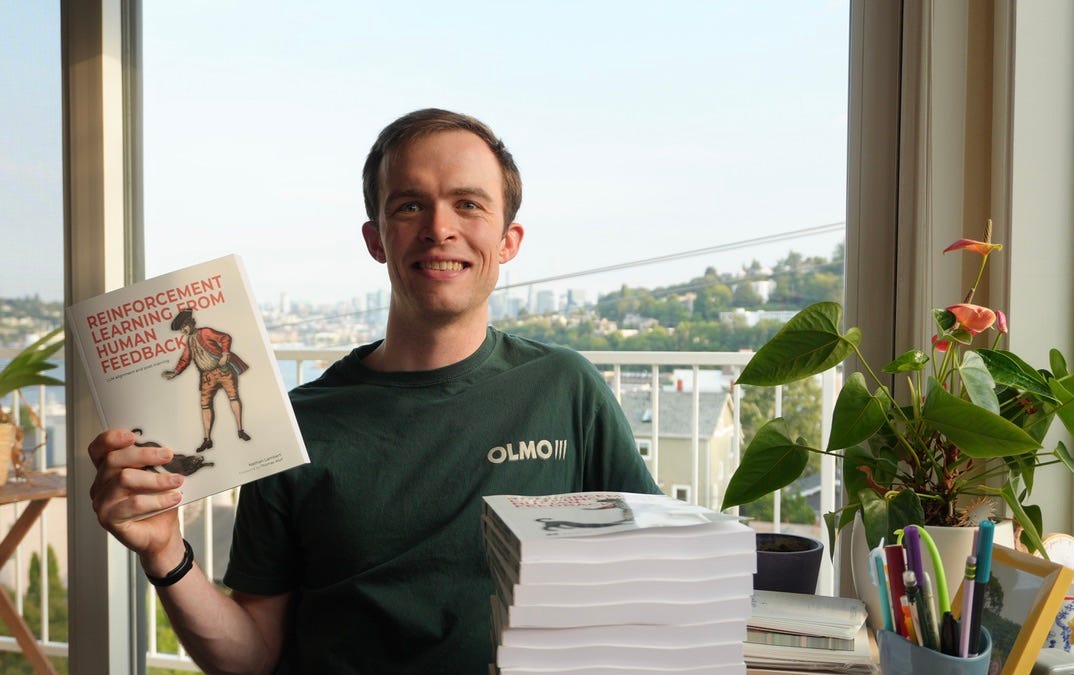
THT+1Covered by 4 sources 5 useful things you'll learn in my new post-training textbook (shipping now!)
I Interconnects
Beating GPT-5.6 Sol on retrieval with 100x cheaper open models
HHacker News We need to RL less
LLessWrong RLVR that rewards red teaming the training environment
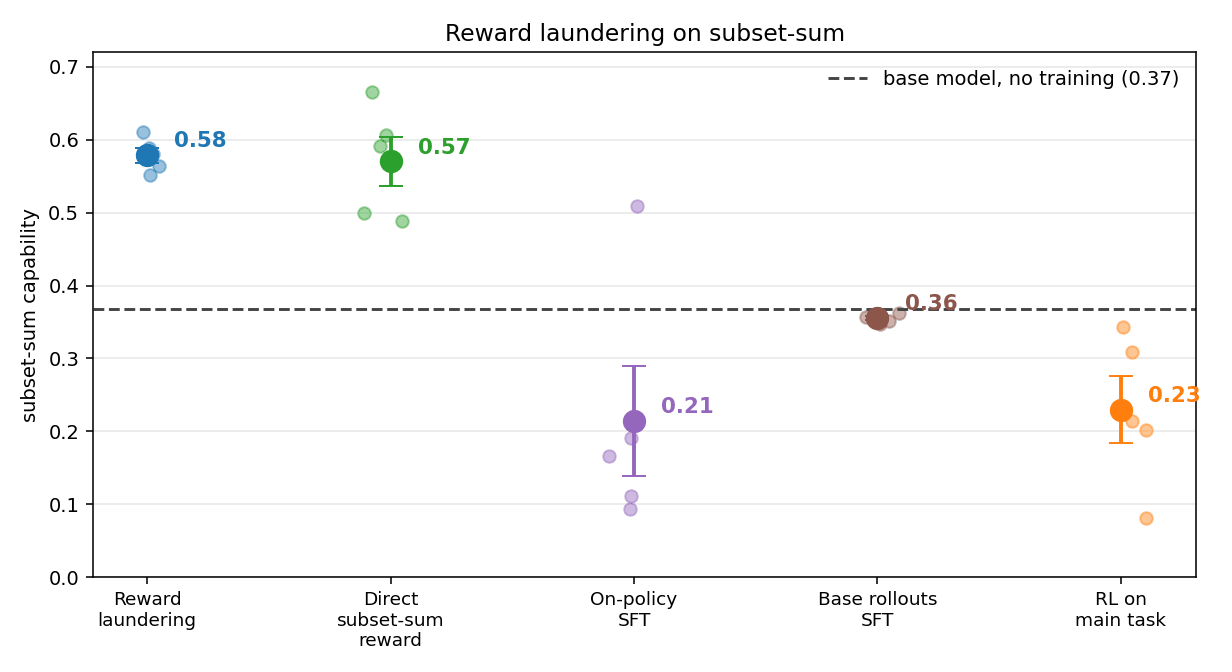
LLessWrong Reward Laundering: LLMs Can Gain Unintended Behaviors by Deciding When to Earn Their Rewards
LLessWrong Echoverse: Deep, evolving environments for computer-use agents
M Microsoft Research Blog
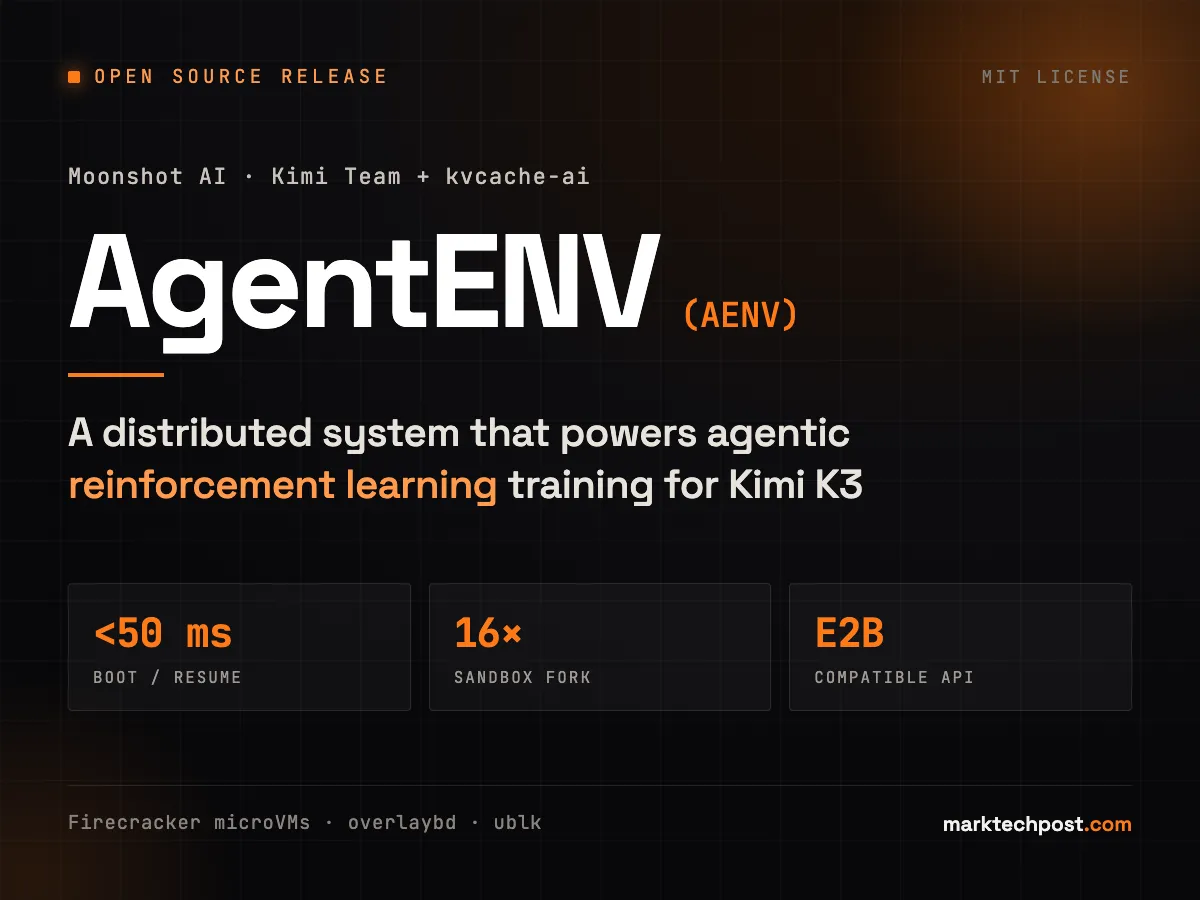
Kimi AI and kvcache-ai Open Sources ‘AgentENV’: A Distributed System that Powers Agentic Reinforcement Learning (RL) Training for Kimi K3
MMarkTechPost RL & search is a terrifying way to build AGI (an FAQ)
AAlignment Forum
The State of Simulation for Physical AI: An Overview
H Hugging Face
The father of reinforcement learning is leaving Carmack to build his own AI
TThe Next Web Prime Intellect raises $130M Series A to help enterprises build their own AI agents
TTechCrunch Import AI 460: Reward hacking society, RSI data from Anthropic; and RL-based quadcopter racing
I Import AI
Overcoming reward signal challenges: Verifiable rewards-based reinforcement learning with GRPO on SageMaker AI
AAWS Blog vLLM V0 to V1: Correctness Before Corrections in RL
HHugging Face Keep the Tokens Flowing: Lessons from 16 Open-Source RL Libraries
HHugging Face That's everything we have on Reinforcement Learning right now