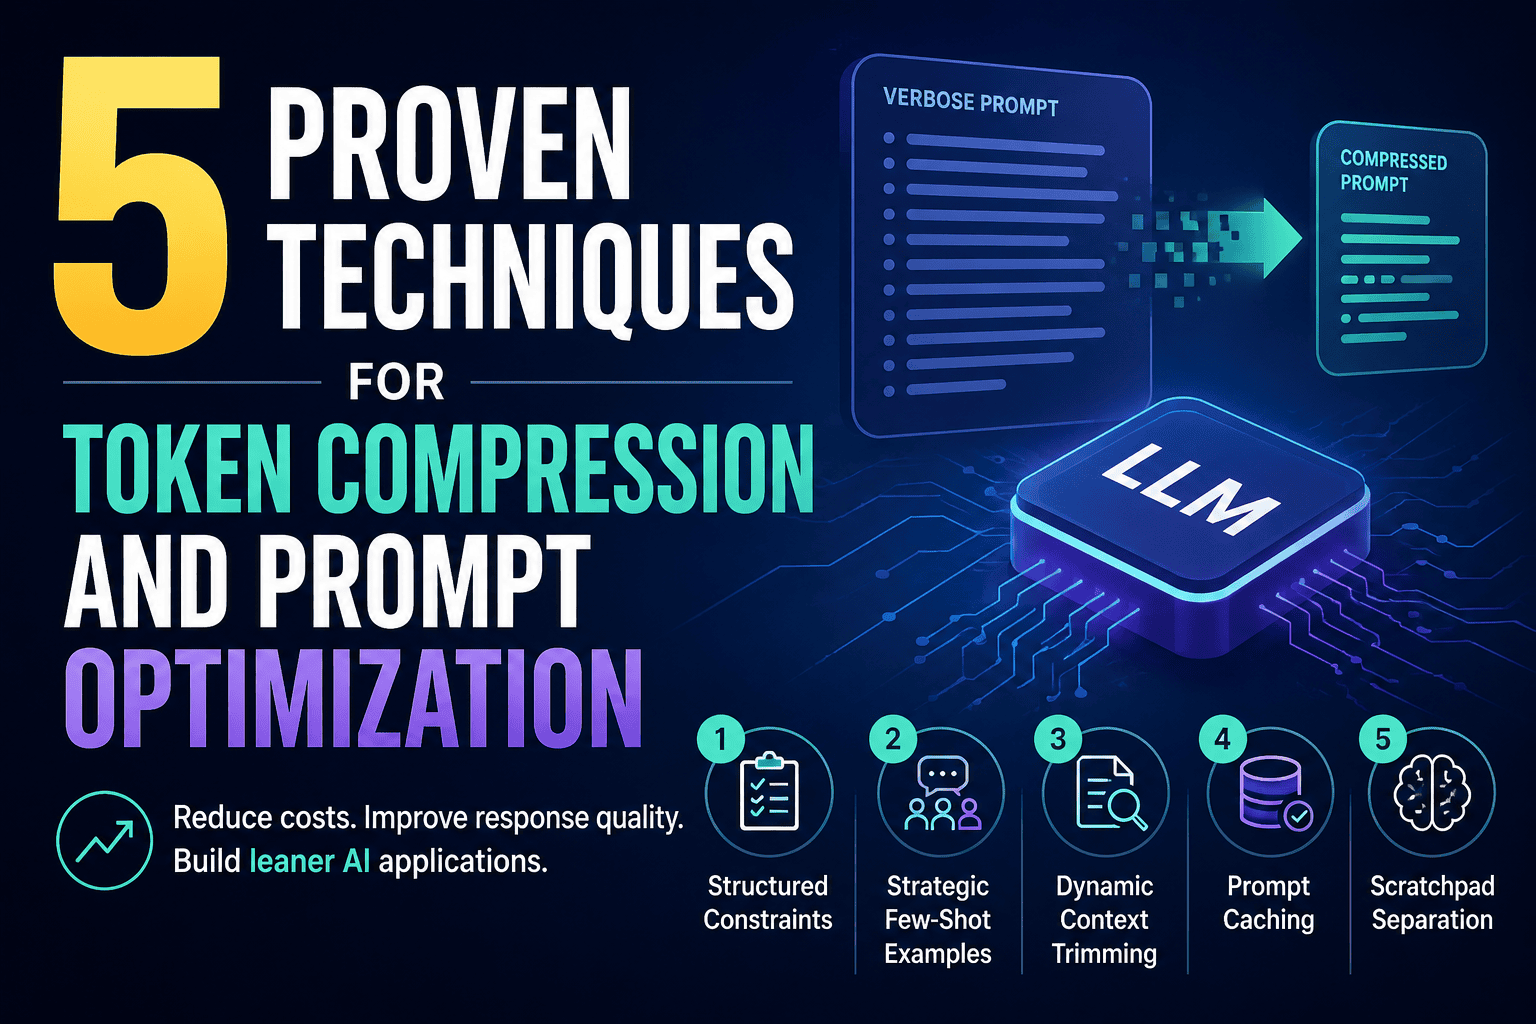
5 Proven Techniques for Token Compression and Prompt Optimization
KDnuggets
Read the full articleToken compression and prompt optimization reduce token usage and improve large language model responses. Techniques include replacing verbose instructions with structured constraints, limiting few-shot examples to three to five, and dynamically trimming context for long inputs.