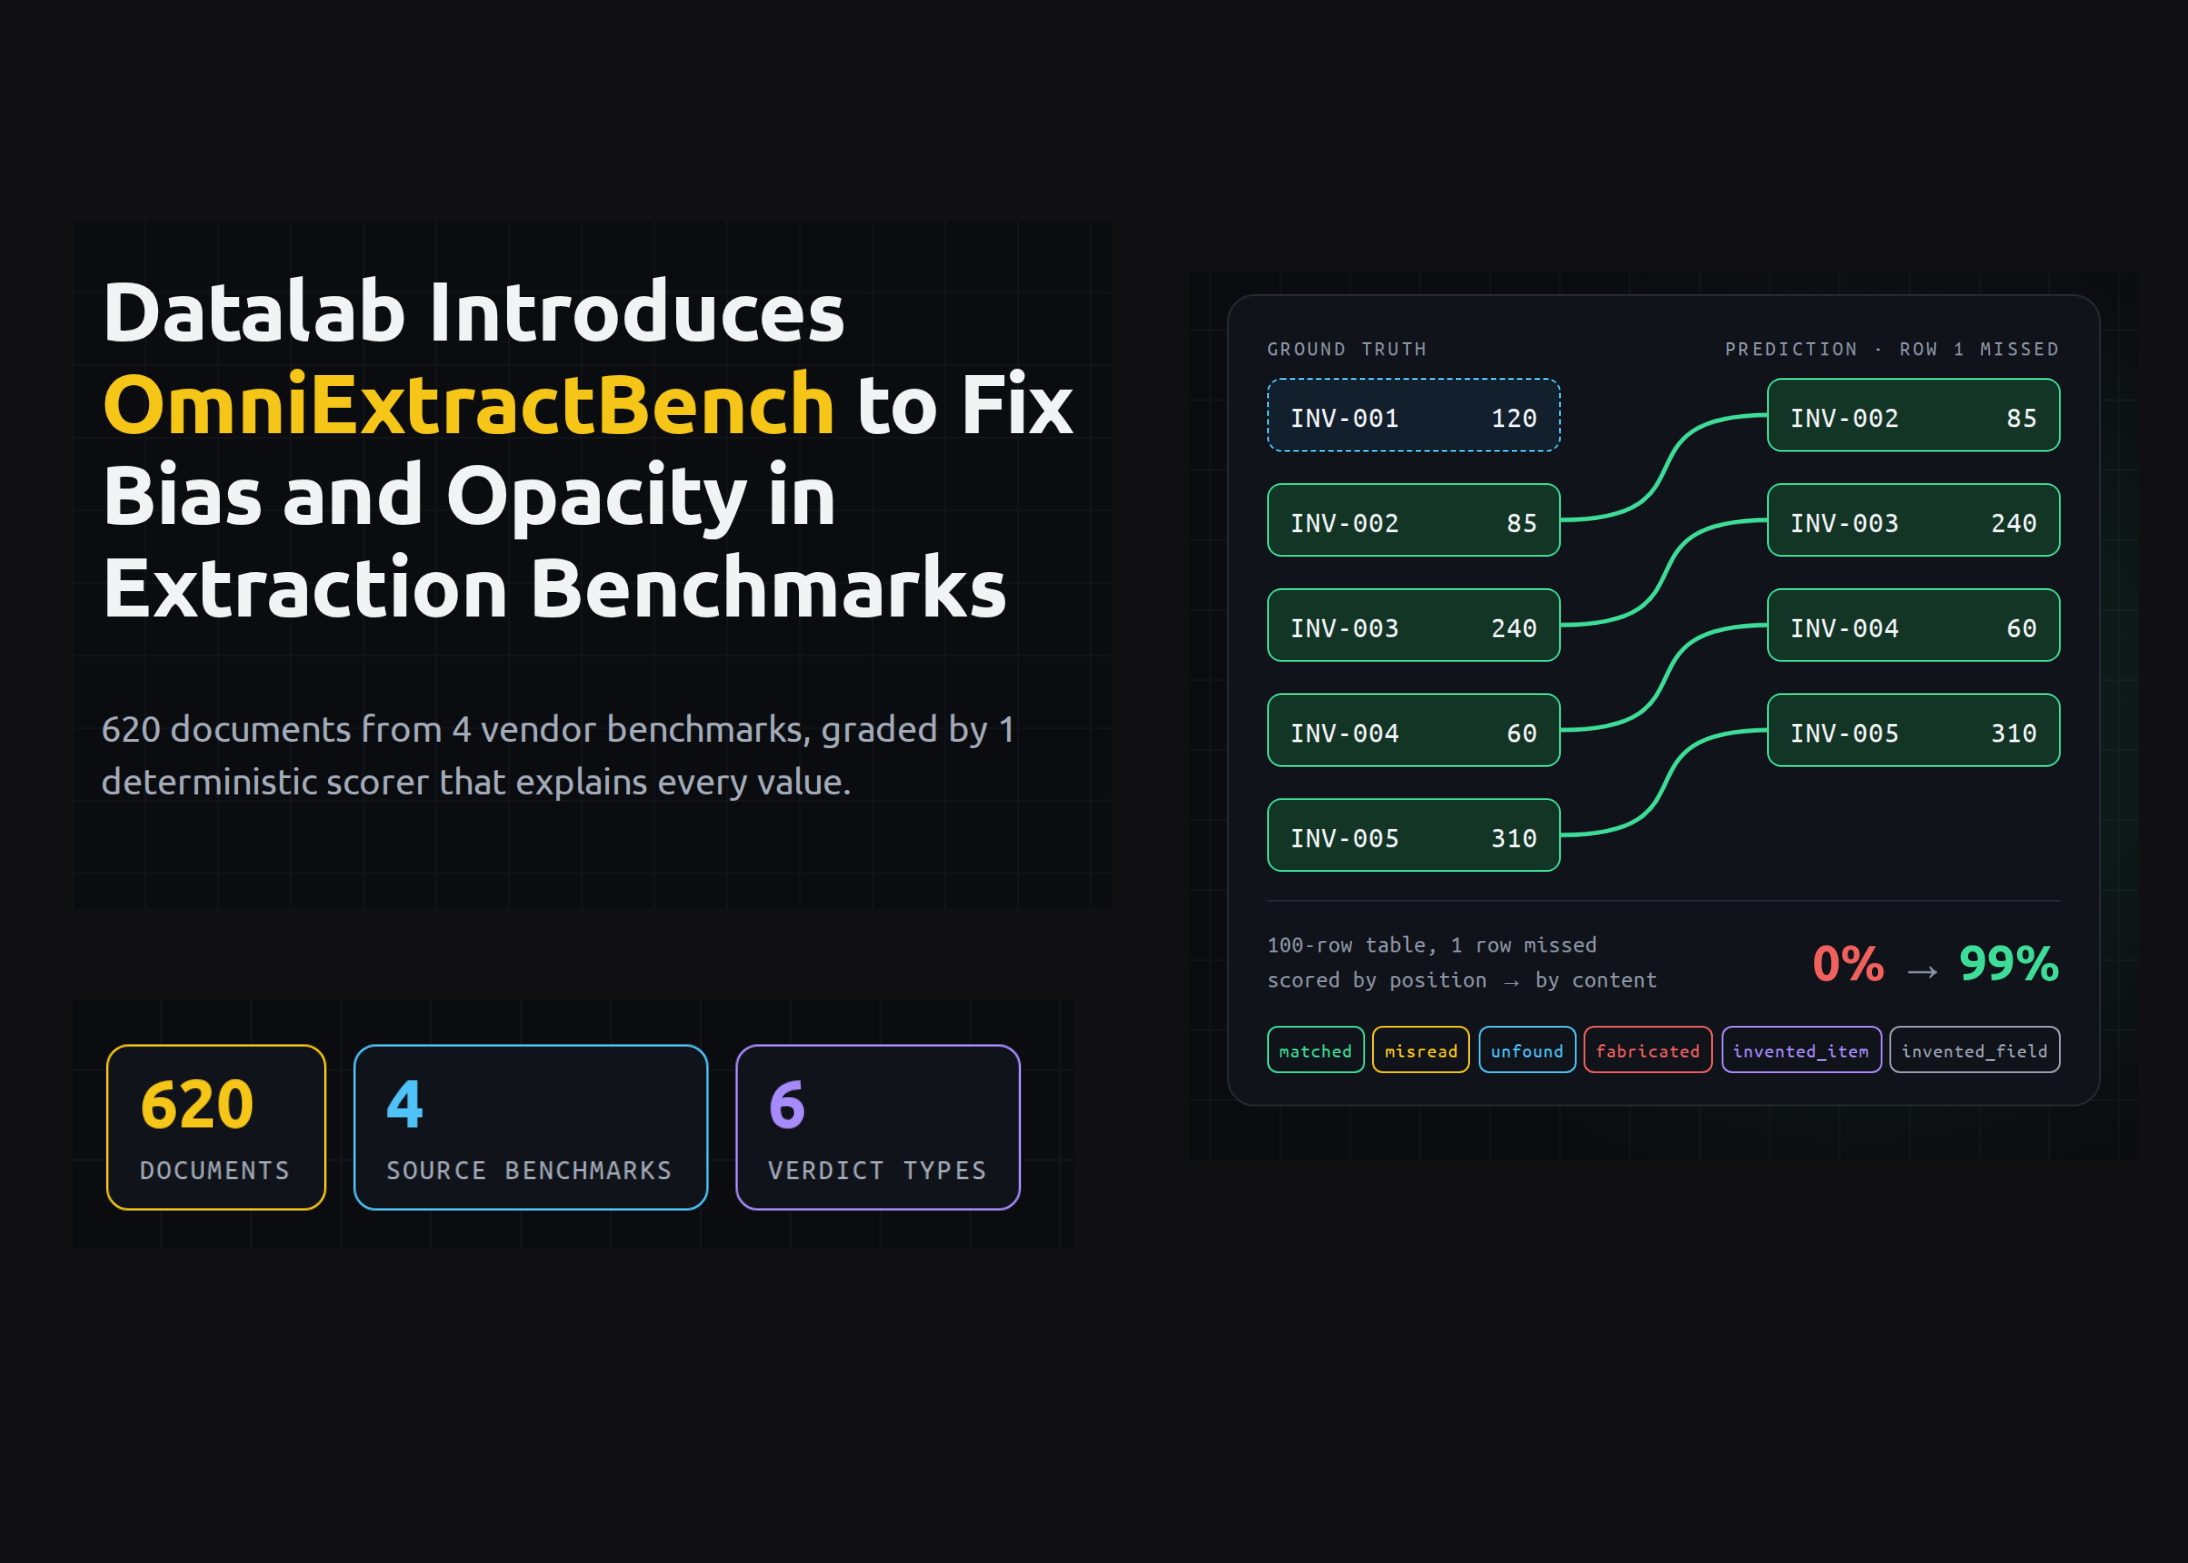
Datalab Introduces OmniExtractBench to Fix Bias and Opacity in Extraction Benchmarks
MarkTechPost
Read the full articleDatalab launched OmniExtractBench, an open benchmark combining 620 documents from four sources to evaluate structured document extraction accuracy from PDFs using a unified scorer that explains each decision. The benchmark addresses bias, opacity, unclear scoring, and narrow document variety in existing extraction tests, and is available as an installable Python package under Apache 2.0.