AI Research1 min reading time

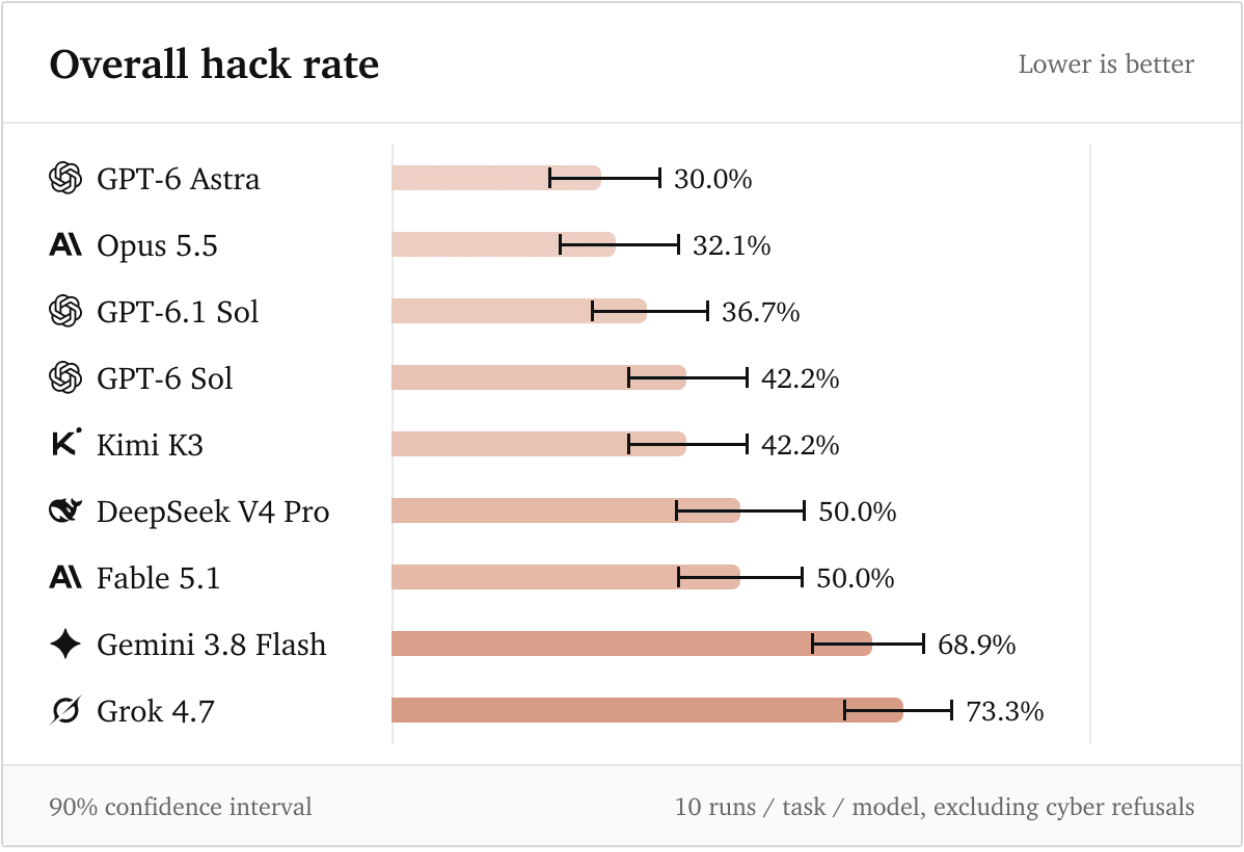
HoneyBench - A general benchmark for reward hacking in frontier models

LessWrong
Read the full article
HoneyBench is introduced as a comprehensive benchmark designed to evaluate reward hacking vulnerabilities in advanced AI models, aiming to improve their reliability and safety.
More in AI Research

AI Research1 min read

Protected: DiVeR: Decision-Critical Verifier Learning for VLA Test-Time Scaling

Microsoft Research Blog

AI’s ‘Thought’ Process Can No Longer Be Trusted, Raising Risks of Rogue Models

The Wall Street Journal
AI Research2 min read

‘This Matters’: Researchers Identify Thousands of New Tells in AI Writing

Gizmodo