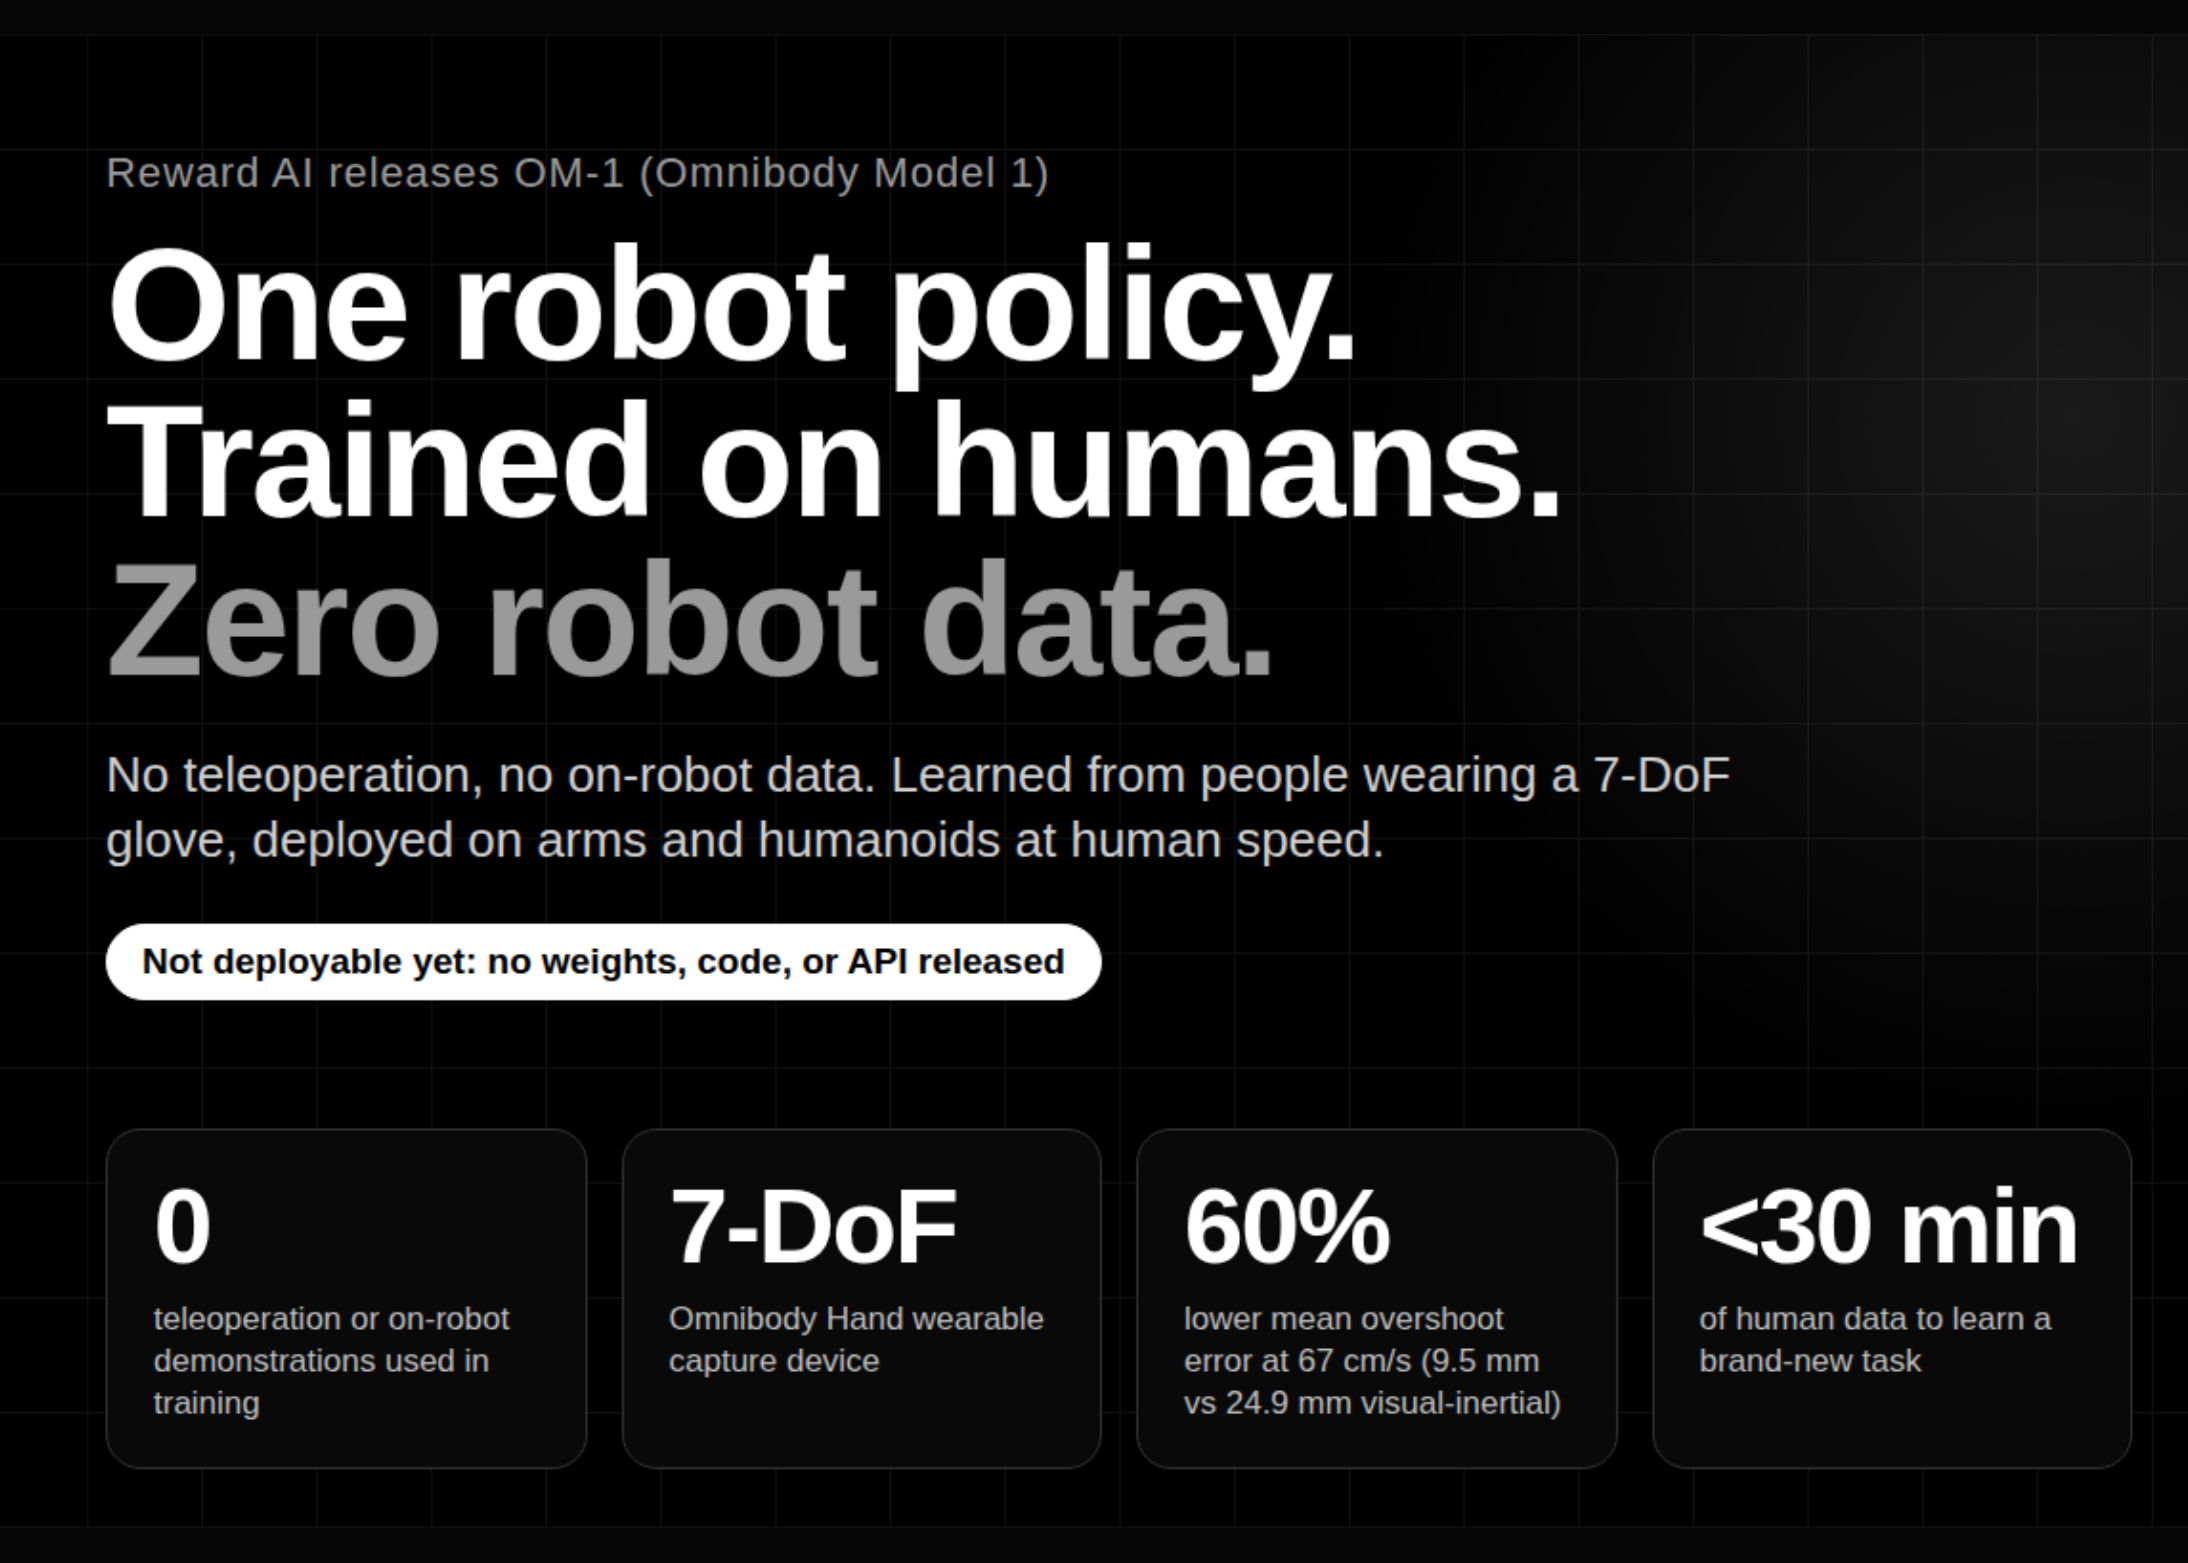
Reward AI Releases OM-1: A Robot Policy Trained on Human Demonstrations Only, With No Teleoperation or On-Robot Data
MarkTechPost
Read full postReward AI has unveiled OM-1, a general-purpose robot manipulation policy trained solely on human demonstrations using a sensorized glove, without teleoperation or robot data. OM-1 runs on various robot bodies at human speed but is currently an internal model with no public release. The approach aims to generalize manipulation skills across different robot embodiments by integrating capture, learning, and control in one pipeline.